

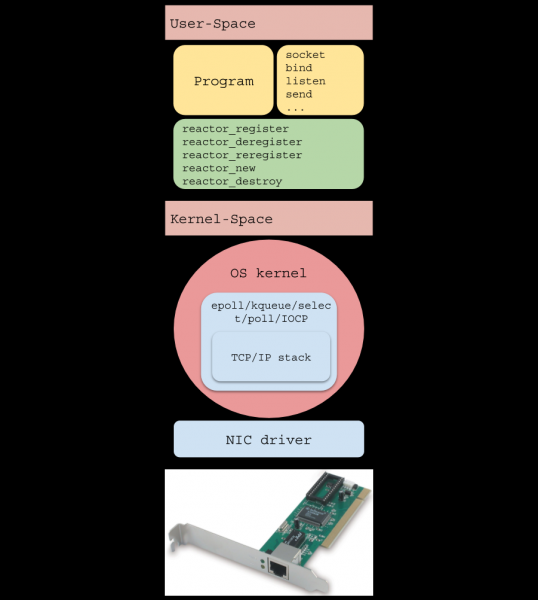
Introduction
(single-threaded ) is a pattern for writing high-load software used in many popular solutions:
- …
In this article, we will explore the inner workings of the I/O reactor and its principle of operation, write an implementation in fewer than 200 lines of code, and make a simple HTTP server handle over 40 million requests per minute.
Preface
- The article is written to help understand the functioning of the I/O reactor and thereby realize the risks involved in its usage.
- To grasp the article, knowledge of the basics is required and a bit of experience in developing network applications.
- All the code is written in C strictly according to thenote: long PDF) for Linux and is available at .
Why is this needed?
With the rise of the Internet, web servers needed to handle a large number of connections simultaneously, which led to the testing of two approaches: blocking I/O with a large number of OS threads and non-blocking I/O in combination with an event notification system, also known as a 'system selector' (///etc).
The first approach involved creating a new OS thread for each incoming connection. Its drawback is poor scalability: the operating system has to perform many and They are expensive operations and can lead to a lack of available RAM when there are a significant number of connections.
A modified version allocates (thread pool), thus not allowing the system to crash during execution, but it also introduces a new problem: if the thread pool is blocking lengthy read operations at a given time, other sockets that are ready to receive data will not be able to do so.
The second approach uses (system selector), which is provided by the OS. This article discusses the most common type of system selector based on notifications (events) regarding readiness for I/O operations rather than on A simplified example of its usage can be represented by the following flowchart:
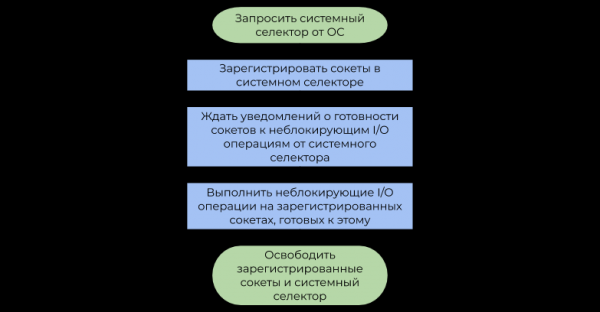
The difference between these approaches is as follows:
- Blocking I/O operations suspend the user thread. until, until the OS properly does not incoming into a stream of bytes (, data receiving) or there is not enough space freed in the write buffers for subsequent sending through (data sending).
- The system selector after some time notifies the program that the OS already has defragmented IP packets (TCP, data receiving) or enough space in the write buffers already is available (data sending).
In summary, reserving the OS stream for each I/O is a waste of computational power, as streams are actually not engaged in useful work (this is where the term ). The system selector solves this problem by allowing the user program to utilize CPU resources much more efficiently.
The I/O reactor model
acts as a layer between the system selector and user code. Its operating principle is described by the following flowchart:
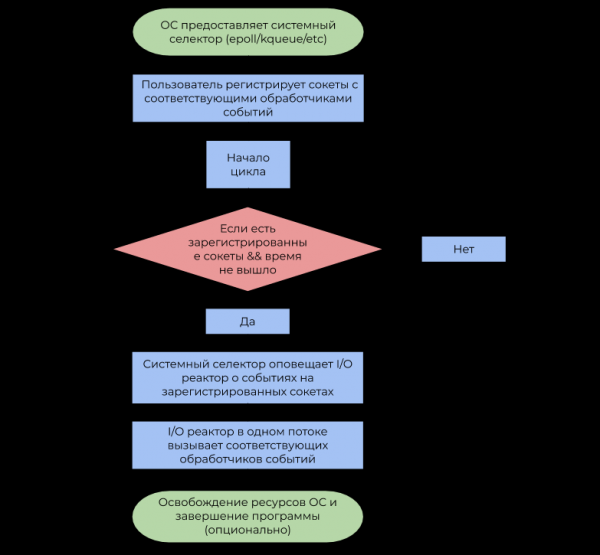
- Let me remind you that an event is a notification that a particular socket is able to perform a non-blocking I/O operation.
- An event handler is a function called by the I/O reactor when an event is received, which then performs a non-blocking I/O operation.
It is important to note that the I/O reactor is by definition single-threaded, but there is nothing to prevent using the concept in a multi-threaded environment regarding 1 thread: 1 reactor, thus utilizing all CPU cores.
Implementation
We will place the public interface in the file , and the implementation in . reactor.h will consist of the following declarations:
Show declarations in reactor.h
typedef struct reactor Reactor;

/*
 * A pointer to the function that will be called by the I/O reactor when an
 * event is received from the system selector.
 */
typedef void (*Callback)(void *arg, int fd, uint32_t events);

/*
 * Returns `NULL` in case of an error, a non-`NULL` pointer to `Reactor` otherwise.
 */
Reactor *reactor_new(void);

/*
 * Releases the system selector, all currently registered sockets,
 * and the I/O reactor itself.
 *
 * The following functions return -1 on error, 0 on success.
 */
int reactor_destroy(Reactor *reactor);

int reactor_register(const Reactor *reactor, int fd, uint32_t interest,
                     Callback callback, void *callback_arg);
int reactor_deregister(const Reactor *reactor, int fd);
int reactor_reregister(const Reactor *reactor, int fd, uint32_t interest,
                       Callback callback, void *callback_arg);

/*
 * Starts the event loop with a timeout of `timeout`.
 *
 * This function will yield control to the calling code if the allotted time has expired
 * or if there are no registered sockets.
 */
int reactor_run(const Reactor *reactor, time_t timeout);
The I/O reactor structure consists of a selector and , which maps each socket to CallbackData (a structure containing the event handler and its user argument).
Show Reactor and CallbackData
struct reactor {
    int epoll_fd;
    GHashTable *table; // (int, CallbackData)
};

typedef struct {
    Callback callback;
    void *arg;
} CallbackData;
Note that we utilized the ability to handle a by pointer. In reactor.h we declare the structure reactor, then moving this task to the section reactor.c and define it, thereby preventing the user from explicitly modifying its fields. This is one of the patterns of , fitting neatly into the semantics of C.
Features reactor_register, reactor_deregister and reactor_reregister update the list of interested sockets and their corresponding event handlers in the system selector and the hash table.
Show registration functions
#define REACTOR_CTL(reactor, op, fd, interest)
    if (epoll_ctl(reactor->epoll_fd, op, fd,
                  &(struct epoll_event){.events = interest,
                                        .data = {.fd = fd}}) == -1) {
        perror("epoll_ctl");
        return -1;
    }

int reactor_register(const Reactor *reactor, int fd, uint32_t interest,
                     Callback callback, void *callback_arg) {
    REACTOR_CTL(reactor, EPOLL_CTL_ADD, fd, interest)
    g_hash_table_insert(reactor->table, int_in_heap(fd),
                        callback_data_new(callback, callback_arg));
    return 0;
}

int reactor_deregister(const Reactor *reactor, int fd) {
    REACTOR_CTL(reactor, EPOLL_CTL_DEL, fd, 0)
    g_hash_table_remove(reactor->table, &fd);
    return 0;
}

int reactor_reregister(const Reactor *reactor, int fd, uint32_t interest,
                       Callback callback, void *callback_arg) {
    REACTOR_CTL(reactor, EPOLL_CTL_MOD, fd, interest)
    g_hash_table_insert(reactor->table, int_in_heap(fd),
                        callback_data_new(callback, callback_arg));
    return 0;
}
After the I/O reactor intercepts an event with the descriptor fd, it calls the corresponding event handler, passing it fd, of generated events and a user pointer to void.
Show the reactor_run() function
int reactor_run(const Reactor *reactor, time_t timeout) {
    int result;
    struct epoll_event *events;
    if ((events = calloc(MAX_EVENTS, sizeof(*events))) == NULL)
        abort();

    time_t start = time(NULL);

    while (true) {
        time_t passed = time(NULL) - start;
        int nfds =
            epoll_wait(reactor->epoll_fd, events, MAX_EVENTS, timeout - passed);

        switch (nfds) {
        // Error
        case -1:
            perror("epoll_wait");
            result = -1;
            goto cleanup;
        // Timeout
        case 0:
            result = 0;
            goto cleanup;
        // Successful operation
        default:
            // Call event handlers
            for (int i = 0; i table, &fd);
                callback->callback(callback->arg, fd, events[i].events);
            }
        }
    }

cleanup:
    free(events);
    return result;
}
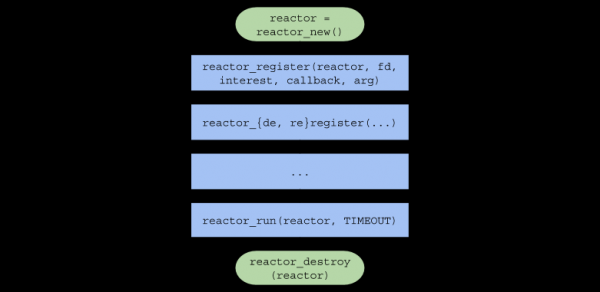
In conclusion, the chain of function calls in the user code will look like this:
Single-threaded server
To test the I/O reactor under heavy load, we will write a simple HTTP web server that responds with an image to any request.
Brief overview of the HTTP protocol
is a protocol , primarily used for interaction between the server and the browser.
HTTP can be easily used over protocol , sending and receiving messages formatted as defined by .
Request format
CRLF
CRLF
CRLF
CRLF CRLF CRLFis a sequence of two characters:randn, separating the first line of the request, headers, and body.<КОМАНДА>is one ofCONNECT,DELETE,GET,HEAD,OPTIONS,PATCH,POST,PUT,TRACE. The browser will send our server a commandGET, meaning 'Send me the content of the file.'<URI>— . For example, if URI =/index.html, then the client is requesting the homepage of the site.<ВЕРСИЯ HTTP>is the version of the HTTP protocol in the formatHTTP/X.Y. The most commonly used version today isHTTP/1.1.:, sent to the server for further analysis.<ДАННЫЕ>is the data required by the server to perform the operation. Often, this is just or any other format.
Response format
CRLF
CRLF
CRLF
CRLF CRLF
<КОД СТАТУСА>— this number represents the result of the operation. Our server will always return a status of 200 (successful operation).<ОПИСАНИЕ СТАТУСА>— a string representation of the status code. For status code 200, it isOK.Content-Length(file size) andContent-Type: text/html(type of returned data).<ДАННЫЕ>— the data requested by the user. In our case, it is the path to the image in .
File (single-threaded server) includes the file , which contains the following function prototypes:
Show function prototypes in common.h
/*
 * Обработчик событий, который вызовется после того, как сокет будет
 * готов принять новое соединение.
 */
static void on_accept(void *arg, int fd, uint32_t events);

/*
 * Обработчик событий, который вызовется после того, как сокет будет
 * готов отправить HTTP ответ.
 */
static void on_send(void *arg, int fd, uint32_t events);

/*
 * Обработчик событий, который вызовется после того, как сокет будет
 * готов принять часть HTTP запроса.
 */
static void on_recv(void *arg, int fd, uint32_t events);

/*
 * Переводит входящее соединение в неблокирующий режим.
 */
static void set_nonblocking(int fd);

/*
 * Печатает переданные аргументы в stderr и выходит из процесса с
 * кодом `EXIT_FAILURE`.
 */
static noreturn void fail(const char *format, ...);

/*
 * Возвращает файловый дескриптор сокета, способного принимать новые
 * TCP соединения.
 */
static int new_server(bool reuse_port);
Also described is the functional macro SAFE_CALL() and the function fail(). The macro compares the value of the expression with an error, and if the condition is met, it calls the function fail():
#define SAFE_CALL(call, error)
    do {
        if ((call) == error) {
            fail("%s", #call);
        }
    } while (false)
Function fail() prints the passed arguments to the terminal (like ) and terminates the program with the code EXIT_FAILURE:
static noreturn void fail(const char *format, ...) {
    va_list args;
    va_start(args, format);
    vfprintf(stderr, format, args);
    va_end(args);
    fprintf(stderr, ": %sn", strerror(errno));
    exit(EXIT_FAILURE);
}
Function new_server() returns a file descriptor for the "server" socket created by the system calls , and and capable of accepting incoming connections in non-blocking mode.
Show function new_server()
static int new_server(bool reuse_port) {
    int fd;
    SAFE_CALL((fd = socket(AF_INET, SOCK_STREAM | SOCK_NONBLOCK, IPPROTO_TCP)),
              -1);

    if (reuse_port) {
        SAFE_CALL(
            setsockopt(fd, SOL_SOCKET, SO_REUSEPORT, &(int){1}, sizeof(int)),
            -1);
    }

    struct sockaddr_in addr = {.sin_family = AF_INET,
                               .sin_port = htons(SERVER_PORT),
                               .sin_addr = {.s_addr = inet_addr(SERVER_IPV4)},
                               .sin_zero = {0}};

    SAFE_CALL(bind(fd, (struct sockaddr *)&addr, sizeof(addr)), -1);
    SAFE_CALL(listen(fd, SERVER_BACKLOG), -1);
    return fd;
}- Note that the socket is initially created in non-blocking mode using the flag
SOCK_NONBLOCK, so that in the functionon_accept()the system callaccept()does not block the execution of the thread. - If
reuse_portequal totrue, this function configures the socket with the option using , to use the same port in a multithreaded environment (see the section "Multithreaded Server").
The event handler on_accept() is called after the OS generates an event EPOLLIN, in this case indicating that a new connection can be accepted. on_accept() accepts a new connection, switches it to non-blocking mode, and registers it with the event handler on_recv() in the I/O reactor.
Show function on_accept()
static void on_accept(void *arg, int fd, uint32_t events) {
    int incoming_conn;
    SAFE_CALL((incoming_conn = accept(fd, NULL, NULL)), -1);
    set_nonblocking(incoming_conn);
    SAFE_CALL(reactor_register(reactor, incoming_conn, EPOLLIN, on_recv,
                               request_buffer_new()),
              -1);
}
The event handler on_recv() is called after the OS generates an event EPOLLIN, in this case meaning that the connection registered on_accept(), is ready to accept data.
on_recv() reads data from the connection until the entire HTTP request is received, then it registers the handler on_send() to send the HTTP response. If the client terminates the connection, the socket is deregistered and closed using .
Show function on_recv()
static void on_recv(void *arg, int fd, uint32_t events) {
    RequestBuffer *buffer = arg;

    // Receive input until recv returns 0 or an error
    ssize_t nread;
    while ((nread = recv(fd, buffer->data + buffer->size,
                         REQUEST_BUFFER_CAPACITY - buffer->size, 0)) > 0)
        buffer->size += nread;

    // Client terminated the connection
    if (nread == 0) {
        SAFE_CALL(reactor_deregister(reactor, fd), -1);
        SAFE_CALL(close(fd), -1);
        request_buffer_destroy(buffer);
        return;
    }

    // read returned an error other than a blocking call
    if (errno != EAGAIN && errno != EWOULDBLOCK) {
        request_buffer_destroy(buffer);
        fail("read");
    }

    // A complete HTTP request from the client has been received. Now we register the event handler
    // for sending data
    if (request_buffer_is_complete(buffer)) {
        request_buffer_clear(buffer);
        SAFE_CALL(reactor_reregister(reactor, fd, EPOLLOUT, on_send, buffer),
                  -1);
    }
}
The event handler on_send() is called after the OS generates an event EPOLLOUT, meaning that the registered connection on_recv(), is ready to send data. This function sends an HTTP response containing HTML with an image to the client, and then changes the event handler back to on_recv().
Show function on_send()
static void on_send(void *arg, int fd, uint32_t events) {
    const char *content = "<img "
 "src="https://habrastorage.org/webt/oh/wl/23/"
                          "ohwl23va3b-dioerobq_mbx4xaw.jpeg">";
    char response[1024];
    sprintf(response,
            "HTTP/1.1 200 OK" CRLF "Content-Length: %zd" CRLF "Content-Type: "
            "text/html" DOUBLE_CRLF "%s",
            strlen(content), content);

    SAFE_CALL(send(fd, response, strlen(response), 0), -1);
    SAFE_CALL(reactor_reregister(reactor, fd, EPOLLIN, on_recv, arg), -1);
}
And finally, in the file http_server.c, in the function main() we create an I/O reactor using reactor_new(), create a server socket and register it, run the reactor with reactor_run() for exactly one minute, then free the resources and exit the program.
Show http_server.c
#include "reactor.h"

static Reactor *reactor;

#include "common.h"

int main(void) {
    SAFE_CALL((reactor = reactor_new()), NULL);
    SAFE_CALL(
        reactor_register(reactor, new_server(false), EPOLLIN, on_accept, NULL),
        -1);
    SAFE_CALL(reactor_run(reactor, SERVER_TIMEOUT_MILLIS), -1);
    SAFE_CALL(reactor_destroy(reactor), -1);
}
Let's check that everything works as it should. We compile (chmod a+x compile.sh && ./compile.sh in the project root) and run the custom server, open in the browser and observe what we expected:
Performance measurement
Show the specifications of my machine
$ screenfetch
 MMMMMMMMMMMMMMMMMMMMMMMMMmds+.        OS: Mint 19.1 tessa
 MMm----::-:///////////////oymNMd+`     Kernel: x86_64 Linux 4.15.0-20-generic
 MMd      /++                -sNMd:    Uptime: 2h 34m
 MMNso/`  dMM    `.::-. .-::.` .hMN:   Packages: 2217
 ddddMMh  dMM   :hNMNMNhNMNMNh: `NMm   Shell: bash 4.4.20
     NMm  dMM  .NMN/+MMM+-/NMN` dMM   Resolution: 1920x1080
     NMm  dMM  -MMm  `MMM   dMM. dMM   DE: Cinnamon 4.0.10
     NMm  dMM  -MMm  `MMM   dMM. dMM   WM: Muffin
     NMm  dMM  .mmd  `mmm   yMM. dMM   WM Theme: Mint-Y-Dark (Mint-Y)
     NMm  dMM`  ..`   ...   ydm. dMM   GTK Theme: Mint-Y [GTK2/3]
     hMM- +MMd/-------...-:sdds  dMM   Icon Theme: Mint-Y
     -NMm- :hNMNNNmdddddddddy/`  dMM   Font: Noto Sans 9
      -dMNs-``-::::-------.``    dMM   CPU: Intel Core i7-6700 @ 8x 4GHz [52.0°C]
       `/dMNmy+/:-------------:/yMMM   GPU: NV136
          ./ydNMMMMMMMMMMMMMMMMMMMMM   RAM: 2544MiB / 7926MiB
             .MMMMMMMMMMMMMMMMMMM
Let's measure the performance of a single-thread server. We'll open two terminals: in one we will run ./http_server, in the other — . After a minute, the following statistics will appear in the second terminal:
$ wrk -c100 -d1m -t8 http://127.0.0.1:18470 -H "Host: 127.0.0.1:18470" -H "Accept-Language: en-US,en;q=0.5" -H "Connection: keep-alive"
Running 1m test @ http://127.0.0.1:18470
  8 threads and 100 connections
  Thread Stats   Avg      Stdev     Max   +/- Stdev
    Latency   493.52us   76.70us  17.31ms   89.57%
    Req/Sec    24.37k     1.81k   29.34k    68.13%
  11657769 requests in 1.00m, 1.60GB read
Requests/sec: 193974.70
Transfer/sec:     27.19MB
Our single-thread server was able to process over 11 million requests per minute, originating from 100 connections. A decent result, but can we improve it?
Multi-threaded server
As mentioned above, an I/O reactor can be created in separate threads, thus utilizing all CPU cores. Let's apply this approach in practice:
Show http_server_multithreaded.c
#include "reactor.h"

static Reactor *reactor;
#pragma omp threadprivate(reactor)

#include "common.h"

int main(void) {
#pragma omp parallel
    {
        SAFE_CALL((reactor = reactor_new()), NULL);
        SAFE_CALL(reactor_register(reactor, new_server(true), EPOLLIN,
                                   on_accept, NULL),
                  -1);
        SAFE_CALL(reactor_run(reactor, SERVER_TIMEOUT_MILLIS), -1);
        SAFE_CALL(reactor_destroy(reactor), -1);
    }
}
Now each thread reactor:
static Reactor *reactor;
#pragma omp threadprivate(reactor)
Note that the argument for the function new_server() is true. This means we assign the server socket the option , to use it in a multi-threaded environment. You can read more about it .
Second round
Now let's measure the performance of the multi-threaded server:
$ wrk -c100 -d1m -t8 http://127.0.0.1:18470 -H "Host: 127.0.0.1:18470" -H "Accept-Language: en-US,en;q=0.5" -H "Connection: keep-alive"
Running 1m test @ http://127.0.0.1:18470
  8 threads and 100 connections
  Thread Stats   Avg      Stdev     Max   +/- Stdev
    Latency     1.14ms    2.53ms  40.73ms   89.98%
    Req/Sec    79.98k    18.07k  154.64k    78.65%
  38208400 requests in 1.00m, 5.23GB read
Requests/sec: 635876.41
Transfer/sec:     89.14MB
The number of processed requests in one minute increased by ~3.28 times! But we were just ~two million short of a round number, let's try to fix that.
First, let's take a look at the statistics generated :
$ sudo perf stat -B -e task-clock,context-switches,cpu-migrations,page-faults,cycles,instructions,branches,branch-misses,cache-misses ./http_server_multithreaded

 Performance counter stats for './http_server_multithreaded':

     242446.314933      task-clock (msec)         #    4,000 CPUs utilized
         1,813,074      context-switches          #    0.007 M/sec
             4,689      cpu-migrations            #    0.019 K/sec
               254      page-faults               #    0.001 K/sec
   895,324,830,170      cycles                    #    3.693 GHz
   621,378,066,808      instructions              #    0.69  insn per cycle
   119,926,709,370      branches                  #  494,653 M/sec
     3,227,095,669      branch-misses             #    2.69% of all branches
           808,664      cache-misses

60.604330670 seconds time elapsed, compiling with -march=native, , increasing the number of hits in , increasing MAX_EVENTS and using EPOLLET did not lead to a significant performance increase. But what will happen if we increase the number of simultaneous connections?
Statistics at 352 simultaneous connections:
$ wrk -c352 -d1m -t8 http://127.0.0.1:18470 -H "Host: 127.0.0.1:18470" -H "Accept-Language: en-US,en;q=0.5" -H "Connection: keep-alive"
Running 1m test @ http://127.0.0.1:18470
  8 threads and 352 connections
  Thread Stats   Avg      Stdev     Max   +/- Stdev
    Latency     2.12ms    3.79ms  68.23ms   87.49%
    Req/Sec    83.78k    12.69k  169.81k    83.59%
  40,006,142 requests in 1.00m, 5.48GB read
Requests/sec: 665789.26
Transfer/sec:     93.34MB
The desired result was achieved, along with an interesting graph showing the relationship between the number of requests processed in 1 minute and the number of connections:
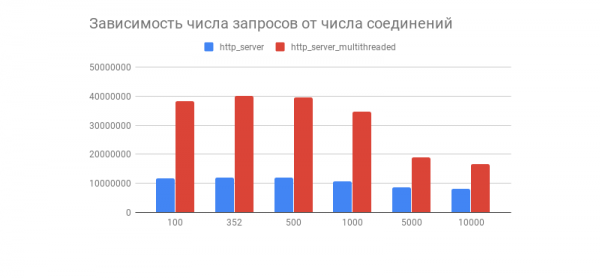
We can see that after a couple of hundred connections, the number of processed requests drops sharply for both servers (this is more noticeable in the multithreaded version). Does this relate to the implementation of the Linux TCP/IP stack? Feel free to share your thoughts on the behavior of the graph and the optimizations of the multithreaded and single-threaded versions in the comments.
How In the comments, this performance test does not show the behavior of the I/O reactor under real loads, as the server almost always interacts with the database, outputs logs, uses cryptography with etc., which results in a non-uniform (dynamic) load. Tests with third-party components will be conducted in the article about the I/O reactor.
Drawbacks of the I/O Reactor
It's important to understand that the I/O reactor is not without its drawbacks, namely:
- Using the I/O reactor in a multithreaded environment is somewhat more complex, as you will have to manage threads manually.
- Practice shows that in most cases the load is uneven, which can lead to one thread being stressed while another is busy with work.
- If one event handler blocks a thread, the system selector will also be blocked, which can lead to hard-to-trace bugs.
These issues are addressed by , often featuring a scheduler that evenly distributes the load across a thread pool, and also provides a more convenient API. More on this will be discussed later in my other article.
Conclusion
With this, our journey from theory straight to profiler output comes to an end.
But we shouldn't stop here, as there are many other interesting approaches to writing network software with varying levels of convenience and speed. Interesting links, in my opinion, are provided below.
Until next time!
Interesting projects
- C
What else to read?
Source: habr.com
