

— a very powerful and convenient mechanism when the same actions are performed "deeper" on related data. However, uncontrolled recursion is a harmful practice that can lead to infinite execution of the process, or (which happens more often) to the "exhaustion" of all available memory..
Databases operate on the same principles — "they said to dig, and I dig".Your query may not only slow down neighboring processes by constantly consuming CPU resources but also "crash" the entire database by "eating" all available memory. Therefore, protection against infinite recursion is the responsibility of the developer.
In PostgreSQL, the ability to use recursive queries has been available since the ancient days of version 8.4, but it’s still common to encounter potentially vulnerable "defenseless" queries. How can you protect yourself from problems of this kind? Do not write recursive queries
But write non-recursive ones. Yours sincerely, K.O.
In fact, PostgreSQL offers a sufficient amount of functionality that can be leveraged to
apply recursion. do not Use a fundamentally different approach to the problem.
Sometimes you can simply look at the task "from another angle". An example of such a situation I provided in the article
"SQL HowTo: 1000 and one way to aggregate" WITH RECURSIVE src AS ( SELECT '{2,3,5,7,11,13,17,19}'::integer[] arr ) , T(i, val) AS ( SELECT 1::bigint , 1 UNION ALL SELECT i + 1 , val * arr[i] FROM T , src WHERE i <= array_length(arr, 1) ) SELECT val FROM T ORDER BY -- selection of the final result i DESC LIMIT 1;
Such a query can be replaced with a version from math experts:WITH src AS ( SELECT unnest('{2,3,5,7,11,13,17,19}'::integer[]) prime ) SELECT exp(sum(ln(prime)))::integer val FROM src;
Use generate_series instead of loops.Suppose we need to generate all possible prefixes for the string
'abcdefgh' WITH RECURSIVE T AS ( SELECT 'abcdefgh' str UNION ALL SELECT substr(str, 1, length(str) - 1) FROM T WHERE length(str) > 1 ) TABLE T;:
Is recursion really needed here?.. If you use LATERAL generate_series and , then even CTE won’t be needed:SELECT substr(str, 1, ln) str FROM (VALUES('abcdefgh')) T(str) , LATERAL( SELECT generate_series(length(str), 1, -1) ln ) X;
Change the database structure.Change the database structure
For example, you have a forum message table with relationships indicating who replied to whom or a thread in :
CREATE TABLE message(
  message_id
    uuid
      PRIMARY KEY
, reply_to
    uuid
      REFERENCES message
, body
    text
);
CREATE INDEX ON message(reply_to); 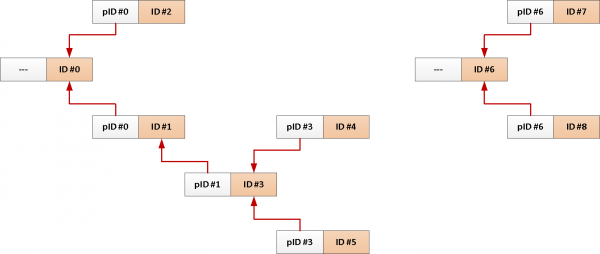
A typical query to load all messages on a specific topic looks something like this:
WITH RECURSIVE T AS (
  SELECT
    *
  FROM
    message
  WHERE
    message_id = $1
UNION ALL
  SELECT
    m.*
  FROM
    T
  JOIN
    message m
      ON m.reply_to = T.message_id
)
TABLE T;
But since we always need the entire thread from the root message, why not add its identifier to each record automatically?
-- let's add a field with a common topic identifier and an index on it
ALTER TABLE message
  ADD COLUMN theme_id uuid;
CREATE INDEX ON message(theme_id);

-- initialize the topic identifier in the trigger upon insertion
CREATE OR REPLACE FUNCTION ins() RETURNS TRIGGER AS $$
BEGIN
  NEW.theme_id = CASE
    WHEN NEW.reply_to IS NULL THEN NEW.message_id -- take from the starting event
    ELSE ( -- or from the message we're replying to
      SELECT
        theme_id
      FROM
        message
      WHERE
        message_id = NEW.reply_to
    )
  END;
  RETURN NEW;
END;
$$ LANGUAGE plpgsql;

CREATE TRIGGER ins BEFORE INSERT
  ON message
    FOR EACH ROW
EXECUTE PROCEDURE ins(); 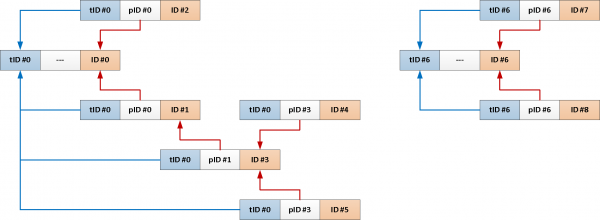
Now our entire recursive query can be simplified to just this:
SELECT
  *
FROM
  message
WHERE
  theme_id = $1;
Use application "limiters"
If we can't change the database structure for some reason, let's look at what can be relied upon so that even the presence of an error in the data doesn't lead to infinite recursion.
Recursion "depth" counter
Simply increase the counter by one at each step of the recursion until we reach a limit that we consider obviously unreasonable:
WITH RECURSIVE T AS (
  SELECT
    0 i
  ...
UNION ALL
  SELECT
    i + 1
  ...
  WHERE
    T.i < 64 -- limit
)
Pro: In the event of an attempt to loop, we will still not perform more iterations "downward" than the specified limit.
Contra: There is no guarantee that we won't process the same record multiple times — for example, at depths 15 and 25, and subsequently every +10. And there are no promises regarding "sideways" operations.
Formally, this recursion will not be infinite, but if the number of records increases exponentially at each step, we all know how this ends...
Keeper of the "path"
Sequentially append all the identifiers of the objects we encounter during the recursion to an array that serves as the unique "path" to it:
WITH RECURSIVE T AS (
  SELECT
    ARRAY[id] path
  ...
UNION ALL
  SELECT
    path || id
  ...
  WHERE
    id  ALL(T.path) -- does not match any of
)
Pro: In the presence of a cycle in the data, we will absolutely not process the same record again within the same path.
Contra: However, we can literally go through all the records without repeating ourselves.
Path Length Limit
To avoid the situation of recursion 'wandering' at an unclear depth, we can combine the two previous methods. Or, if we don't want to maintain extra fields, we can supplement the recursion continuation condition with a path length estimate:
WITH RECURSIVE T AS (
  SELECT
    ARRAY[id] path
  ...
UNION ALL
  SELECT
    path || id
  ...
  WHERE
    id  ALL(T.path) AND
    array_length(T.path, 1) < 10
)
Choose a method to your liking!
Source: habr.com
