

In the course of work, developers often encounter situations where they write a query and think, "the database is smart; it will handle everything on its own!"«
In some cases (partly due to a lack of knowledge about the database's capabilities, partly due to premature optimizations), this approach leads to the emergence of "Frankensteins."
First, let me provide an example of such a query:
-- for each key pair, find associated field values
WITH RECURSIVE cte_bind AS (
  SELECT DISTINCT ON (key_a, key_b)
    key_a a
  , key_b b
  , fld1 bind_fld1
  , fld2 bind_fld2
  FROM
    tbl
)
-- find min/max values for each first key
, cte_max AS (
  SELECT
    a
  , max(bind_fld1) bind_fld1
  , min(bind_fld2) bind_fld2
  FROM
    cte_bind
  GROUP BY
    a
)
-- link key pairs and min/max values by the first key
, cte_a_bind AS (
  SELECT
    cte_bind.a
  , cte_bind.b
  , cte_max.bind_fld1
  , cte_max.bind_fld2
  FROM
    cte_bind
  INNER JOIN
    cte_max
      ON cte_max.a = cte_bind.a
)
SELECT * FROM cte_a_bind;
To objectively assess the quality of the query, let's create some arbitrary dataset:
CREATE TABLE tbl AS
SELECT
  (random() * 1000)::integer key_a
, (random() * 1000)::integer key_b
, (random() * 10000)::integer fld1
, (random() * 10000)::integer fld2
FROM
  generate_series(1, 10000);
CREATE INDEX ON tbl(key_a, key_b);
It turns out that reading the data took less than a quarter of the total query execution time: Let's analyze it piece by piece.
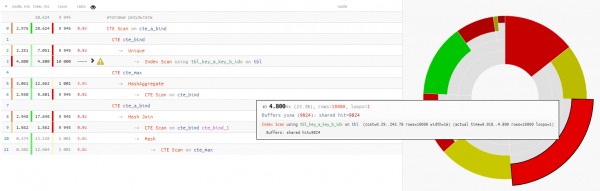
We'll take a close look at the query and wonder:
Why is there a WITH RECURSIVE here, if there are no recursive CTEs?
- Why group min/max values in a separate CTE if they are going to be linked to the original selection anyway?
- +25% time
Why use a repeated read from the previous CTE with an unconditional ‘SELECT * FROM’ at the end? - +14% time
In this case, we were fortunate that a Hash Join was chosen for the join, rather than a Nested Loop, otherwise we would have had not just a single CTE Scan, but 10K!
A bit about CTE Scan.
Here we need to remember thatCTE Scan is analogous to Seq Scan — meaning no indexing, just a complete enumeration that would require 10K x 0.3ms = 3000ms for cycles over cte_max. 1K x 1.5ms = or 1500ms for cycles over cte_bind. So, what were we hoping to get as a result?!
Ah, usually that’s the kind of question that comes to mind around the 5th minute of analyzing "three-tiered" queries. We wanted to output for each unique key pair
the min/max from the group by key_a. So let's make use of.
window functions. :
SELECT DISTINCT ON(key_a, key_b)
	key_a a
,	key_b b
,	max(fld1) OVER(w) bind_fld1
,	min(fld2) OVER(w) bind_fld2
FROM
	tbl
WINDOW
w AS (PARTITION BY key_a); 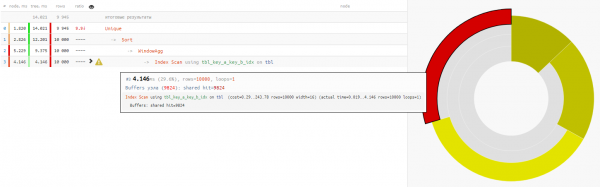
Since reading data in both cases takes roughly the same 4-5ms, our overall time gain -32% is purely the load lifted from the CPU of the database, if such a request is executed frequently enough.
In general, you shouldn't force the database to do tasks it's not designed for.
Source: habr.com
