

Today, we'll discuss how best to store data in a world where fifth-generation networks, genome scanners, and autonomous vehicles generate more data in a single day than all of humanity produced from the beginning of the industrial revolution.
Our world is generating more information than ever. Some of it is fleeting and lost just as quickly as it is collected. Other information needs to be stored longer, while some is intended to last 'for ages' — at least that’s how it seems from our current perspective. Data streams settle in data centers at such a pace that any new approach or technology designed to meet this endless 'demand' quickly becomes outdated.
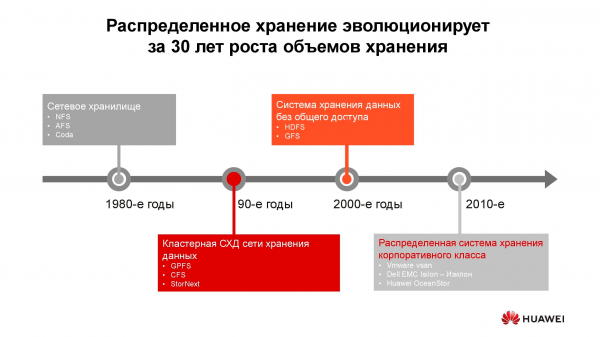
40 years of development in distributed storage systems
The first networked storage systems in the form we know emerged in the 1980s. Many of you may be familiar with NFS (Network File System), AFS (Andrew File System), or Coda. A decade later, trends and technologies changed, and distributed file systems gave way to clustered storage systems based on GPFS (General Parallel File System), CFS (Clustered File Systems), and StorNext. Traditional block storage architecture served as the basis on which a unified file system was built through a software layer. These and similar solutions are still in use, occupy their niche, and are in demand.
At the turn of the millennium, the paradigm of distributed storage changed somewhat, leading to the emergence of systems with SN (Shared Nothing) architecture. The transition occurred from clustered storage to storage on individual nodes, typically classic servers that provide reliable storage software; this principle underpins, for example, HDFS (Hadoop Distributed File System) and GFS (Global File System).
By the 2010s, the concepts underlying distributed storage systems increasingly began to reflect in full-fledged commercial products, such as VMware vSAN, Dell EMC Isilon, and our . Behind these platforms stand not just a community of enthusiasts, but specific vendors who are responsible for the functionality, support, maintenance of the product, and guarantee its further development. Such solutions are in high demand in several sectors.
Telecommunications operators
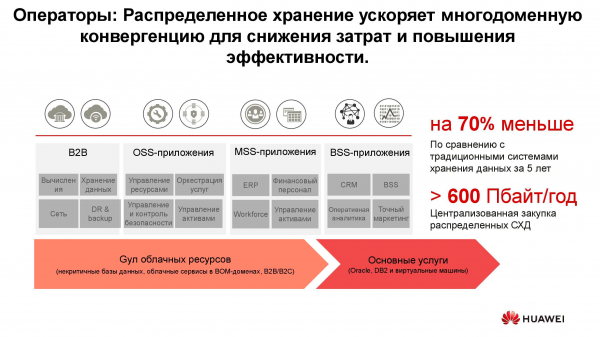
Perhaps some of the oldest consumers of distributed storage systems are telecommunications operators. The diagram shows which groups of applications generate the majority of data. OSS (Operations Support Systems), MSS (Management Support Services), and BSS (Business Support Systems) are three complementary software layers necessary for providing service to subscribers, financial reporting to the provider, and operational support to the operator's engineers.
Often, the data from these layers is heavily intermingled, and to avoid the accumulation of unnecessary copies, distributed storage systems are used to aggregate all the information coming from the operational network. These storages are combined into a common pool, which is accessed by all services.
Our calculations show that transitioning from traditional storage systems to block storage can save up to 70% of the budget simply by replacing high-end dedicated storage systems with standard classical architecture servers (typically x86) working in conjunction with specialized software. Mobile operators have been acquiring such solutions in significant volumes for quite some time. In particular, Russian operators have been using products from Huawei for over six years.
Yes, a number of tasks cannot be accomplished using distributed systems. For example, when there are increased requirements for performance or compatibility with outdated protocols. However, no less than 70% of the data processed by the operator can be effectively stored in a distributed pool.
Banking Sector
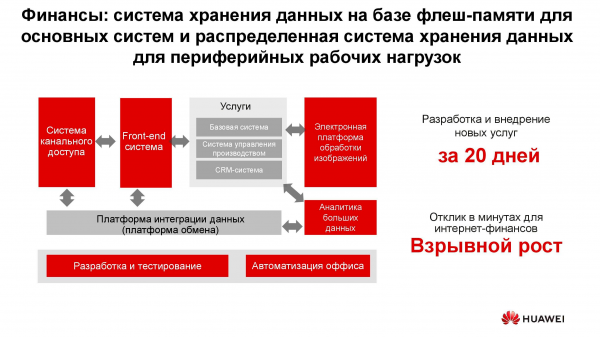
In any bank, there are many diverse IT systems, ranging from processing to automated banking systems. This infrastructure also works with a vast amount of information, although the majority of tasks do not require high performance and reliability from storage systems, such as development, testing, office process automation, etc. In this context, using traditional storage systems is possible, but it becomes less economically advantageous each year. Moreover, in this case, there is a lack of flexibility in resource allocation for storage systems, whose performance is determined by peak load.
When using distributed storage systems, their nodes, which are essentially ordinary servers, can be converted at any moment into a server farm and used as a computing platform.
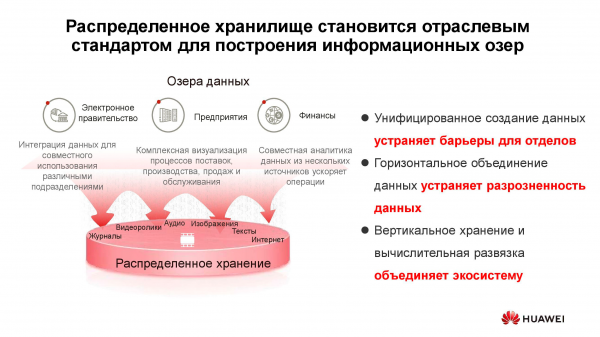
Data Lakes
The diagram above lists typical consumers of these services. These can include e-government services (for example, 'State Services') that have undergone digital transformation, financial institutions, and others. They all need to work with large volumes of heterogeneous information.
Using traditional storage systems to address such tasks is ineffective since both high-performance access to block databases and regular access to libraries of scanned documents stored as objects are required. A web portal order system, for example, might also be connected here. To implement all this on a traditional storage platform, a large amount of hardware would be needed for various tasks. A single horizontal universal storage system could handle all previously mentioned tasks; it would only require creating several pools with different storage characteristics.
Generators of New Information
The amount of information stored in the world is growing by about 30% annually. This is good news for storage system providers, but what is and will be the main source of this data?
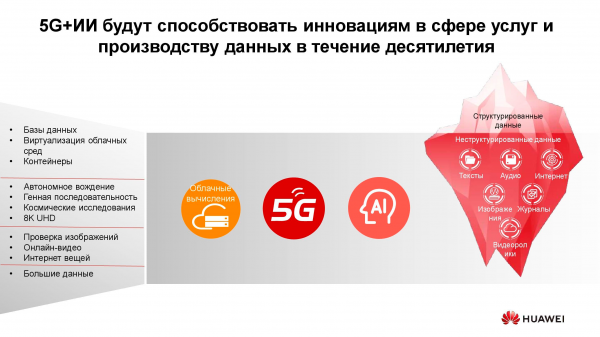
Ten years ago, social networks became such generators, requiring the creation of a large number of new algorithms, hardware solutions, etc. Currently, three main drivers of storage growth are identified. The first is cloud computing. Today, approximately 70% of companies use cloud services in one form or another. This can include email systems, backups, and other virtualized entities.
The second driver is fifth-generation networks. These offer new speeds and new data transfer volumes. According to our forecasts, the widespread adoption of 5G will lead to a decrease in demand for flash memory cards. No matter how much memory a phone has, it eventually runs out, and with a 100-megabit channel in the device, there is no need to store photos locally.
The third group of reasons driving the demand for storage systems includes the rapid development of artificial intelligence, the shift to big data analytics, and the trend towards universal automation of everything possible.
A distinctive feature of 'new traffic' is its . We need to store this data without defining its format. The format is only required when it is read later. For example, a scoring system in banking to determine the available loan amount will look at the photos you've posted on social media, assessing how often you visit the sea and restaurants, while also reviewing available excerpts from your medical records. This data is, on one hand, comprehensive, and on the other, it lacks uniformity.
The ocean of unstructured data
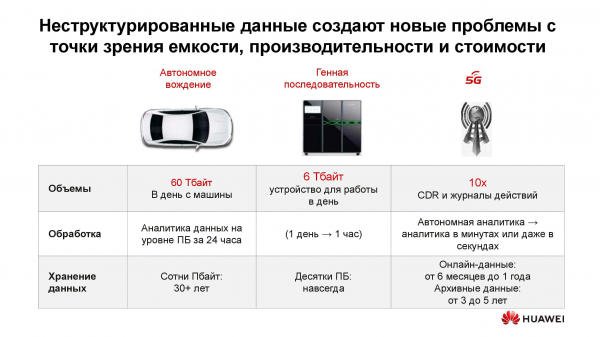
What problems does the emergence of 'new data' bring? The foremost issue is certainly the sheer volume of information and the projected duration of its storage. A modern autonomous vehicle generates up to 60 TB of data daily from all its sensors and mechanisms. To develop new movement algorithms, this information must be processed within the same day; otherwise, it will begin to accumulate. Meanwhile, it must be stored for a very long time—dozens of years. Only then can we draw conclusions based on large analytical samples in the future.
One device for decoding genetic sequences produces about 6 TB per day. The data collected through it does not imply deletion, meaning it theoretically should be stored permanently.
Finally, there are the same fifth-generation networks. Besides the information being transmitted, such a network itself is a massive generator of data: logs of actions, call records, intermediate results of inter-machine interactions, etc.
All this demands the development of new approaches and algorithms for storing and processing information. And such approaches are emerging.
Technologies of a new era
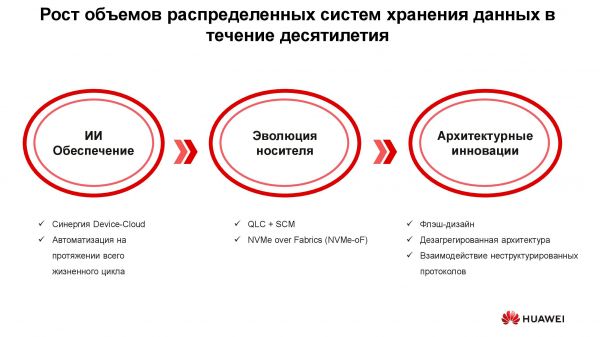
Three groups of solutions can be identified to address the new requirements for information storage systems: the implementation of artificial intelligence, the technical evolution of data carriers, and innovations in system architecture. Let's start with AI.
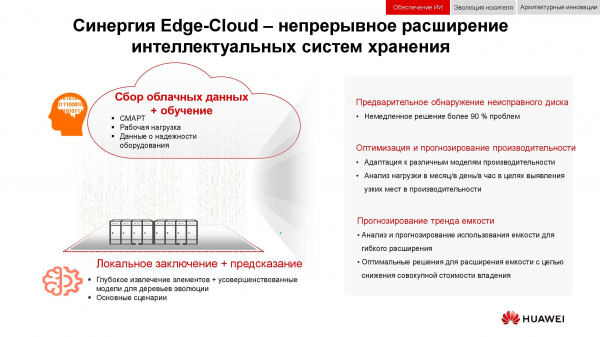
In Huawei's new solutions, artificial intelligence is already integrated at the storage level, equipped with an AI processor that enables the system to autonomously analyze its state and predict failures. If the storage system is connected to a service cloud with significant computing capabilities, the AI can process more information and enhance the accuracy of its predictions.
In addition to failures, this AI can forecast future peak loads and the time remaining until capacity exhaustion. This allows for optimizing performance and scaling the system before any undesirable events occur.
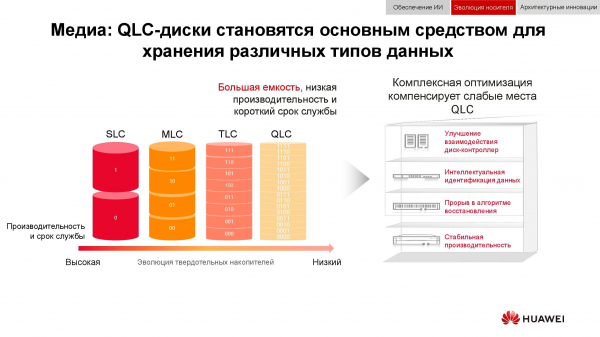
Now, let's talk about the evolution of data storage devices. The first flash drives were based on SLC (Single-Level Cell) technology. Devices based on this technology were fast, reliable, and stable, but had limited capacity and were very expensive. Growth in capacity and reduction in price were achieved through certain technical compromises, which reduced speed, reliability, and lifespan. Nevertheless, this trend did not affect the storage systems themselves, which, thanks to various architectural tricks, became both more efficient and more reliable overall.
But why was there a need for All-Flash storage systems? Wasn't it enough to simply replace the old HDDs in already operational systems with new SSDs of the same form factor? This was necessary to effectively utilize all the resources of the new solid-state drives, which was simply impossible in older systems.
Huawei, for instance, has developed a whole range of technologies to address this challenge, one of which is , which maximally optimizes the interactions between the "disk and controller."
Intelligent identification enabled the distribution of data across multiple streams, effectively addressing a number of undesirable phenomena such as (write amplification). Additionally, new recovery algorithms, particularly , increased rebuild speeds, reducing the time to virtually negligible amounts.
Failures, overflow, and "garbage collection"—these factors no longer affect the storage system's performance thanks to specialized enhancements to the controllers.
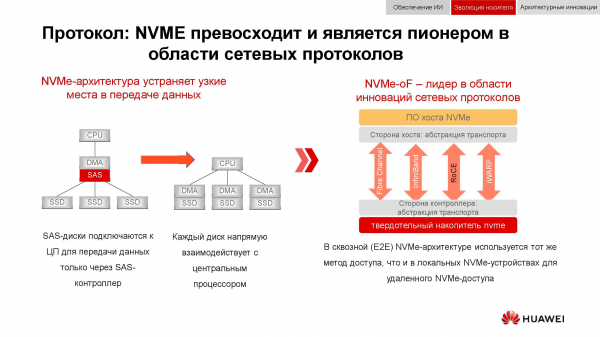
And block data storage is preparing to meet . It’s worth recalling that the classic data access organization scheme functioned as follows: the processor addressed the RAID controller via the PCI Express bus. The controller, in turn, interacted with mechanical disks via SCSI or SAS. The application of NVMe on the backend significantly accelerated the entire process, but it had one downside: storage devices had to be directly connected to the processor to provide direct access to memory.
The next phase of technology development that we are currently witnessing has been the application of NVMe-oF (NVMe over Fabrics). As for Huawei's block technologies, they already support FC-NVMe (NVMe over Fibre Channel), and NVMe over RoCE (RDMA over Converged Ethernet) is on the way. Test models are fully functional, and only a few months remain until their official presentation. Note that all this will also appear in distributed systems, where ‘lossless Ethernet’ will be in high demand.
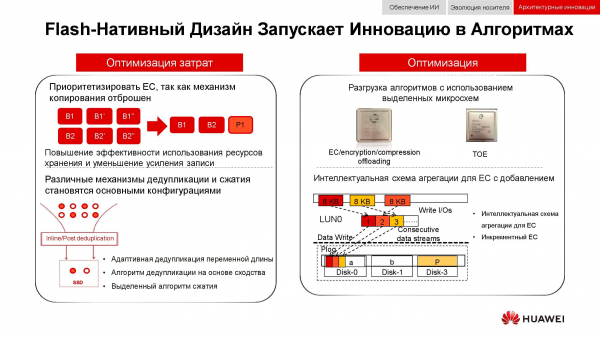
An additional method of optimizing the operation of distributed storage has become the complete abandonment of data mirroring. Huawei's solutions no longer use n copies, as in traditional RAID 1, and fully transition to a mechanism (Erasure coding). A special mathematical package periodically calculates parity blocks, allowing for the restoration of intermediate data in case of loss.
Deduplication and compression mechanisms are becoming mandatory. While in traditional storage systems we are limited by the number of processors installed in the controllers, in horizontally scalable distributed storage systems, each node contains everything necessary: disks, memory, processors, and interconnect. These resources are sufficient for deduplication and compression to have minimal impact on performance.
And about hardware optimization methods. Here, the load on central processors has been reduced with the help of additional dedicated chips (or dedicated blocks within the processor itself), performing the role of (TCP/IP Offload Engine) or taking on mathematical tasks of EC, deduplication, and compression.
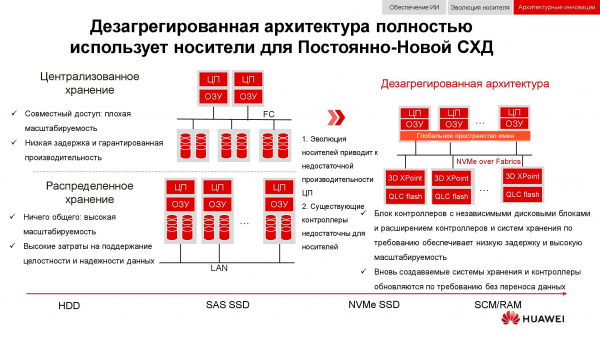
New approaches to data storage have been embodied in disaggregated (distributed) architecture. In centralized storage systems, there is a factory of servers connected via Fibre Channel to a large number of arrays. The drawbacks of this approach include difficulties in scalability and ensuring guaranteed service levels (in terms of performance or latency). Hyper-converged systems use the same hosts for both storage and processing of information. This provides virtually unlimited scalability but entails high costs for maintaining data integrity.
Unlike both of the aforementioned, disaggregated architecture implies the separation of the system into a compute factory and a horizontal storage system. This provides the advantages of both architectures and allows for virtually unlimited scalability of only the element that lacks performance.
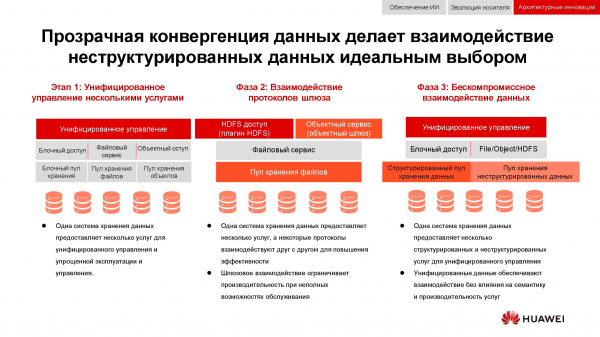
From Integration to Convergence
A classic problem, whose relevance has only grown over the past 15 years, is the need to simultaneously provide block storage, file access, object access, and big data farm operations, etc. The cherry on top might also include, for instance, a backup system to magnetic tape.
At the first stage, it was only possible to unify the management of these services. Heterogeneous data storage systems were tied to some specialized software through which the administrator distributed resources from available pools. However, since these pools were different hardware-wise, migrating loads between them was impossible. At a higher level of integration, unification occurred at the gateway level. With the availability of a common file access, it could be provided through different protocols.
The most advanced method of convergence available to us now implies the creation of a universal hybrid system. This is precisely what our Universal access uses the same hardware resources, logically divided into different pools, yet allowing load migration. All of this can be done through a single management console. This way, we have managed to realize the concept of 'one data center — one storage system.'
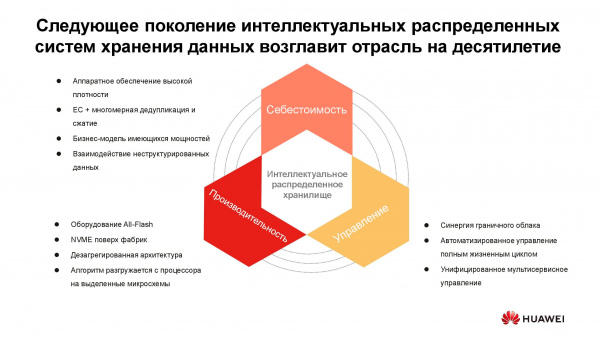
The cost of information storage currently defines many architectural decisions. While it can confidently be placed at the forefront, we are discussing 'live' storage with active access today, so performance must also be considered. Another important characteristic of next-generation distributed systems is unification. After all, no one wants several disconnected systems managed from different consoles. All these qualities have found embodiment in the new series of Huawei products. .
Next-generation mass storage system
OceanStor Pacific meets reliability requirements at the 'six nines' level (99.9999%) and can be used to create HyperMetro class data centers. With a distance of up to 100 km between two data centers, the systems demonstrate an added latency of 2 ms, allowing for the construction of any disaster-resistant solutions, including those with quorum servers.
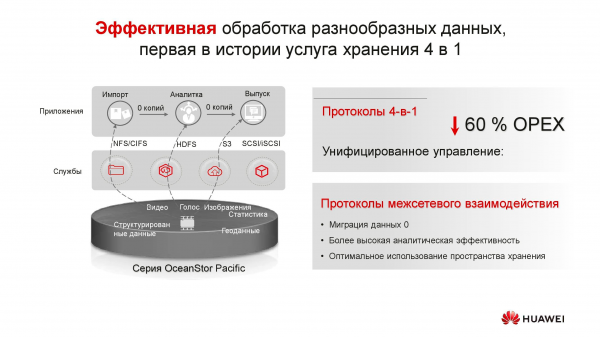
The products of the new series demonstrate versatility across protocols. Already, OceanStor 100D supports block access, object access, and Hadoop access. File access will be implemented soon. There is no need to store multiple copies of data if they can be delivered through different protocols.
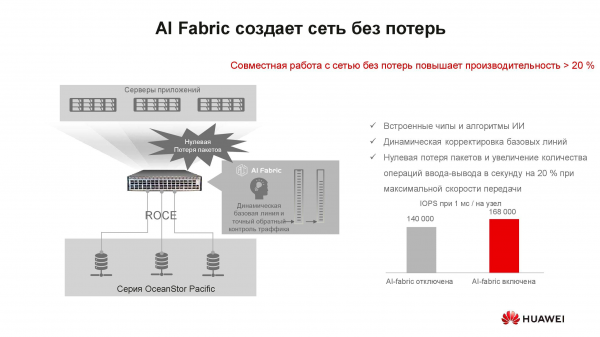
It may seem that the concept of 'lossless network' has nothing to do with storage systems. The fact is that distributed data storage systems are built on a fast network that supports the corresponding algorithms and the RoCE mechanism. Our switches also help increase network speed and reduce latency through an artificial intelligence system. The performance gain of the storage system when activating AI Fabric can reach 20%.
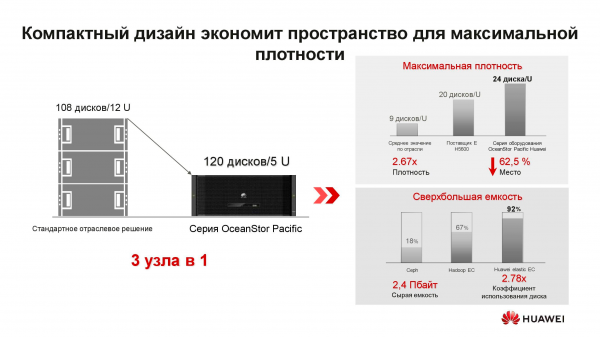
What does the new node of the distributed storage system OceanStor Pacific represent? The 5U form factor solution includes 120 drives and can replace three classic nodes, resulting in more than double the space savings in the rack. By eliminating the need to store copies, the efficiency of the drives significantly increases (up to +92%).
We are accustomed to software-defined storage being software installed on a traditional server. However, to achieve optimal parameters, this architectural solution now requires specialized nodes. It consists of two servers based on ARM processors that manage an array of three-inch drives.
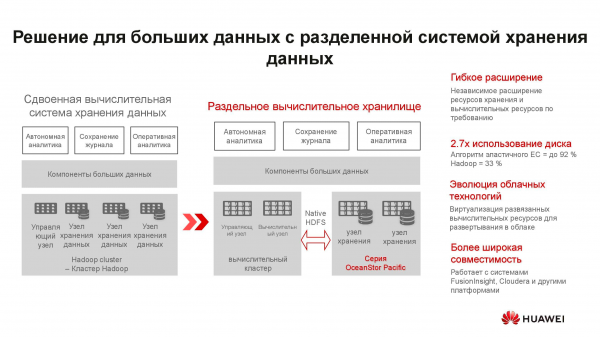
These servers are not well-suited for hyper-converged solutions. Firstly, there are not many applications for ARM, and secondly, it is difficult to maintain load balancing. We suggest transitioning to separate storage: a compute cluster represented by classic or rack servers operates separately but connects to the OceanStor Pacific storage nodes, which also perform their direct tasks. And this proves to be justified.
For example, consider a traditional solution for big data storage with a hyper-converged system occupying 15 server racks. If the load is distributed between separate compute servers and OceanStor Pacific storage nodes, separating them from each other, the number of required racks can be halved! This reduces data center operational costs and lowers the total cost of ownership. In a world where the volume of stored information is growing by 30% per year, such advantages are not to be overlooked.
***
More information about Huawei solutions and their application scenarios can be found on our or by directly contacting company representatives.
Source: habr.com
