

I invite you to review the transcript of Nikolai Samokhvalov's report 'Industrial Approach to Tuning PostgreSQL: Experiments with Databases'
Is Shared_buffers = 25% a lot or a little? Or just right? How to determine if this rather outdated recommendation fits your specific case?
It's time to address the selection of parameters in postgresql.conf 'maturely'. Not through blind 'auto-tuners' or outdated advice from articles and blogs, but based on:
- strictly calibrated experiments on databases, conducted automatically, in large quantities and under conditions as close to 'live' as possible,
- a deep understanding of the peculiarities of DBMS and OS.
Using Nancy CLI (), we will examine a specific example – the notorious shared_buffers – in various situations, in different projects, and try to figure out how to select the optimal settings for our infrastructure, databases, and load.
We will talk about experiments with databases. This story has been ongoing for just over six months.
A little about myself. I have over 14 years of experience with Postgres. I founded several social networking companies where Postgres was used and continues to be used.
Also, the RuPostgres group on Meetup, ranked 2nd in the world. We are slowly approaching 2,000 members. RuPostgres.org.
At various conferences, including Highload, I am responsible for databases, particularly Postgres, from the very beginning.
In recent years, I restarted my Postgres consulting practice in 11 time zones from here.
When I did this a few years ago, I had a bit of a break from active hands-on work with Postgres, probably since 2010. I was surprised at how little the daily work of a DBA had changed, and how much manual labor was still required. I immediately thought that something was not right; there needed to be more automation.
Since most of this was remote, most clients were in the cloud. A lot of automation had obviously been implemented. More on this later. In other words, it led to the idea that there should be a set of tools, i.e., a platform that would automate almost all DBA actions to manage a large number of databases.
This report will not cover:
- "Silver bullets" and statements like – set 8 GB or 25% shared_buffers and you'll be fine. There won't be much about shared_buffers.
- Hardcore "internals".
What will happen?
- There will be optimization principles that we apply and develop. There will be various ideas that arise along the way and different tools that we create mostly in Open Source, i.e., we build the foundation in Open Source. Moreover, we have tickets, and practically all communication is in Open Source. You can see what we are currently working on, what will be in the next release, etc.
- There will also be some experience using these principles and tools in a range of companies: from small startups to large corporations.
How is all this evolving?
First of all, the main task of a DBA, besides ensuring the creation of instances, deploying backups, etc., is to find bottlenecks and optimize performance.
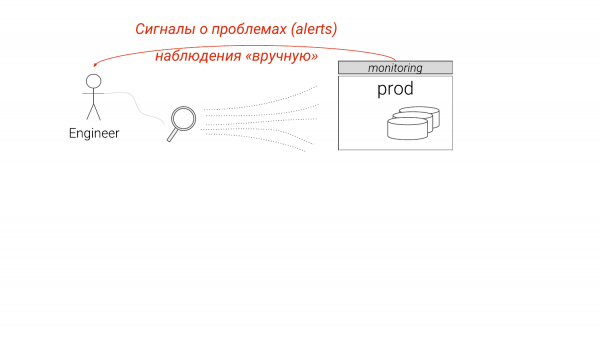
Currently, it's organized this way. We look at monitoring, see something, and lack some details. We start digging deeper, usually manually, and understand what to do with it one way or another.
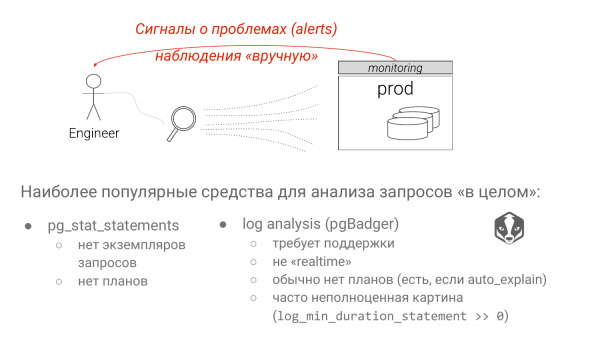
And there are two approaches. Pg_stat_statements – the default standard solution for identifying slow queries. And log analysis of Postgres using pgBadger.
Each approach has serious drawbacks. The first approach discards all parameters. If we see groups like SELECT * FROM table where column equals "?" or "$" starting from Postgres version 10. We don’t know – is it an index scan or a seq scan? It heavily depends on the parameter. Insert a rarely encountered value, and it will be an index scan. Insert a value that occupies 90% of the table, and it will be a seq scan obviously because Postgres knows the statistics. This is a significant drawback of pg_stat_statements, although some work is being done.
The main drawback of log analysis is that you generally can't afford "log_min_duration_statement = 0". We will also talk about that. Consequently, you don't see the whole picture. A very fast query may consume a huge amount of resources, but you won't see it because it falls below your threshold.
How do DBAs resolve the problems they find?
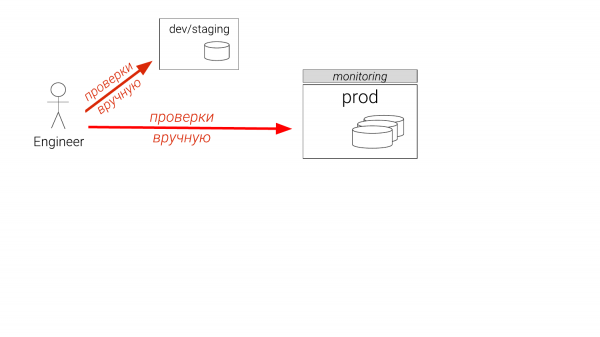
For instance, we encountered a problem. What is usually done? If you're a developer, you'll be working on an instance that is not that large. If you're a DBA, you have a staging environment. And there can only be one. It has been lagging behind for six months. You think you’ll move to production. Even experienced DBAs check on production, on a replica afterwards. Sometimes they create a temporary index, verify that it helps, drop it, and hand it back to developers to include it in migration files. This kind of nonsense is happening now. It’s a disaster.
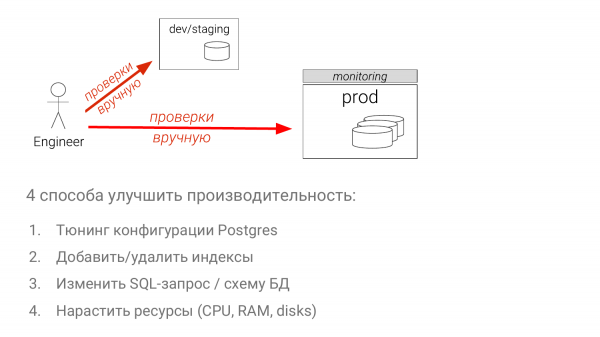
- Tuning configurations.
- Optimizing the index set.
- Modifying the SQL query itself (this is the most complex way).
- Adding resources (the simplest method in most cases).
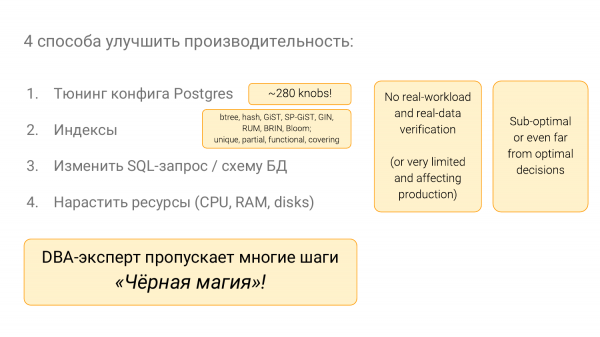
There is a lot involved with these things. There are many knobs in Postgres. One needs to know a lot. There are a lot of indexes in Postgres, thanks in part to the organizers of this conference. All this knowledge is required, and this is why non-DBAs feel like DBAs are practicing dark magic. That is, it takes about ten years to start understanding all of this properly.
And I am a fighter against this dark magic. I want to ensure that we have technology rather than intuition in all of this.
Real-life examples
I've observed this in at least two projects, including my own. A blog post informs us that a value of 1,000 for default_statistic_target is good. Fine, let’s try it in production.
And here we are, two years later, using our tool, able to compare what was and what is now with the databases we are discussing today.
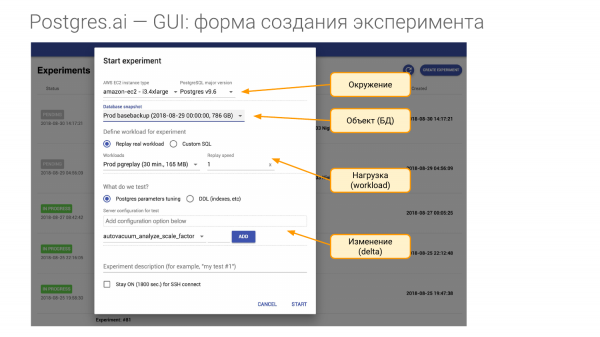
To do this, we need to create an experiment. It consists of four parts.
- The first part is the environment. We need the hardware. When I come to a company and sign a contract, I request hardware that is the same as in production. For each of your Masters, I need at least one piece of identical hardware. Either it's a virtual machine instance on Amazon or Google, or I need exactly the same hardware. That is, I want to recreate the environment. And by 'environment' we mean the major version of Postgres.
- The second part is the subject of our studies. It is the database. It can be created in several ways. I will show how.
- The third part is the load. This is the most challenging aspect.
- The fourth part is what we verify, i.e., what we will compare. For instance, we can change one or several parameters in the config, or we can create an index, etc.
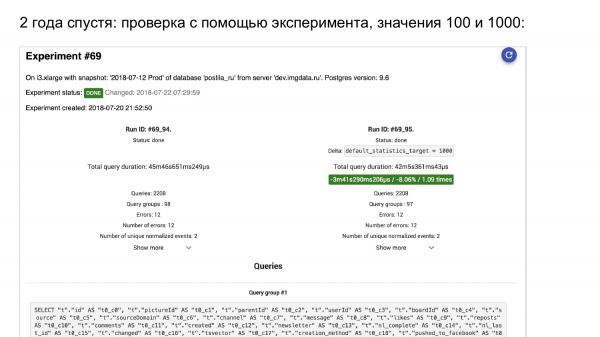
We are running an experiment. Here is pg_stat_statements. On the left – what it was. On the right – what it has become.
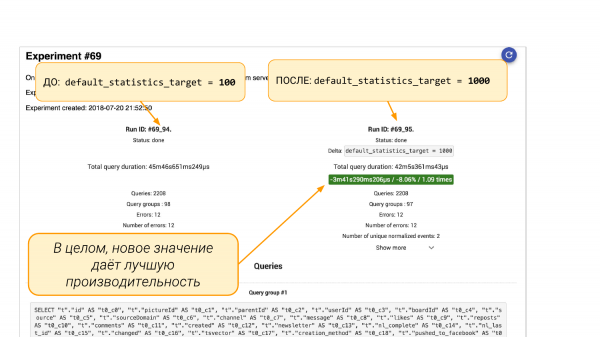
On the left, default_statistics_target = 100, on the right = 1,000. We see that this has helped us. Overall, everything improved by 8%.
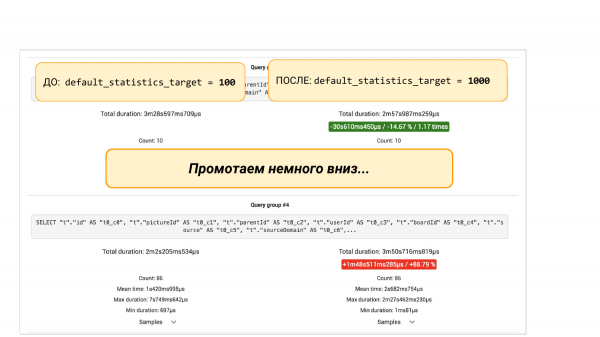
But if we scroll down, there will be groups of queries from pgBadger or from pg_stat_statements. Here we have two options. We will see that a certain query has decreased by 88%. This calls for an engineering approach. We can dig deeper, as it's interesting to see why it dropped. We need to understand what happened with the statistics. Why do more buckets in the statistics lead to worse results?
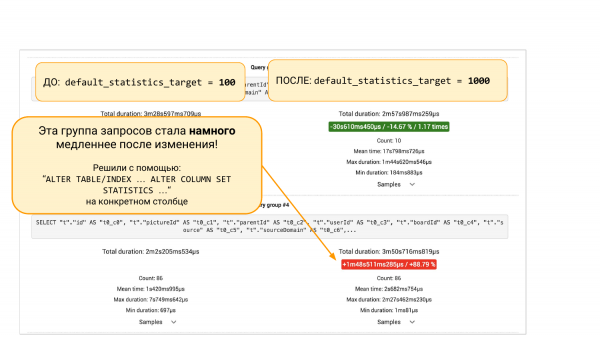
Alternatively, we could just run an 'ALTER TABLE… ALTER COLUMN' command and revert back to 100 buckets in the statistics for that column. We can further confirm through experimentation that this fix helped. That’s it. This is the engineering approach that helps us see the big picture and make decisions based on data, not intuition.
A couple of examples from other fields. In testing, CI tests have been around for many years. No project in its right mind would operate without automated tests.
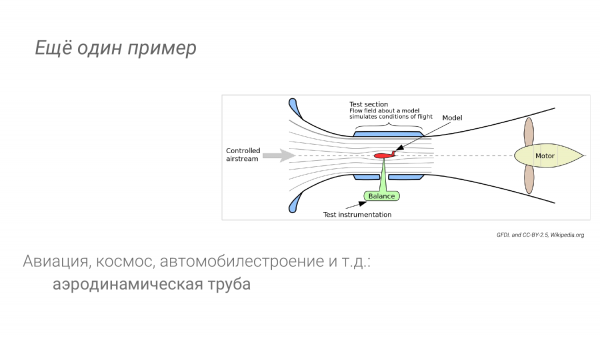
In other industries, like aviation and automotive engineering, when we test aerodynamics, we also have the opportunity to conduct experiments. We won't launch something from the blueprint straight into space or immediately put a car on the road. For example, we have a wind tunnel.
From observing other industries, we can draw conclusions.
Firstly, we have a special environment. It is close to production, but not exactly. Its main feature is that it should be cost-effective, repeatable, and as automated as possible. Additionally, there should be specific tools for conducting detailed analysis.
Most likely, when we launch the aircraft and are flying, we have fewer opportunities to study every millimeter of the wing surface than we do in a wind tunnel. We have more means for diagnostics. We can afford to attach more heavy equipment that we cannot take onto an airplane in the air. The same goes for Postgres. In some cases, we can enable full query logging during experiments. And we do not want to do that in production. We might even enable this with auto_explain in our plans.
And as I mentioned, a high level of automation means we pressed a button and repeated the process. That’s how it should be, with many experiments flowing in.
Nancy CLI is the foundation of the "database laboratory".
And we created this thing. I talked about these ideas back in June, almost a year ago. And we already have what we call Nancy CLI in Open Source. It is the foundation for building a database laboratory.
— This is in Open Source, on GitLab. You can say, you can try it. I provided the link in the slides, you can click on it and find it there. across all parameters.
Of course, there is still much in development. There are many ideas. But this is already something we practically apply daily. And when we have an idea—like what happens when we delete 40,000,000 rows and everything gets bottlenecked in IO—we can conduct an experiment and look into it more deeply to understand what is happening and then try to fix it on the fly. That is the essence of the idea.
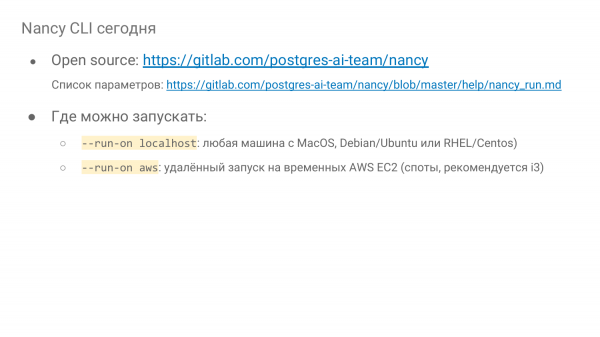
Where can this work? It can work locally, meaning you can do this anywhere; you can even run it on a MacBook. You just need Docker, and off you go. You can run it on some instance on hardware or in a virtual machine, anywhere.
There is also the possibility to run remotely on Amazon in EC2 Instances, in spot instances. This is a fantastic opportunity. For example, yesterday we conducted over 500 experiments on an i3 instance, starting from the smallest up to i3-16-xlarge. These 500 experiments cost us $64. Each lasted 15 minutes. Thanks to the use of spot instances, this is very cheap – a 70% discount with Amazon’s per-second billing. You can do a lot. You can conduct real research.
Three major versions of Postgres are supported. It's not that difficult to adapt some older versions and the new 12th version as well.
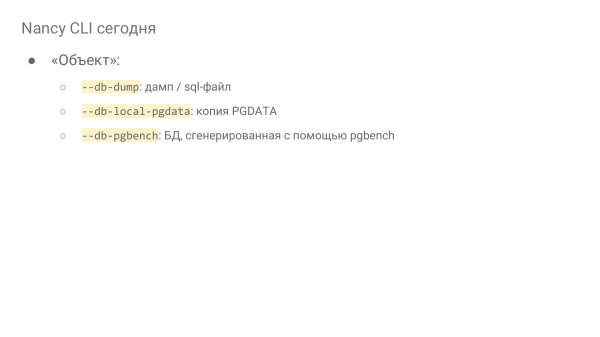
We can define the object in three ways. These are:
- Dump/sql file.
- The main method is to clone the PGDATA directory. Usually, it's taken from the backup server. If you have proper binary backups, you can create clones from there. If you have cloud storage, then the cloud provider like Amazon or Google will handle this for you. This is the primary method for cloning real production. This is how we typically deploy.
- And the last method is suitable for research when there’s a desire to understand how something works in Postgres. This is pgbench. You can generate it using pgbench. There’s simply one option 'db-pgbench.' You specify the scale and everything will be generated in the cloud as stated.
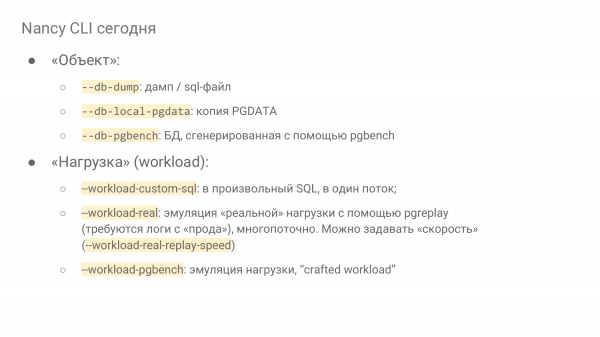
And the load:
- We can execute the load in a single-threaded SQL manner. This is the most primitive method.
- Or we can emulate the load. We primarily can emulate it in the following way. We need to collect all logs. And this is painful. I’ll show you why. We replay it using pgreplay, which is built into Nancy.
- Or another option. The so-called crafted load, which we create with some effort. By analyzing our current load on the production system, we extract the top query groups. And using pgbench, we can emulate this load in the lab.
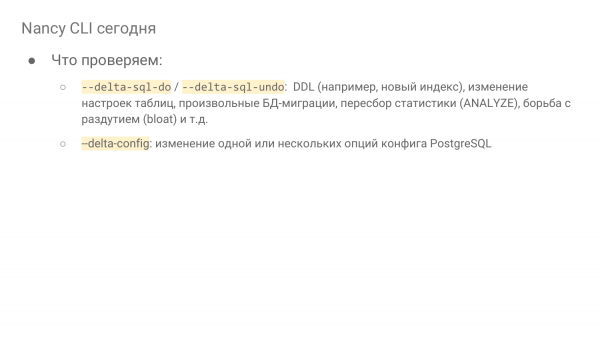
- Alternatively, we should execute some SQL, i.e., checking a migration, creating an index, performing ANALYZE. We observe what was before and after the vacuum. In general, any SQL.
- Either we change one or more parameters in the config. We can request a check, for example, of 100 values in Amazon for our terabyte database. And within a few hours, you'll have the results. Typically, a terabyte database will take several hours to deploy. However, in development, there is a patch, and we can have a series, meaning you can use the same pgdata sequentially on the same server and check. Postgres will restart, caches will be cleared, and you can run the load tests.
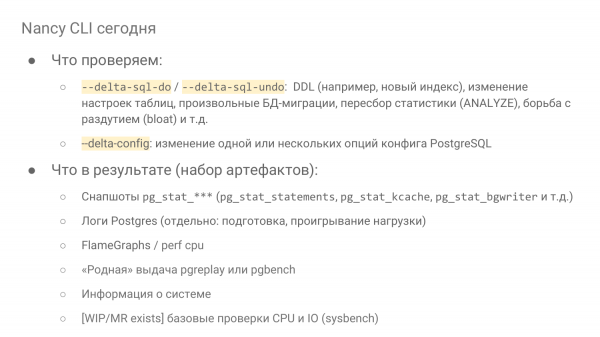
- A directory arrives containing a bunch of files, starting from pg snapshots.stat***. And the most interesting parts are pg_stat_statements and pg_stat_kcache. These are two extensions that analyze queries. Additionally, pg_stat_bgwriter contains not only pgwriter statistics but also data on checkpoints and how the backends evict dirty buffers. It’s all worth a look. For example, when we configure shared_buffers, it’s very interesting to see how much has been evicted.
- Postgres logs are also included. There are two logs – the preparation log and the load playback log.
- A relatively new feature is FlameGraphs.
- Also, if you’ve used pgreplay or pgbench for load playback, you will see their native output. You'll be able to see latency and TPS. This will help you understand how they perceived it.
- System information.
- Basic CPU and IO checks. This is more for EC2 instances on Amazon when you want to launch 100 identical instances in a flow and run 100 different tests, leading to 10,000 experiments. You need to ensure that you don’t get a degraded instance that someone has already stressed. Other activities on this hardware may leave you with limited resources. It’s better to discard such results. Using sysbench from Alexey Kopytov, we perform several short checks that will come in and can be compared with others, allowing you to understand how CPU behaves and how IO performs.
What are the technical challenges based on different companies?
For instance, if we want to simulate real load based on logs, it’s a great idea if it’s written on Open Source pgreplay. We use it. However, for it to work well, you must enable full query logging with parameters and timing.
There are some difficulties regarding duration and timestamp. We'll skip all that. The main question is whether you can afford this or not.
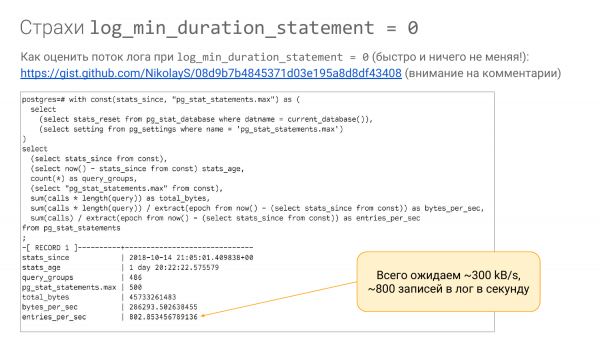
The problem is that it may be unavailable. You need to first understand what kind of stream will be written in the log. If you have pg_stat_statements, you can use this query (the link will be available in the slides) to understand approximately how many bytes will be written per second.
We look at the length of the request. We're disregarding the fact that there are no parameters, but we know the length of the request and how many times it was executed per second. Thus, we can estimate approximately how many bytes are being written per second. We might be off by a factor of two, but we'll definitely have a rough idea this way.
We can see that this request is executed 802 times per second. And we see that bytes_per_sec will be around 300 kB/s, plus or minus. Generally, we can afford such a stream.
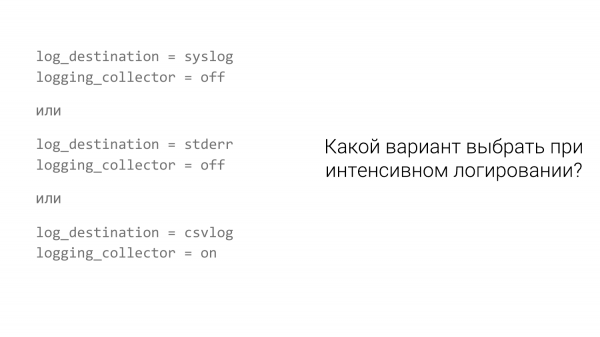
But! The thing is that there are different logging systems. By default, people usually use "syslog."
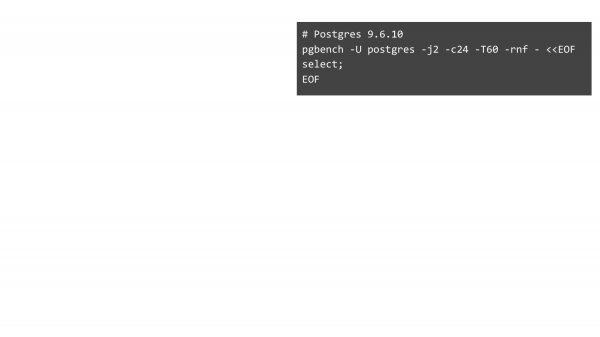
And if you have syslog, then you may have a picture like this. We'll take pgbench, enable query logging, and see what we get.
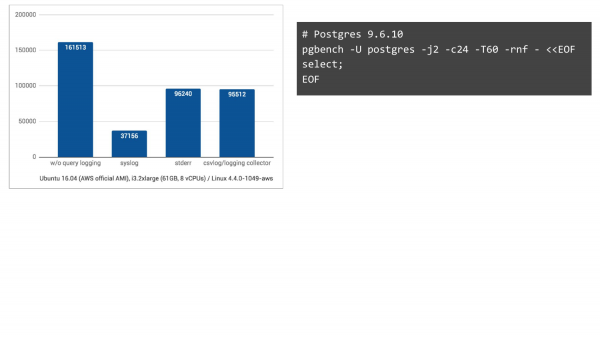
Without logging – that's the column on the left. We achieved 161,000 TPS. With syslog – on Ubuntu 16.04 on Amazon, we get 37,000 TPS. But if we switch to two other logging methods, the situation improves significantly. That is, we expected some drop, but not this much.
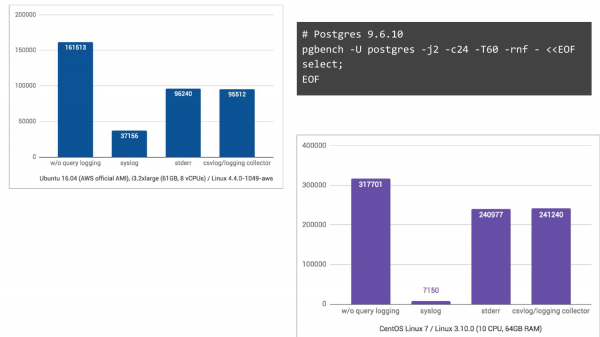
And on CentOS 7, where journald is involved, converting logs into a binary format for easier searching, it's even worse; we drop by 44 times in TPS.
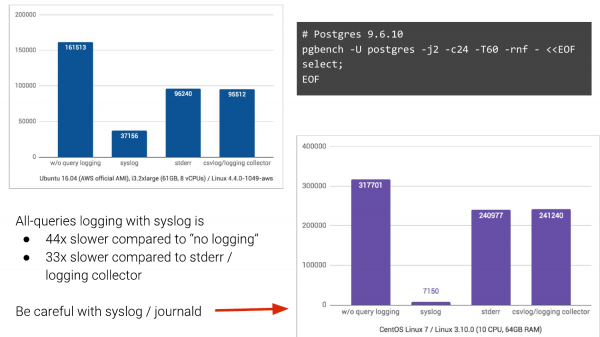
And this is what people have to deal with. Often in companies, especially large ones, it's very difficult to change. If you can move away from syslog, please do so.
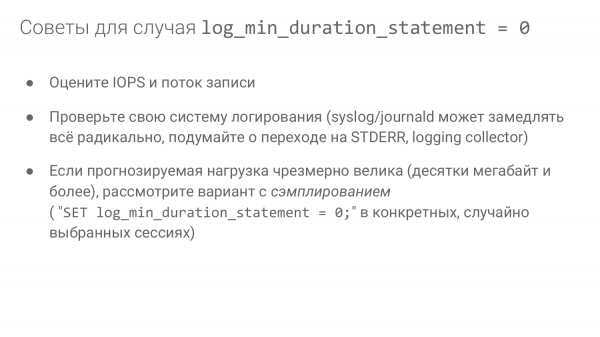
- Evaluate IOPS and write throughput.
- Check your logging system.
- If the expected load is excessively high, consider sampling.
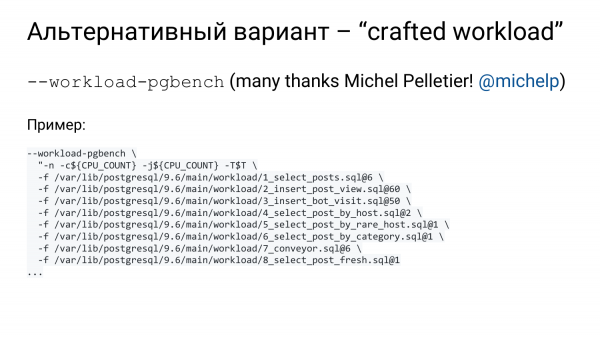
We have pg_stat_statements. As I mentioned, it must be enabled. We can take and describe each group of requests in a file in a special way. Then we can use a very handy feature in pgbench – the ability to pass multiple files using the "-f" option.
It understands a lot of '–f'. And you can specify with '@' at the end what share each file should have. That is, we can tell it to execute this 10% of the time, and that one 20%. This will bring us closer to what we see in production.
How do we know what we have in production? What portion and what exactly? This is a bit of a digression. We have another product. . It's also based on Open Source. And we are currently actively developing it.
It was born from different reasons. Because monitoring is often insufficient. That is, you come, look at the database, check the existing problems. And, as a rule, you perform a health check. If you are an experienced DBA, you do health checks. You check index usage, etc. If you have OKmeter, that's great. It's a fantastic monitoring tool for Postgres. OKmeter.io – please install it, it's really well done. It's paid.
If you don't have it, then usually you have very little. Monitoring typically only includes CPU, IO, and even that with some caveats, and that's it. But we need more. We need to see how autovacuum works, how checkpoints operate, and in IO we need to separate checkpoints from bgwriter and backends, etc.
The problem is when you help a large company, they can't implement something quickly. They can't quickly purchase OKmeter. They might buy it after six months. They can't quickly install certain packages.
So we came up with the idea that we need a special tool that requires no installation, meaning you shouldn't install anything on production at all. You install it on your laptop or on an observing server from which you'll run it. And it will analyze many things: the operating system, the file system, and Postgres itself, making some light queries that can be run directly in production without causing any downtime.
We named it Postgres-checkup. If we think of it in medical terms, it's a regular health check. In automotive terms, it's like a scheduled maintenance. You do maintenance on your car every six months or a year, depending on the brand. But do you do maintenance for your database? That is, do you conduct thorough investigations regularly? You should. If you perform backups, then also do the checkup, it's equally important.
And we have such a tool. It has only begun to actively develop in the last three months. It's still young, but there's already a lot in it.
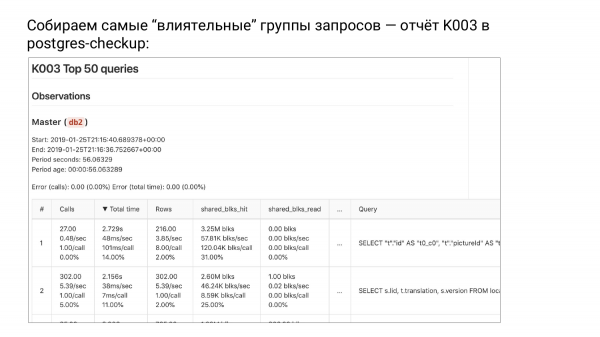
We gather the most "influential" query groups – report K003 in Postgres-checkup
And there is a group of reports K. Three reports for now. And there is the report K003. It contains the top items from pg_stat_statements, sorted by total_time.
When we sort the query groups by total_time, we see a group at the top that burdens our system the most, i.e., consumes the most resources. Why do I call them query groups? Because we've eliminated the parameters. These are no longer queries but groups of queries, meaning they are abstracted.
If we optimize from the top down, we will ease our resource usage and postpone the time when we need to upgrade. This is a great way to save money.
This may not be the best approach for user care, as we might not notice rare but annoying cases where someone waited 15 seconds. Overall, they are so rare that we don't see them, but we manage our resources.
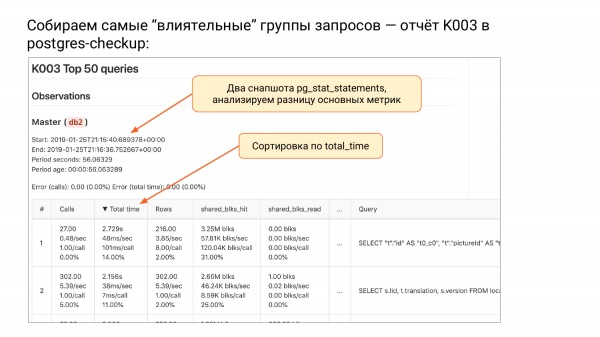
What happened in this table? We created two snapshots. Postgres_checkup will give you the delta for each metric: total-time, calls, rows, shared_blks_read, etc. That's it, the delta has been calculated. pg_stat_statements has a big problem in that it doesn't remember when it was reset. If pg_stat_database remembers, pg_stat_statements doesn't. You see that there is a number like 1,000,000, but we don't know where we counted from.
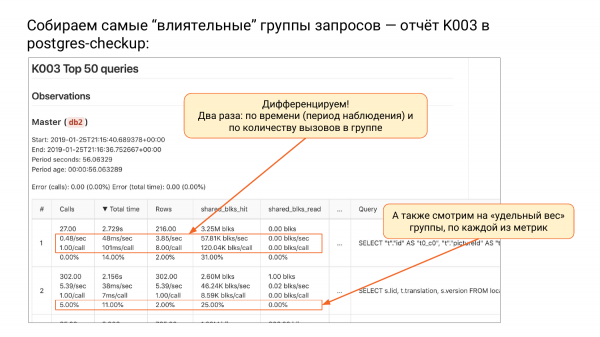
Here we know, we have two snapshots. We know that the delta in this case was 56 seconds. A very small interval. We sorted by total_time. Then we can differentiate, i.e., we divide all metrics by duration. If we divide each metric by duration, we will have the number of calls per second.
Next, total_time per second – this is my favorite metric. It is measured in seconds per second, i.e., how many seconds our system took to execute this group of queries per second. If you see more than one second per second, it means you need more than one core. This is a very good metric. You can understand, for example, that this user needs at least three cores.
This is our know-how; I've never seen anything like it. Pay attention – it's a very simple thing – seconds per second. Sometimes, when your CPU is at 100%, that means half an hour per second, i.e., you spent half an hour only on these queries.
Next, we see the rows per second. We know how many rows per second were returned.
And there’s another interesting thing. How many shared buffers were read per second from the shared buffers themselves. Hits were there, and the rows were taken from the operating system cache or from disk. The first option is fast, while the second may be fast or not, depending on the situation.
And the second method of differentiation involves dividing the number of requests in this group. In the second column, you will always have one request divided by another request. Then it gets interesting – how many milliseconds were spent on this request. We know how this request behaves on average. It took 101 milliseconds for each request. This is a traditional metric we need for understanding.
How many rows each request returned on average. We see this group returns 8. How many were taken and read from the cache on average. We see that everything is cached perfectly. There are solid hits for the first group.
And the fourth substring in each row is the percentage of the total number. We have calls. Let’s say, 1,000,000. And we can understand the contribution this group makes. In this case, we can see that the first group contributes less than 0.01%. That is, it is so slow that we do not see it in the overall picture. The second group accounts for 5% of the calls. That is, 5% of all calls are from the second group.
The total_time is also interesting. We spent 14% of the total working time on the first group of requests. On the second group, we spent 11%, and so on.
I won’t go into details, but there are nuances. We display an error at the top because when we compare, snapshots can drift, meaning some requests may drop out and may not be present in the second one, while others may appear anew. We compute the error there. If you see 0, it’s good. This means there are no errors. If the error rate is up to 20%, that’s OK.
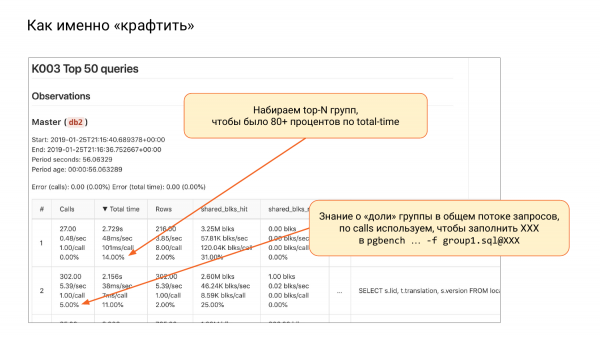
Next, we return to our topic. We need to craft the workload. We go from the top down until we reach 80% or 90%. Usually, this involves 10-20 groups. We create files for pgbench. There we use random. Sometimes, unfortunately, this doesn’t work out. And in Postgres 12, there will be more opportunities to use this approach.
And then we gather 80-90% on total_time this way. What should we put after "@"? We look at the calls, see what percentage there is, and understand that we need this much percent here. From these percentages, we can determine how to balance each of the files. After that, we use pgbench and start working.
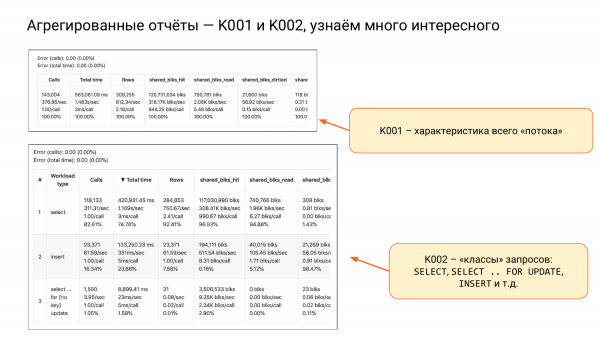
We also have K001 and K002.
K001 is one large string with four substrings. It characterizes the load as a whole. Look at the second column and the second substring. We see that it's about one and a half seconds per second, meaning that if there are two cores, it will be good. The load will be around 75%. And it will work like that. If we have 10 cores, we will be completely at ease. This way we can evaluate the resources.
K002 is what I call query classes, i.e. SELECT, INSERT, UPDATE, DELETE. And separately, SELECT FOR UPDATE, because it locks.
And here we can conclude that regular read SELECTs account for 82% of all calls, but 74% of total_time. That is, they are called a lot but consume resources less.
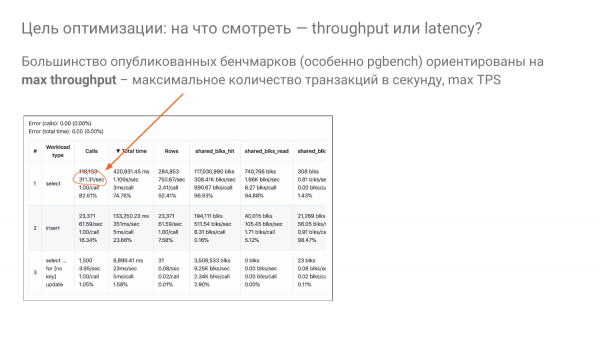
And we return to the question: "How do we correctly select shared_buffers?" I observe that most benchmarks are built on the idea – let's see what the throughput will be, i.e. what the capacity will be. This is usually measured in TPS or QPS.
And we try to squeeze as many transactions per second out of the machine through tuning parameters. Here, it is 311 per second for select.
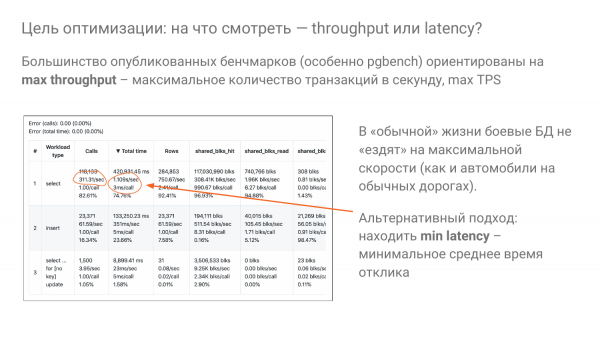
But no one drives to work and back home at full speed. That's silly. It's the same with databases. We shouldn’t operate at full speed, and no one does. No one lives in production with 100% CPU. Although maybe someone does, but that's not good.
The idea is that we usually drive at about 20% of capacity, preferably not above 50%. And we try to optimize response time for our users primarily. That is, we need to adjust our handles to have minimal latency at 20% speed, conditionally. This is an idea that we also try to use in our experiments.
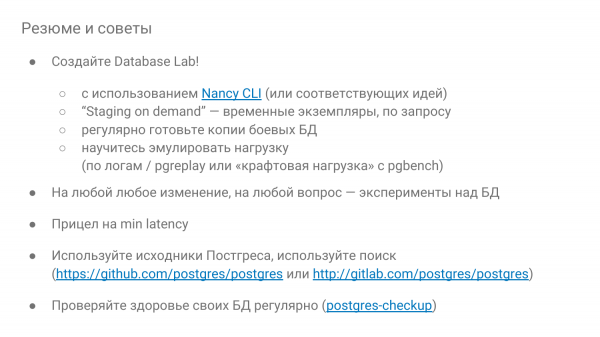
And finally, the recommendations:
- Be sure to create a Database Lab.
- If possible, make it on demand, so it can be deployed for a while – play around and then discard it. If you have cloud services, then this is a given, i.e. have many standing.
- Be curious. And if something is wrong, check through experiments how it behaves. You can use Nancy to educate yourself and see how the database works.
- And aim for minimal response time.
- And don’t be afraid of Postgres source codes. When working with source codes, you need to know English. There are many comments, everything is explained there.
- And check the health of the database regularly, at least once every three months manually or with Postgres-checkup.
Questions
Thank you very much! It's a very interesting thing.
Two things.
Yes, two things. But I don’t quite understand. When we work with Nancy, can we only tweak one parameter or an entire group?
We have a delta-config parameter. You can tweak as many as you want at once. But you need to understand that when you change too many things, you might draw incorrect conclusions.
Yes. Why did I ask? Because it's difficult to conduct experiments when you only have one parameter. You tweak it, see how it works, set it, and then move on to the next one.
You can tweak simultaneously, but it certainly depends on the situation. But it's better to test one idea. We had an idea yesterday. We had a very similar situation with two configs. And we couldn't understand why there was such a big difference. The idea arose that we should use dichotomy to sequentially grasp and find the difference. You can first make half the parameters the same, then a quarter, and so on. Everything is flexible.
And I have another question. The project is young and developing. Is there already detailed documentation ready?
I specifically made a link to the parameter descriptions. That exists. But there is still a lot that is not ready yet. I'm looking for like-minded individuals. And I find them when I present. It's really cool. Some are already working with me, some helped and did something there. And if you are interested in this topic, give feedback – what is lacking.
Once we set up the lab, we might get some feedback. We'll see. Thank you!
Hello! Thank you for the report! I saw that there is support for Amazon. Is support for GSP planned?
That's a good question. We've started working on it. For now, we've paused because we want to save costs. In other words, there's support by running on localhost. You can create an instance yourself and work locally. By the way, that's what we do. I do this in GitLab, using GSP. However, we don't currently see the point in creating that specific orchestration because Google doesn't offer cheap spot instances. They have ??? instances, but there are restrictions. First, there's always only a 70% discount, and you can't play with the pricing there. We increase the price of spots by 5-10% to reduce the likelihood of losing them. In other words, with spots you save money, but they can be taken away at any moment. If you set your prices slightly higher than others, you'll be phased out later. Google has a completely different specification. There is also a very unfavorable restriction—they only last for 24 hours. Sometimes we want to run an experiment for 5 days. But this can be done with spots, as they sometimes last for months.
Hello! Thank you for your presentation! You mentioned the checkup. How do you calculate the errors in stat_statements?
That's a very good question. I can explain and show it in detail. In short, we look at how a set of query groups has changed: how many have dropped off and how many new ones have appeared. Then we examine two metrics: total_time and calls, which gives us two errors. We also look at the contribution from the fluctuating groups. There are two subgroups: those that dropped off and those that arrived. We assess their contribution to the overall picture.
Aren't you concerned that it might catch on two or three times between snapshots?
In other words, did they register again or what?
For example, this query has already been evicted once, then returned and been evicted again, then came back once more and been evicted again. And you calculated something here, so where is all of it?
That's a good question; we need to look into it.
I've done a similar thing. Although it was simpler and I did it alone. But I had to reset the stat_statements and determine at the snapshot point that it was below a certain threshold, which meant it hadn't reached the ceiling of how many stat_statements it could accumulate. I'm orienting myself to the fact that, most likely, nothing was ejected.
Yes, yes.
But I don't understand how to do it reliably another way.
Unfortunately, I can't remember exactly whether we use the text of the query or the queryid with pg_stat_statements and base our conclusions on that. If we rely on queryid, then in theory, we're comparing comparable entities.
No, it can be overwritten several times between snapshots and come back again.
With the same ID?
Yes.
We'll look into this. Good question. We need to investigate. But so far, what we see is that we either write 0…
This is indeed a rare case, but I was shocked when I learned that stat_statements can be overwritten there.
There can be a lot in Pg_stat_statements. We've encountered that if you have track_utility = on, your sets are also being tracked.
Yes, of course.
And if you have a random Java Hibernate, then it starts locking the hash table. And as soon as you disable a heavily loaded application, you end up with 50-100 groups. And everything stabilizes more or less. One way to combat this is to increase pg_stat_statements.max.
Yes, but you need to know how much. And you need to monitor it somehow. That's what I do. That is, I have pg_stat_statements.max. And I check that at the time of the snapshot, I haven't reached 70%. Good, that means we haven't lost anything. We reset it. And start accumulating again. If in the next snapshot it’s below 70, then most likely, we haven’t lost anything again.
Yes. By default, it's currently 5,000. And that’s enough for many.
Usually - yes.
Video:
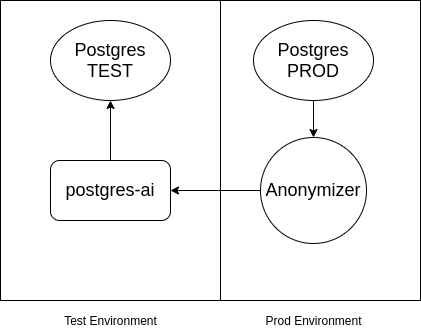
P.S. I would add that if there are confidential data in Postgres that shouldn't end up in the test environment, you can use . The scheme is roughly as follows:
Source: habr.com
