

This post was written because our employees had quite a few conversations with clients about application development on Kubernetes and the specifics of such development on OpenShift.
We usually start with the thesis that Kubernetes is simply Kubernetes, while OpenShift is a Kubernetes platform, similar to Microsoft AKS or Amazon EKS. Each of these platforms has its own advantages tailored to specific target audiences. After this, the discussion usually shifts to comparing the strengths and weaknesses of specific platforms.
Overall, we thought about writing this post with a conclusion like, "Listen, it doesn’t really matter where you run your code, on OpenShift or on AKS, EKS, some custom Kubernetes, or any Kubernetes," (for brevity, let’s call it KUK) — it’s really just as simple on both.
Then we planned to take a simple 'Hello World' example and show what is common and what the differences are between KUK and Red Hat OpenShift Container Platform (hereafter referred to as OCP or simply OpenShift).
However, as we were writing this post, we realized that we have become so accustomed to using OpenShift that we hardly recognize how it has grown and evolved into an amazing platform that has become much more than just a Kubernetes distribution. We tend to take the maturity and simplicity of OpenShift for granted, overlooking its greatness.
In general, the time for active reflection has come, and now we will step-by-step compare the deployment of our 'Hello World' on KUK and OpenShift, doing so as objectively as possible (though, we may express some personal opinions on the subject). If you are interested in a purely subjective opinion on this matter, you can read it . In this post, we will stick to the facts and only the facts.
Clusters
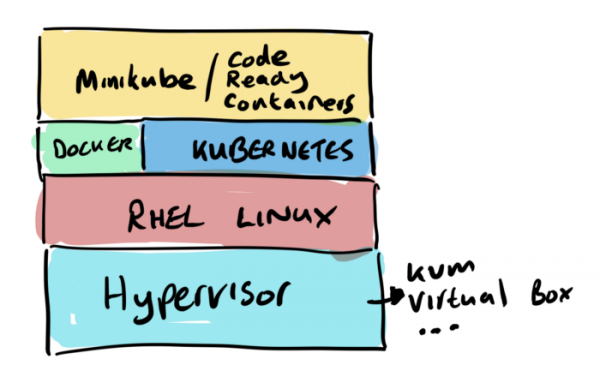
So, for our 'Hello World', we need clusters. Let's immediately say 'no' to any public clouds to avoid paying for servers, registries, networks, data transfer, etc. Accordingly, we choose a simple single-node cluster on (for KUK) and (for the OpenShift cluster). Both of these options are really simple to install, but will require quite a lot of resources on your laptop.
Building on KUK
So, let's get started.
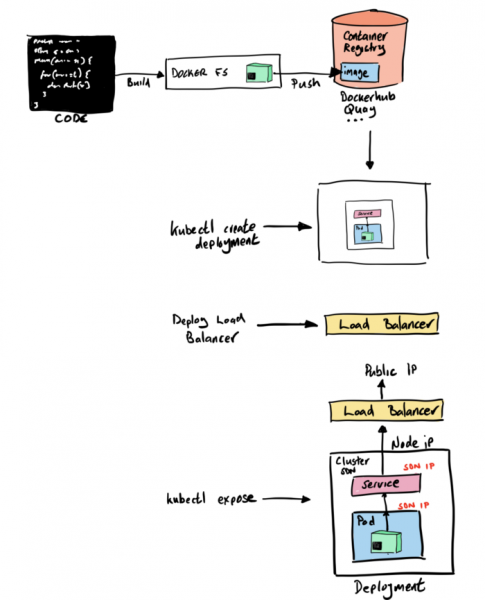
Step 1 - Let's build our container image
Let’s start by deploying our 'Hello World' on minikube. For this, we will need:
- 1. Installed Docker.
- 2. Installed Git.
- 3. Installed Maven (actually, this project uses the mvnw binary, so this is optional).
- 4. The source code itself, i.e., a clone of the repository
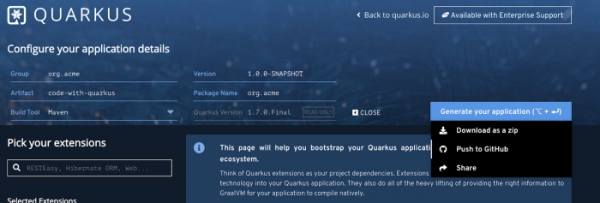
First, we need to create a Quarkus project. Don’t worry if you’ve never worked with the Quarkus.io site—it’s easy. Just select the components you want to use in your project (RestEasy, Hibernate, Amazon SQS, Camel, etc.), and then Quarkus will automatically set up the Maven archetype and deploy everything on GitHub without any input from you. That’s literally just one click of the mouse—and it’s done. This is why we love Quarkus.
The simplest way to build our 'Hello World' into a container image is to use the quarkus-maven extension for Docker, which will handle all the necessary work. With Quarkus, this has become really easy: you add the container-image-docker extension and can create images using Maven commands.
./mvnw quarkus:add-extension -Dextensions="container-image-docker"
And finally, we build our image using Maven. As a result, our source code turns into a ready-to-run container image that can be executed in a container runtime environment.
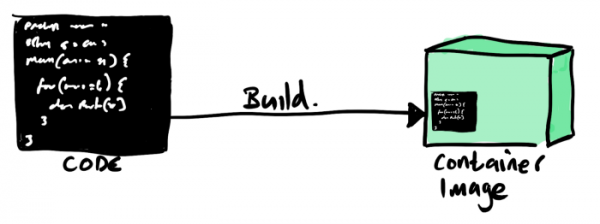
./mvnw -X clean package -Dquarkus.container-image.build=true
And that’s it; now you can run the container with the command docker run, mapping our service to port 8080 for access.
docker run -i --rm -p 8080:8080 gcolman/quarkus-hello-world
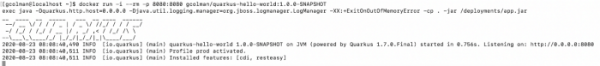
Once the container instance has started, you just need to check with the curl command that our service is working:

So, everything works, and it was really easy and straightforward.
Step 2 – pushing our container to the container image repository
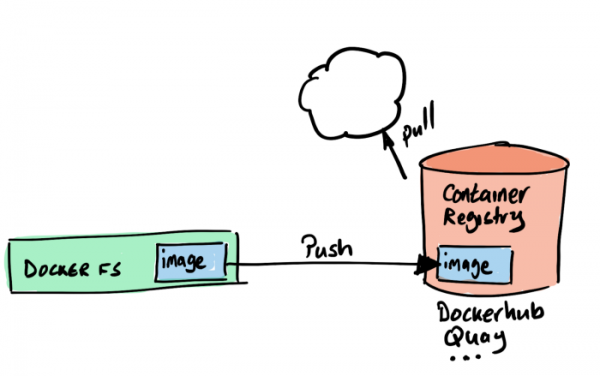
So far, our created image is stored locally in our local container repository. If we want to use this image in our K8s environment, we need to place it in another repository. Kubernetes doesn’t have such functionalities, so we will use Docker Hub. Firstly, it’s free, and secondly, (almost) everyone does it.
It’s also very simple; all you need is an account on Docker Hub.
So, let’s log into Docker Hub and push our image there.
Step 3 – starting Kubernetes
There are many ways to build a Kubernetes configuration to run our 'Hello World', but we will use the simplest one because that’s just who we are...
First, let’s start the minikube cluster:
minikube start
Step 4 – Deploying our container image
Now we need to transform our code and container image into Kubernetes configurations. In other words, we require a pod and deployment definition pointing to our container image on Docker Hub. One of the simplest ways to accomplish this is by running the create deployment command, specifying our image:
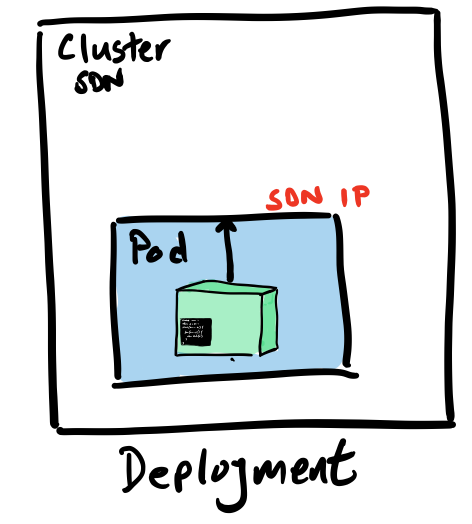
kubectl create deployment hello-quarkus --image=gcolman/quarkus-hello-world:1.0.0-SNAPSHOT
With this command, we instructed Kubernetes to create a deployment configuration that should include the pod specification for our container image. This command will also apply this configuration to our Minikube cluster, creating a deployment that pulls our container image and launches a pod in the cluster.
Step 5 – Opening access to our service
Now that we have the container image deployed, it's time to consider how to configure external access to this Restful service, which is indeed programmed in our code.
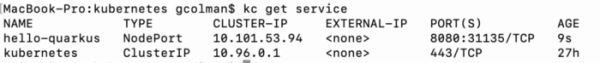
There are several ways to do this. For example, we can use the expose command to automatically create the necessary Kubernetes components, such as services and endpoints. Essentially, that’s what we will do by executing the expose command for our deployment object:
kubectl expose deployment hello-quarkus --type=NodePort --port=8080
Let's pause for a moment on the “--type” option of the expose command.
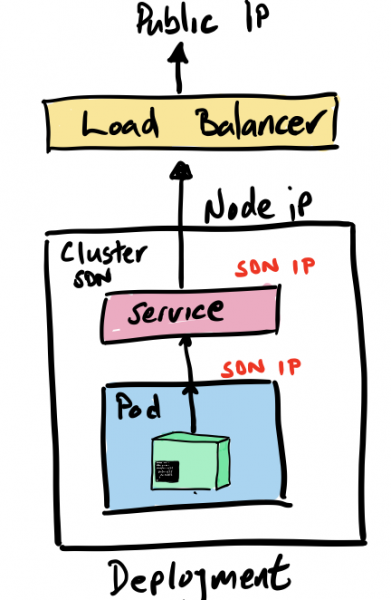
When we perform expose and create the components necessary for running our service, we need, among other things, to ensure that external access can connect to the hello-quarkus service, which resides within our software-defined network. The parameter type allows us to create and connect things like load balancers to route traffic into this network.
For example, specifying --type=LoadBalancer, we automatically initialize a load balancer in the public cloud to connect to our Kubernetes cluster. This is, of course, fantastic, but it’s essential to understand that such a configuration will be tightly bound to a specific public cloud and will be more challenging to transfer between Kubernetes instances across different environments.
In our example, --type=NodePort, meaning that the service call is made using the node's IP address and port number. This option allows not to use any public clouds but requires a number of additional steps. First, you need your own load balancer, so we will deploy an NGINX load balancer in our cluster.
Step 6 – Setting up the load balancer
Minikube has a number of platform-specific features that simplify the creation of necessary components for external access, such as ingress controllers. Minikube comes with an NGINX ingress controller, and all we need to do is enable and configure it.
minikube addons enable ingress
Now, with just one command, we can create an NGINX ingress controller that will operate within our minikube cluster:
ingress-nginx-controller-69ccf5d9d8-j5gs9 1/1 Running 1 33m
Step 7 – Configuring ingress
Now we need to configure the NGINX ingress controller to accept requests for hello-quarkus.
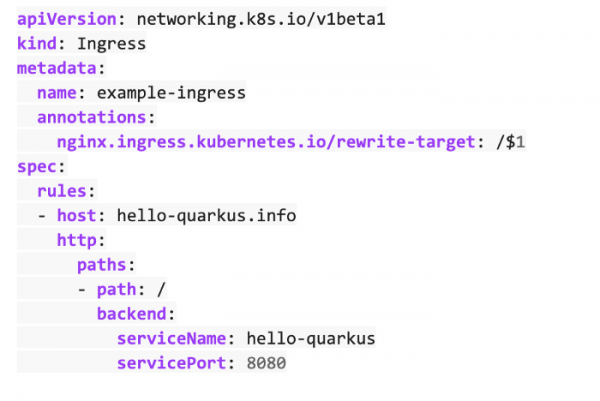
And finally, we need to apply this configuration.
kubectl apply -f ingress.yml

Since we're doing all this on our computer, we simply add the IP address of our node to the /etc/hosts file to direct HTTP requests to our minikube on the NGINX load balancer.
192.168.99.100 hello-quarkus.info
That's it, now our minikube service is accessible from the outside through the NGINX ingress controller.
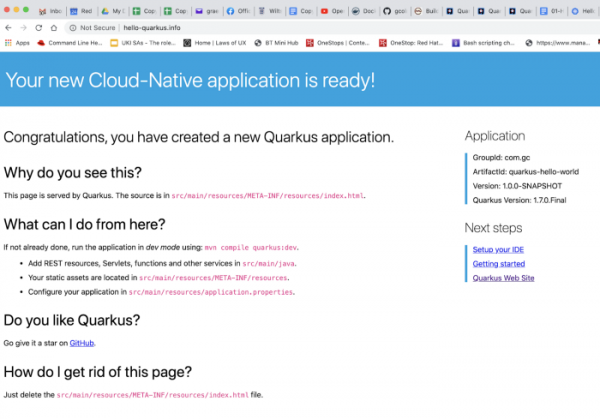
Well, that was easy, right? Or not quite?
Running on OpenShift (Code Ready Containers)
Now let's see how this is done on the Red Hat OpenShift Container Platform (OCP).
As with minikube, we choose a single-node OpenShift cluster scheme in the form of Code Ready Containers (CRC). Previously, this was called minishift and was based on the OpenShift Origin project, and now it is CRC built on Red Hat's OpenShift Container Platform.
Here we must say, 'OpenShift is wonderful!'
Initially, we thought to write that development on OpenShift is no different from development on Kubernetes. And in essence, that's true. But while writing this post, we recalled how many extra steps are required when you don't have OpenShift, and that's why it is, as we repeat, wonderful. We love when everything is easy, and the way our example deploys and runs on OpenShift compared to minikube inspired us to write this post.
Let's go through the process and see what we need to do.
So, in the minikube example, we started with Docker… Wait, we no longer need Docker to be installed on the machine.
And we don't need a local git.
And Maven is not needed either.
And there's no need to manually create a container image.
And there's no need to find a container image repository.
And there's no need to install an ingress controller.
And configuring ingress is also unnecessary.
You got it, right? To deploy and run our application on OpenShift, none of the above is required. The process looks like this.
Step 1 – Start your OpenShift cluster
We use Code Ready Containers from Red Hat, which is essentially the same as Minikube, but with a full single-node OpenShift cluster.
crc start
Step 2 – Build and deploy the application in the OpenShift cluster
This is where the simplicity and convenience of OpenShift shine. As with all Kubernetes distributions, we have many ways to launch an application in the cluster. And, as in the case of K8s, we deliberately choose the simplest option.
OpenShift has always been built as a platform for creating and running container applications. Building containers has always been an integral part of this platform, so there are plenty of additional Kubernetes resources for related tasks.
We will use OpenShift's Source 2 Image (S2I) process, which has several different ways to take our source (code or binary files) and turn it into a container image that can be run in the OpenShift cluster.
For this, we need two things:
- Our source code in a git repository
- A builder image on which the build will be executed.
There are many such images, supported both by Red Hat and at the community level, and we will use the OpenJDK image since I am building a Java application.
Starting the S2I build can be done from both the OpenShift Developer graphical console and the command line. We will use the new-app command, specifying where to get the builder image and our source code.
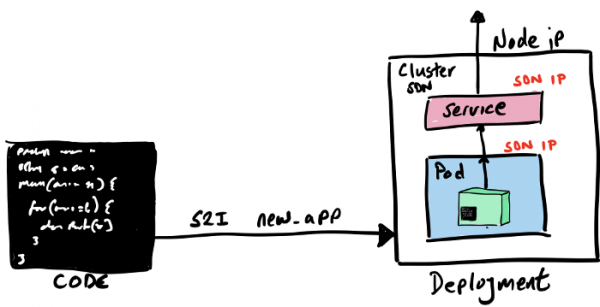
oc new-app registry.access.redhat.com/ubi8/openjdk-11:latest~https://github.com/gcolman/quarkus-hello-world.git
That's it, our application is created. The S2I process has performed the following actions:
- Created a service build pod for all things related to building the application.
- Created an OpenShift Build config.
- Downloaded the builder image to the internal OpenShift docker registry.
- Cloned 'Hello World' into the local repository.
- I saw that there is a Maven POM, so I compiled the application using Maven.
- I created a new container image containing the compiled Java application and stored this image in the internal container registry.
- I created a Kubernetes Deployment with specifications for the pod, service, etc.
- I launched the deployment of the container image.
- I deleted the temporary build pod.
There is a lot in this list, but the main thing is that the entire build process occurs entirely within OpenShift, the internal Docker registry is inside OpenShift, and the build process creates all the Kubernetes components and runs them in the cluster.
If you visually track the S2I launch in the console, you can see how the build pod is started during the build process.
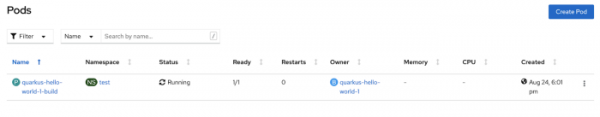
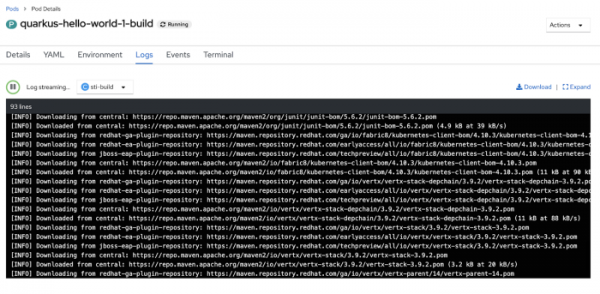
Now let's take a look at the logs of the builder pod: first of all, you can see how Maven does its job and downloads dependencies for building our Java application.
After the Maven build is complete, the container image build is initiated, and then this built image is sent to the internal repository.
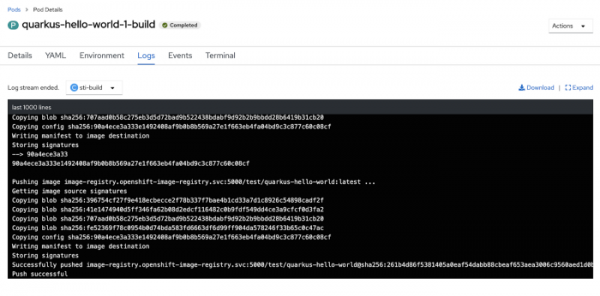
That's it, the build process is complete. Now let's verify that the pods and services of our application have started in the cluster.
oc get service
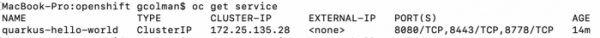
That's all. Only one command left. We just need to expose this service for external access.
Step 3 – expose the service for external access
As with the KUK, our 'Hello World' also needs a router on the OpenShift platform to direct external traffic to the service inside the cluster. OpenShift simplifies this greatly. First, the HAProxy routing component is installed by default in the cluster (it can be changed to the same NGINX). Second, there are special resources that offer extensive configuration options, called Routes, which resemble Ingress objects in the good old Kubernetes (in fact, OpenShift's Routes significantly influenced the design of Ingress objects, which can now also be used in OpenShift), but for our 'Hello World', and in most other cases, the standard Route will suffice without additional configuration.
To create a routable FQDN for 'Hello World' (yes, OpenShift has its own DNS for routing by service names), we simply perform expose for our service:
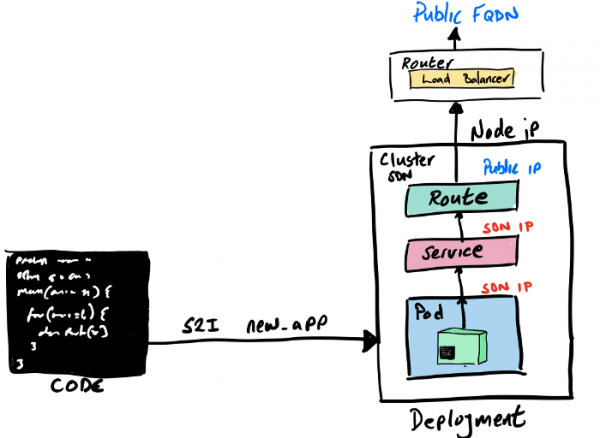
oc expose service quarkus-hello-world
If you look at the newly created Route, you can find the FQDN and other routing information:
oc get route

And finally, we access our service from the browser:
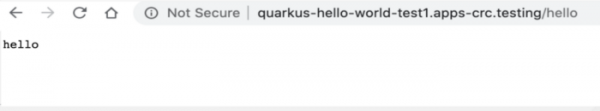
Well, that was really easy!
We love Kubernetes and everything this technology allows us to do, as well as the simplicity and ease it brings. Kubernetes was designed to dramatically simplify the operation of distributed scalable containers, but today its simplicity is no longer enough for deploying applications. This is where OpenShift comes into play, keeping up with the times and offering Kubernetes primarily focused on developers. A tremendous amount of effort has gone into tailoring the OpenShift platform specifically for developers, including the creation of tools such as S2I, ODI, Developer Portal, OpenShift Operator Framework, integration with IDEs, Developer Catalogues, Helm integration, monitoring, and many more.
We hope this article has been interesting and useful to you. Additional resources, materials, and other helpful items for development on the OpenShift platform can be found on the .
Source: habr.com
