

In the previous article, I discussed the fundamentals of DATA VAULT, describing its main elements and their purposes. However, the topic of DATA VAULT is not exhausted; it's necessary to talk about the subsequent stages of the evolution of DATA VAULT.
In this article, I will focus on the development of DATA VAULT and its transition to BUSINESS DATA VAULT or simply BUSINESS VAULT.
Reasons for the emergence of BUSINESS DATA VAULT
It should be noted that while DATA VAULT has certain strengths, it is not without its weaknesses. One such drawback is the complexity of writing analytical queries. Queries typically involve a significant number of JOINs, resulting in lengthy and cumbersome code. Additionally, the data entering DATA VAULT undergoes no transformations, which means that from a business perspective, DATA VAULT in its pure form does not hold unconditional value.
It is precisely to address these shortcomings that the DATA VAULT methodology has been expanded to include elements such as:
- PIT (point in time) tables;
- BRIDGE tables;
- PREDEFINED DERIVATIONS.
Let’s take a closer look at the purpose of these elements.
PIT tables
Generally, a single business object (HUB) may contain data with varying update frequencies. For instance, when it comes to data characterizing a person, we can state that information like phone numbers, addresses, or email addresses is updated more frequently than, say, full name, passport data, marital status, or gender.
Therefore, when defining satellites, it is essential to consider the frequency of their updates. Why is this important?
If attributes with different update frequencies are stored in one table, it will be necessary to add a row to the table upon each update of the most frequently changing attribute. As a result, this leads to an increase in disk space usage and longer query execution times.
Now that we have separated satellites by update frequency, allowing us to load data into them independently, we should ensure the ability to obtain current data. Ideally, without the use of excessive JOINs.
For example, suppose we need to obtain current (based on the last update date) information from satellites that have different refresh frequencies. This requires not only performing JOINs but also creating several nested queries (for each satellite containing the information) to select the maximum update date MAX(Update Date). With each new JOIN, such code expands and quickly becomes difficult to understand.
The PIT table is designed to simplify such queries; PIT tables are populated simultaneously with the recording of new data in the DATA VAULT. PIT Table:
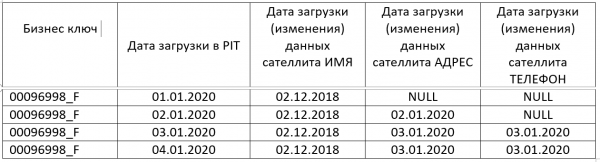
Thus, we have information about the currency of the data across all satellites at any given time. By using JOINs with the PIT table, we can completely eliminate nested queries, given the condition that the PIT is filled every day without gaps. Even if there are gaps in the PIT, current data can be obtained using just one nested query to the PIT itself. One nested query will perform faster than multiple nested queries to each satellite.
BRIDGE
BRIDGE-type tables are also used to simplify analytical queries. However, unlike the PIT, they serve to simplify and speed up queries between different hubs, links, and their satellites.
The table contains all necessary keys for all satellites that are frequently used in queries. Additionally, when needed, hashed business keys can be supplemented with text keys if the names of keys are required for analysis.
The fact is that without using BRIDGE, when retrieving data from satellites belonging to different hubs, it will be necessary to perform JOINs not only of the satellites themselves but also of the links connecting the hubs.
The presence or absence of a BRIDGE is determined by the configuration of the warehouse and the need to optimize the speed of query execution. It is difficult to come up with a universal example of a BRIDGE.
PREDEFINED DERIVATIONS
Another type of object that brings us closer to the BUSINESS DATA VAULT is tables containing pre-calculated metrics. Such tables are indeed important for business; they contain information aggregated according to specified rules and allow relatively easy access to it.
Architectural PREDEFINED DERIVATIONS are nothing more than another satellite of a specific hub. Like a regular satellite, it contains a business key and the date of record creation in the satellite. However, this is where the similarities end. The further composition of attributes for such a "specialized" satellite is determined by business users based on the most in-demand, pre-calculated metrics.
For example, a hub containing information about an employee may include a satellite with metrics such as:
- Minimum salary;
- Maximum salary;
- Average salary;
- Cumulative total of calculated salaries, etc.
It makes sense to include PREDEFINED DERIVATIONS in the PIT table of this same hub, then it will be easy to obtain data slices by employee on a specifically selected date.
CONCLUSIONS
As practice shows, the use of DATA VAULT can be somewhat challenging for business users for several reasons:
- The query code is complex and cumbersome;
- The abundance of JOINs affects the performance of queries;
- Outstanding knowledge of the structure of the repository is required to write analytical queries.
To simplify access to data, DATA VAULT is expanded with additional objects:
- PIT (point in time) tables;
- BRIDGE tables;
- PREDEFINED DERIVATIONS.
In the next I plan to discuss, in my opinion, the most interesting aspects for those who work with BI. I will present methods for creating fact tables and dimension tables based on DATA VAULT.
The materials of the article are based on:
- At Kenta Graziano, which contains detailed descriptions and model diagrams;
- The book: "Building a Scalable Data Warehouse with DATA VAULT 2.0";
- Article .
Source: habr.com
