

A few months ago — a public for PostgreSQL.
In the time since, you have already used it over 6000 times, but one of its convenient features may have gone unnoticed — that is structural hints, which look something like this:
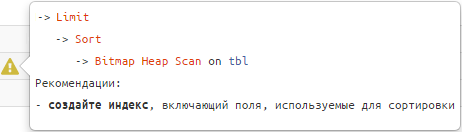
Listen to them, and your queries will become 'smooth and silky'. 🙂
In all seriousness, many situations that make a query slow and 'resource-hungry' are common and can be identified by the structure and data of the plan..
In this case, each individual developer won't need to find an optimization option on their own, relying solely on their experience — we can suggest what is happening here, what might be the cause, and how to approach the solution. And that's exactly what we did.
Let's take a closer look at these cases — how they are identified and what recommendations they lead to.
For a better understanding of the topic, you can first listen to the relevant section from , and then move on to a detailed analysis of each example:
#1: индексная «недосортировка»
When it arises
Show the latest invoice for the client 'LLC Kolokolchik'.
How to identify
-> Limit
   -> Sort
      -> Index [Only] Scan [Backward] | Bitmap Heap Scan
Recommendations
Used index extend with sorting fields.
Example:
CREATE TABLE tbl AS
SELECT
  generate_series(1, 100000) pk  -- 100K "facts"
, (random() * 1000)::integer fk_cli; -- 1K different foreign keys

CREATE INDEX ON tbl(fk_cli); -- index for foreign key

SELECT
  *
FROM
  tbl
WHERE
  fk_cli = 1 -- filtering by a specific connection
ORDER BY
  pk DESC -- we want only one "latest" record
LIMIT 1; 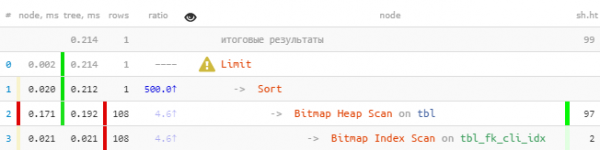
It is immediately noticeable that more than 100 records were read by the index, which were then all sorted, and only one was retained.
Fixing it:
DROP INDEX tbl_fk_cli_idx;
CREATE INDEX ON tbl(fk_cli, pk DESC); -- added sorting key
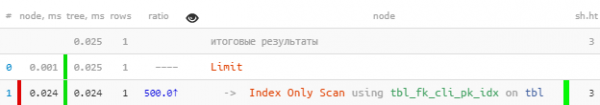
Even on such a primitive selection — 8.5 times faster and 33 times fewer reads.The effect will be even more evident the more 'facts' you have for each value fk.
I note that such an index will work as a 'prefix' no worse than the previous one for other queries with fk, where there was and is no sorting by pk You can read more about this ). It will also provide normal support for the explicit foreign key for this field.
#2: пересечение индексов (BitmapAnd)
When it arises
Show all contracts for client "LLC Bell" made on behalf of "NAO Lyutik".
How to identify
-> BitmapAnd
   -> Bitmap Index Scan
   -> Bitmap Index Scan
Recommendations
Create composite index from fields of both sources or extend one of the existing ones with fields from the second.
Example:
CREATE TABLE tbl AS
SELECT
  generate_series(1, 100000) pk      -- 100K "facts"
, (random() *  100)::integer fk_org  -- 100 different foreign keys
, (random() * 1000)::integer fk_cli; -- 1K different foreign keys

CREATE INDEX ON tbl(fk_org); -- index for foreign key
CREATE INDEX ON tbl(fk_cli); -- index for foreign key

SELECT
  *
FROM
  tbl
WHERE
(fk_org, fk_cli) = (1, 999); -- filtering by a specific pair 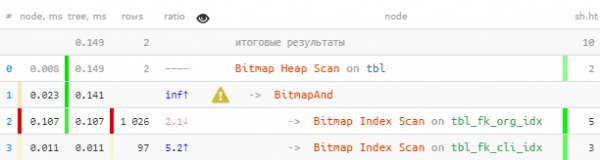
Fixing it:
DROP INDEX tbl_fk_org_idx;
CREATE INDEX ON tbl(fk_org, fk_cli);
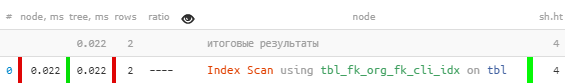
Here the gain is less, since Bitmap Heap Scan is effective enough on its own. But still 7 times faster and 2.5 times fewer reads.
#3: объединение индексов (BitmapOr)
When it arises
Show the first 20 oldest "own" or unassigned requests for processing, giving preference to own requests.
How to identify
-> BitmapOr
   -> Bitmap Index Scan
   -> Bitmap Index Scan
Recommendations
Use UNION [ALL] to combine subqueries for each of the OR condition blocks.
Example:
CREATE TABLE tbl AS
SELECT
  generate_series(1, 100000) pk  -- 100K "facts"
, CASE
    WHEN random() < 1::real/16 THEN NULL -- with a probability of 1:16 the record is "draw"
    ELSE (random() * 100)::integer -- 100 different foreign keys
  END fk_own;

CREATE INDEX ON tbl(fk_own, pk); -- index with "seemingly suitable" sorting

SELECT
  *
FROM
  tbl
WHERE
  fk_own = 1 OR -- own
  fk_own IS NULL -- ... or "draw"
ORDER BY
  pk
, (fk_own = 1) DESC -- own first
LIMIT 20;
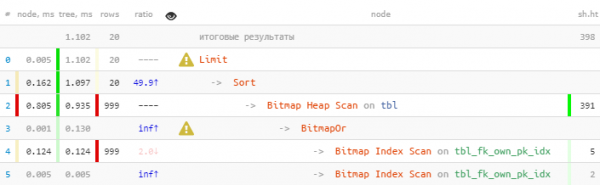
Fixing it:
(
  SELECT
    *
  FROM
    tbl
  WHERE
    fk_own = 1 -- own first 20
  ORDER BY
    pk
  LIMIT 20
)
UNION ALL
(
  SELECT
    *
  FROM
    tbl
  WHERE
    fk_own IS NULL -- then "draw" 20
  ORDER BY
    pk
  LIMIT 20
)
LIMIT 20; -- but total - 20, no more needed 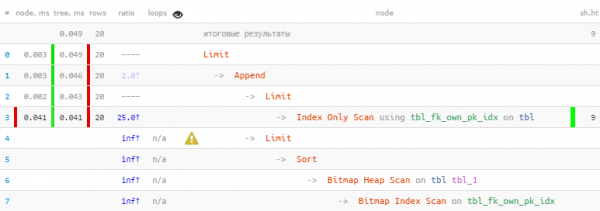
We took advantage of the fact that all 20 required records were retrieved in the first block, so the second, with the more "expensive" Bitmap Heap Scan, was not even executed — as a result 22 times faster, 44 times fewer reads!
A more detailed discussion of this optimization method with specific examples can be found in articles and .
Generalized version of ordered selection by multiple keys (not just by const/NULL pair) is discussed in the article .
#4: читаем много лишнего
When it arises
Typically arises when there is a desire to "attach another filter" to an already existing query.
"Don't you have something similar, but with mother-of-pearl buttons?» from the movie "The Diamond Arm"
For example, modifying the above task to show the first 20 oldest "critical" requests for processing, regardless of their assignment.
How to identify
-> Seq Scan | Bitmap Heap Scan | Index [Only] Scan [Backward]
   && 5 × rows 80% of what was read
   && loops × RRbF > 100 -- and more than 100 records in total
Recommendations
Create [more] specialized index with a WHERE condition or include additional fields in the index.
If the filtering condition is 'static' for your tasks — that is, does not foresee an extension of the list of values in the future — it is better to use a WHERE index. Various boolean/enum statuses fit well into this category.
If the filtering condition can take different values, it is better to expand the index with these fields — as in the case with BitmapAnd above.
Example:
CREATE TABLE tbl AS
SELECT
  generate_series(1, 100000) pk -- 100K "facts"
, CASE
    WHEN random() < 1::real/16 THEN NULL
    ELSE (random() * 100)::integer -- 100 different foreign keys
  END fk_own
, (random() < 1::real/50) critical; -- 1:50, that the request is "critical"

CREATE INDEX ON tbl(pk);
CREATE INDEX ON tbl(fk_own, pk);

SELECT
  *
FROM
  tbl
WHERE
  critical
ORDER BY
  pk
LIMIT 20; 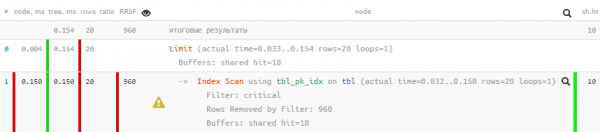
Fixing it:
CREATE INDEX ON tbl(pk)
  WHERE critical; -- added a "static" filtering condition
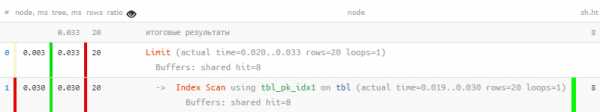
As we can see, the filtering from the plan has completely disappeared, and the query has become 5 times faster.
#5: разреженная таблица
When it arises
Various attempts to create a custom task processing queue, where a large number of updates/deletions of records in the table lead to a situation with a large number of "dead" records.
How to identify
-> Seq Scan | Bitmap Heap Scan | Index [Only] Scan [Backward]
   && loops × (rows + RRbF)  64
Recommendations
Regularly perform manually VACUUM [FULL] or achieve adequately frequent execution by properly tuning its parameters, including .
In most cases, such problems turn out to be caused by poor query composition in calls from business logic like those discussed in .
But it should be understood that even VACUUM FULL may not always help. In such cases, it is worth getting acquainted with the algorithm from the article .
#6: чтение с «середины» индекса
When it arises
It seems that we read a little, all through the index, and filtered no unnecessary records — yet significantly more pages were read than desired.
How to identify
-> Index [Only] Scan [Backward]
   && loops × (rows + RRbF)  64
Recommendations
Take a close look at the structure of the index used and the key fields specified in the query — most likely, part of the index is not defined. You will probably need to create a similar index, but without the prefix fields or .
Example:
CREATE TABLE tbl AS
SELECT
  generate_series(1, 100000) pk      -- 100K "facts"
, (random() *  100)::integer fk_org  -- 100 different foreign keys
, (random() * 1000)::integer fk_cli; -- 1K different foreign keys

CREATE INDEX ON tbl(fk_org, fk_cli); -- almost everything as in #2
-- only we have already deemed a separate index on fk_cli unnecessary and removed it

SELECT
  *
FROM
  tbl
WHERE
  fk_cli = 999 -- but fk_org is not defined, although it is listed earlier in the index
LIMIT 20; 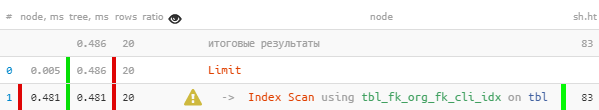
Everything seems fine, even by the index, but somehow suspicious — for each of the 20 read records, I had to read 4 data pages, 32KB per record — isn't that too much? And the index name tbl_fk_org_fk_cli_idx raises some questions.
Fixing it:
CREATE INDEX ON tbl(fk_cli); 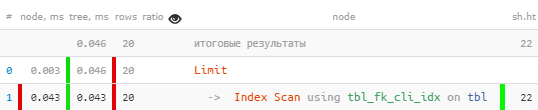
Suddenly — 10 times faster, and read 4 times less!
Other examples of inefficient index usage can be found in the article .
#7: CTE × CTE
When it arises
In the query we gathered "fat" CTEs from different tables, and then decided to create a connection between them JOIN.
This case is relevant for versions lower than v12 or queries with WITH MATERIALIZED.
How to identify
-> CTE Scan
   && loops > 10
   && loops × (rows + RRbF) > 10000
      -- too large a Cartesian product of CTE
Recommendations
Carefully analyze the query — do we even need CTEs here? ? Если все-таки да, то based on the model described in One-time processing (sorting or unifying) of a large number of records does not fit into the memory allocated for this purpose. .
#8: swap на диск (temp written)
When it arises
-> * && temp written > 0
How to identify
If the amount of memory used by the operation does not exceed the set limit of the parameterRecommendations
work_mem SET [LOCAL] for a specific query/transaction. SHOW work_mem; -- "16MB"SELECT random() FROM generate_series(1, 1000000) ORDER BY 1;
Example:
SET work_mem = '128MB'; -- before executing the query 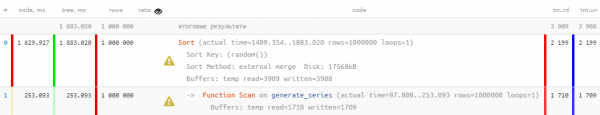
Fixing it:
For obvious reasons, if only memory is used, rather than disk, the query will be executed much faster. At the same time, the load on the HDD is also reduced. 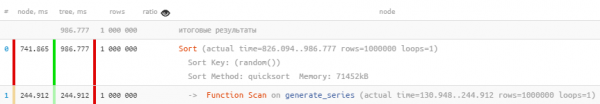
But it should be understood that allocating a lot of memory will also not always be possible — there simply may not be enough for everyone.
A lot was poured into the database at once, but we didn’t manage to run
#9: неактуальная статистика
When it arises
ANALYZE -> Seq Scan | Bitmap Heap Scan | Index [Only] Scan [Backward] && ratio >> 10.
How to identify
UltimatelyRecommendations
Conduct the analysis -> Seq Scan | Bitmap Heap Scan | Index [Only] Scan [Backward] && ratio >> 10.
More details about this situation are described in .
#10: «что-то пошло не так»
When it arises
There was a wait for a lock imposed by a competing query, or there were insufficient CPU/hypervisor resources.
How to identify
-> *
   && (shared hit / 8K) + (shared read / 1K) < time / 1000
      -- RAM hit = 64MB/s, HDD read = 8MB/s
   && time > 100ms -- read less, but took too long
Recommendations
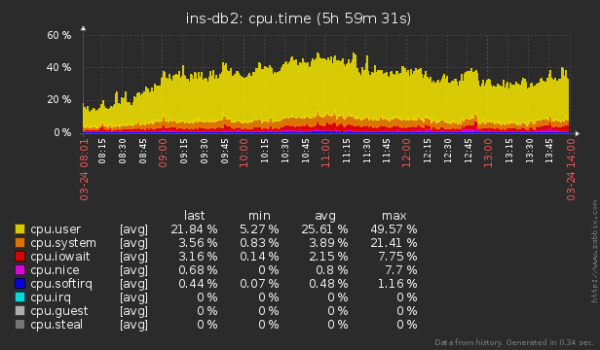
Use an external monitoring system for servers to check for locks or unusual resource consumption. We have already discussed our approach to organizing this process for hundreds of servers. and .
Source: habr.com
