

Ideas and meetings about what other processes can be automated arise in businesses of all sizes on a daily basis. However, aside from the significant time needed to create a model, it is also essential to spend time evaluating it and verifying that the results are not random. After implementation, every model must be monitored and periodically checked.
These are all stages that any company, regardless of its size, must go through. When talking about the scale and legacy of Sberbank, the number of intricate settings increases exponentially. By the end of 2019, Sber was already using more than 2000 models. It is not enough to just develop a model; it is necessary to integrate with industrial systems, create data showcases for model building, and ensure monitoring of its operation on the cluster.
Our team is developing the Sber.DS platform. It tackles machine learning tasks, accelerates the hypothesis testing process, simplifies the development and validation of models, and controls the performance results of the model in production.
To avoid disappointing your expectations, I want to say in advance that this post is introductory and, for starters, will discuss what is essentially under the hood of the Sber.DS platform. We will tell the story of the model's lifecycle from creation to deployment separately.
Sber.DS consists of several components, the key ones being the library, the development system, and the model execution system.
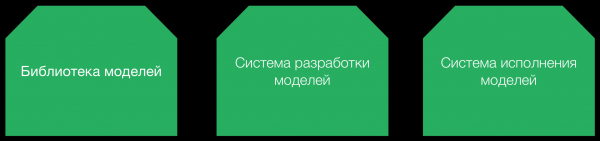
The library manages the model's lifecycle from the moment an idea to develop it arises until it is implemented in production, monitored, and decommissioned. Many capabilities of the library are dictated by regulatory requirements, such as reporting and storage of training and validation data samples. In fact, it is a registry of all our models.
The development system is designed for visual model development and validation methodologies. Developed models undergo initial validation and are supplied to the execution system to perform their business functions. Moreover, in the execution system, a model can be placed on monitor for periodic activation of validation methodologies to ensure control over its operation.
The system has several types of nodes. Some are designed for connecting to various data sources, while others are for transforming raw data and enriching it (through markup). There are many nodes for building different models and nodes for their validation. Developers can load data from any sources, transform, filter, and visualize intermediate data, breaking it into parts.
The platform also contains ready-made modules that can be dragged into the project area. All actions are performed using a visual interface. In fact, tasks can be solved without writing a single line of code.
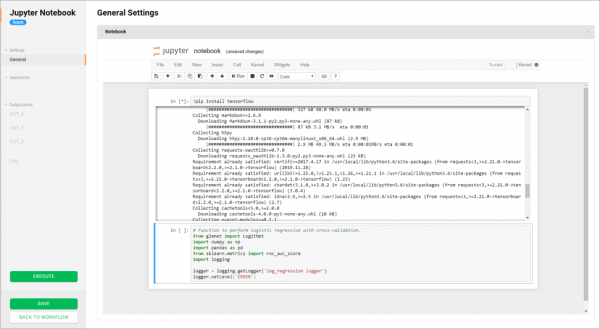
If the built-in capabilities are insufficient, the system provides a way to quickly create custom modules. We have developed an integrated development mode based on for those creating new modules from scratch.
The architecture of Sber.DS is built on microservices. There are many opinions about what microservices are. Some believe it is enough to break monolithic code into parts, but they still access the same database. In our case, a microservice should communicate with another microservice only via REST API. No workarounds for accessing the database directly.
We strive to keep services from becoming too large and cumbersome: a single instance should not consume more than 4-8 gigabytes of RAM and must allow for horizontal scaling of requests by launching new instances. Each service communicates with others only via REST API (). The team responsible for the service must maintain API backward compatibility for the last client using it.
The core of the application is written in Java using the Spring Framework. The solution was originally designed for rapid deployment in cloud infrastructure, so the application is built using a containerization system (). The platform is constantly evolving, both in terms of expanding business functionality (new connectors and AutoML are being added) and in terms of technological efficiency.
One of the standout features of our platform is that we can run code developed in a visual interface on any execution system of Sberbank models. Currently, there are two: one on Hadoop, and the other on OpenShift (Docker). We are not stopping there and are creating integration modules to run code on any infrastructure, including on-premise and in the cloud. Regarding the ability to effectively integrate into Sberbank's ecosystem, we also plan to support existing execution environments. In the future, the solution can be flexibly integrated 'out of the box' into any landscape of any organization.
Those who have ever tried to maintain a solution running Python on Hadoop in a production environment know that preparing and delivering a user Python environment to each data node is just the beginning. A multitude of C/C++ libraries for machine learning that utilize Python modules will keep you on your toes. It's crucial not to forget to update packages when adding new libraries or servers, while maintaining backward compatibility with the already deployed model code.
There are several approaches to accomplishing this. For example, pre-preparing a set of commonly used libraries and integrating them into the production environment. In the Cloudera Hadoop distribution, this is typically done using . Additionally, Hadoop now offers the ability to run -containers. In some simple cases, you can package the code together with .
The bank takes the security of running third-party code very seriously, so we leverage new capabilities of the Linux kernel as much as possible, where a process running in an isolated environment can be restricted, for instance, in terms of network and local disk access, which significantly reduces the potential for malicious code. The data areas of each department are protected and accessible only to the owners of that data. The platform ensures that data from one area can only enter another area through a data publication process with controls at all stages from access to sources to the landing of data in the target showcase. .
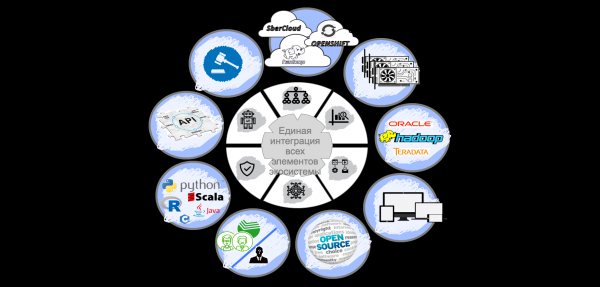
This year we plan to complete the MVP launch of models written in Python/R/Java on Hadoop. We have set ourselves an ambitious goal to learn how to launch any custom environment on Hadoop, so as not to limit the users of our platform in any way.
Moreover, it turns out that many data science specialists have a solid understanding of mathematics and statistics, creating great models, but they may not be very well-versed in big data transformations, requiring assistance from our data engineers for preparing training datasets. We decided to help our colleagues by creating convenient modules for standard transformations and feature preparation for models on the Spark engine. This will allow more time for model development without having to wait for data engineers to prepare a new dataset.
We have people with knowledge in various fields: Linux and DevOps, Hadoop and Spark, Java and Spring, Scala and Akka, OpenShift and Kubernetes. Next time, we will talk about the model library, how a model goes through its lifecycle within the company, and how validation and implementation occur.
Source: habr.com
