

Ansible DevOps Coding Style
Hey! My name is I work as an engineer in the process automation department. Every day, new application builds are deployed on hundreds of the company's servers. In this article, I share my experience using Ansible for these purposes.
This guide offers a way to organize variables in deployment. It is intended for those who already use roles in their playbooks and have read , but face similar issues:
- Finding a variable in the code makes it hard to immediately understand what it is for;
- There are several roles, and the variables need to be linked with a single value, but it's not working;
- There are difficulties in explaining to others how the logic of variables in your playbooks works.
We faced these problems in projects within our company, which led us to establish rules for formatting variables in our playbooks that somewhat resolved these issues.
Variables in Roles
A role is a separate object in the deployment system. Like any object in the system, it must have an interface for interaction with the rest of the system. This interface consists of the role's variables.
For example, let's take a role api, which installs a Java application on a server. What variables could it have?
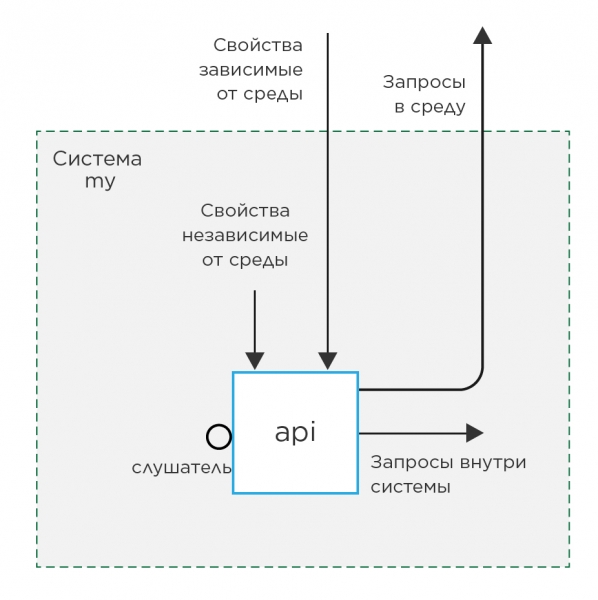
Role variables can be divided into 2 types:
1. Properties
    a) independent of the environment
    b) dependent on the environment
2. Relationships
    a) listeners
    b) internal system requests
    c) external requests
Property Variables — these are variables that define the behavior of the role.
Request Variables — these are variables whose values are used to denote external resources in relation to the role.
Listener Variables — these are variables whose values are used to form request variables.
On the other hand, 1a, 2a, 2b are variables that do not depend on the environment (hardware, external resources, etc.) and can be filled with default values in the role's defaults. However, variables of type 1b and 2c cannot be filled with anything other than 'example', as they will change from stand to stand depending on the environment.
Code Style
- The variable name must start with the role name. This will make it easier to understand later what role the variable comes from and what it is responsible for.
- When using variables in roles, you must adhere to the principle of encapsulation and use variables defined either within the role itself or in the roles from which the current one depends.
Avoid using dictionaries for variables. Ansible does not allow for convenient overriding of individual values in a dictionary.
Example of a poor variable:
myrole_user:
    login: admin
    password: admin
Here, login is an environment-independent variable, while password is dependent. However,
since they are combined in a dictionary, you will have to specify it fully
every time. Which is very inconvenient. Better like this:myrole_user_login: admin myrole_user_password: admin
Variables in deployment playbooks
When composing a deployment playbook (hereafter referred to as playbook), we adhere to the rule that it should be placed in a separate repository. Just like roles: each in its own git repository. This allows us to understand that roles and playbooks are different independent objects of the deployment system, and changes in one object should not affect the operation of another. This is achieved by changing the default values of variables.
When composing a playbook, generally speaking, there is an option to override the default values of role variables in two places: in playbook variables and in inventory variables.
mydeploy                        # Deployment directory
├── deploy.yml                  # Deployment playbook
├── group_vars                  # Playbook variables directory
│   ├── all.yml                 # File for system-wide variables
│   └── myapi.yml               # File for group property variables myapi
└── inventories                 #
    └── prod                    # Production environment directory
        ├── prod.ini            # Inventory file
        └── group_vars          # Directory for inventory variables
            └── myapi           #
                ├── vars.yml    # Environment-independent variables for group myapi
                └── vault.yml   # Secrets (always environment-dependent) *
* —
The difference is that playbook variables are always used when calling playbooks located at the same level. This means these variables are well-suited for changing the default values of environment-independent variables. Conversely, inventory variables will only be used for specific environments, which is ideal for environment-dependent variables.
It is important to note that the priority of variables will not allow you to redefine variables first in playbook variables, and then separately in an inventory.
This means that at this stage, you need to decide whether the variable is environment-dependent or not and place it in the appropriate location.
For example, in one project, a variable responsible for enabling SSL was environment-dependent for a long time because we could not enable SSL for reasons beyond our control on one of the servers. After we resolved this issue, it became environment-independent and was moved to the playbook variables.
Property variables for groups
Let's extend our model from Figure 1 by adding 2 server groups with a different Java application, but with different settings.
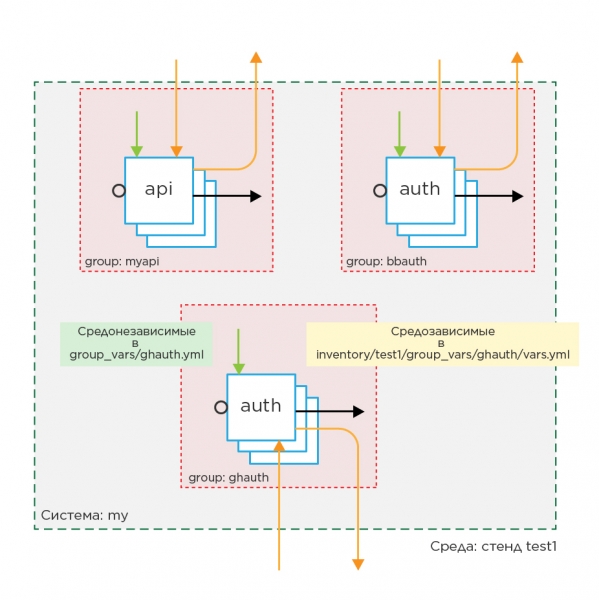
Let's see how the playbook would look in this case:
- hosts: myapi
  roles:
    - api

- hosts: bbauth
  roles:
    - auth

- hosts: ghauth
  roles:
    - auth
We have three groups in the playbook, so it's advisable to create the same number of group files in group_vars for both inventory variables and playbook variables. Each group file, in this case, describes one component of your application in the playbook. When you open the group file in the playbook variables, you immediately see all the differences from the default behavior of the roles assigned to the group. In the inventory variables: the differences in group behavior from one setup to another.
Code Style
- Try to avoid using host_vars variables altogether, as they do not describe the system but only a specific case, which will eventually lead to questions like: "Why does this host differ from the others?", the answer to which is not always easy to find.
Link variables
However, this pertains to property variables, but what about link variables?
The difference is that they must have the same value across different groups.
At first, there was to use a monstrous construct like:
hostvars[groups['bbauth'][0]]['auth_bind_port'], but it was immediately discarded
because it has its drawbacks. First, its bulkiness. Second, the dependence on a specific host in the group. Third, facts must be gathered from all hosts before deployment if we want to avoid undefined variable errors.
Ultimately, it was decided to use link variables.
Link variables These are variables belonging to the playbook, necessary for linking system objects.
Linking variables are filled in the system's global variables. group_vars/all/vars and are formed by extracting all listener variables from each group and adding the group's name from which the listener was extracted at the beginning of the variable.
This ensures consistency and non-intersecting names.
Let's try to connect the variables from the example above:
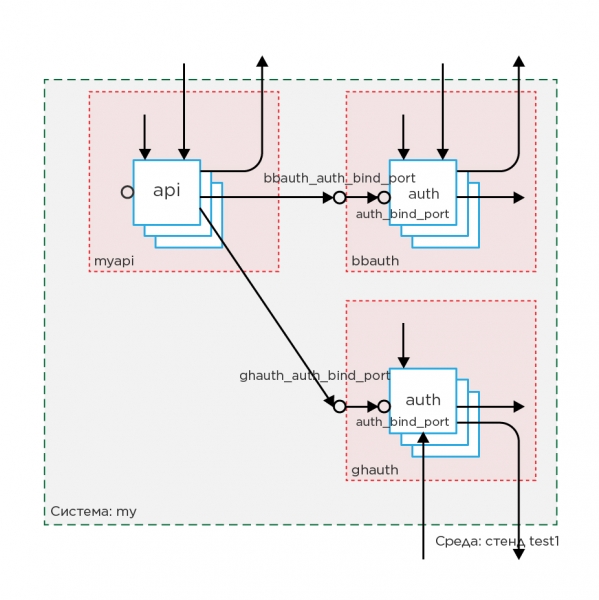
Imagine we have variables that depend on each other:
# roles/api/defaults:
# Переменная запроса
api_auth1_address: "http://example.com:80"
api_auth2_address: "http://example2.com:80"

# roles/auth/defaults:
# Переменная слушатель
auth_bind_port: "20000"
We'll extract all listeners into global variables group_vars/all/vars and add the group's name to the title:
# group_vars/all/vars
bbauth_auth_bind_port: "20000"
ghauth_auth_bind_port: "30000"

# group_vars/bbauth/vars
auth_bind_port: "{{ bbauth_auth_bind_port }}"

# group_vars/ghauth/vars
auth_bind_port: "{{ ghauth_auth_bind_port }}"

# group_vars/myapi/vars
api_auth1_address: "http://{{ bbauth_auth_service_name }}:{{ bbauth_auth_bind_port }}"
api_auth2_address: "http://{{ ghauth_auth_service_name }}:{{ ghauth_auth_bind_port }}"
Now, by changing the connector value, we can be sure that the request will point to the same location where the port is located.
Code Style
- Since roles and groups are different system objects, they need to have different names, so the linking variables will clearly indicate that they belong to a specific server group, rather than a role in the system.
Environment-dependent files
Roles may use files that differ from environment to environment.
An example of such files can be SSL certificates. Storing them in plain text
in a variable is not very convenient. However, it's convenient to store the path to them within a variable.
For example, we use the variable api_ssl_key_file: "/path/to/file".
Since it is obvious that the certificate key will change from environment to environment, this is an environment-dependent variable, and thus it should be located in the file
group_vars/myapi/vars inventory variables, and contain the value 'for example'.
It is best in this case to put the key file in the playbook repository at the path
files/prod/certs/myapi.key, then the variable value will be:
api_ssl_key_file: "prod/certs/myapi.key". The convenience lies in the fact that the people responsible for deploying the system on a specific environment also have their own dedicated space in the repository for storing their files. At the same time, there remains the option to specify the absolute path to the certificate on the server, in case the certificates are supplied by another system.
Several environments in one setup
There is often a need to deploy several almost identical environments with minimal differences. In this case, we divide the environment-dependent variables into those that remain constant within this environment and those that change. We then move the latter directly into the inventory files. After this manipulation, it becomes possible to create another inventory directly in the environment directory.
It will reuse inventory group_vars and also have the option to override some variables directly for itself.
The final directory structure for the deployment project:
mydeploy                        # Deployment directory
├── deploy.yml                  # Deployment playbook
├── files                       # Directory for deployment files
│   ├── prod                    # Directory for environment-dependent files of the prod stand
│   │   └── certs               #
│   │       └── myapi.key       #
│   └── test1                   # Directory for environment-dependent files of the test1 stand
├── group_vars                  # Playbook variables directory
│   ├── all.yml                 # File for global system variables
│   ├── myapi.yml               # File for group-specific variables of myapi
│   ├── bbauth.yml              #
│   └── ghauth.yml              #
└── inventories                 #
    ├── prod                    # Prod environment directory
    │   ├── group_vars          # Directory for inventory variables
    │   │   ├── myapi           #
    │   │   │   ├── vars.yml    # Environment-dependent variables of the myapi group
    │   │   │   └── vault.yml   # Secrets (always environment-dependent)
    │   │   ├── bbauth          #
    │   │   │   ├── vars.yml    #
    │   │   │   └── vault.yml   #
    │   │   └── ghauth          #
    │   │       ├── vars.yml    #
    │   │       └── vault.yml   #
    │   └── prod.ini            # Inventory of the prod stand
    └── test                    # Test environment directory
        ├── group_vars          #
        │   ├── myapi           #
        │   │   ├── vars.yml    #
        │   │   └── vault.yml   #
        │   ├── bbauth          #
        │   │   ├── vars.yml    #
        │   │   └── vault.yml   #
        │   └── ghauth          #
        │       ├── vars.yml    #
        │       └── vault.yml   #
        ├── test1.ini           # Inventory of the test1 stand in the test environment
        └── test2.ini           # Inventory of the test2 stand in the test environment
Summary
After organizing the variables according to the article: each file with variables is responsible for a specific task. Since the file has certain tasks, it became possible to assign someone accountable for the correctness of each file. For instance, the developer in charge of the system deployment is responsible for the accuracy of the playbook variables, while the administrator responsible for filling in the inventory variables is directly related to the stand described in the inventory.
Roles have become an independent unit of development with their own interface, allowing role developers to create functionalities instead of adjusting the role to the system. This issue was especially relevant for common roles applicable to all systems within the company.
System administrators no longer need to understand the deployment code. All they need for a successful deployment is to fill in the environment-dependent variable files.
Literature
Author
Kalyuzhny Denis Alexandrovich
Source: habr.com
