

At Badoo, we continually monitor emerging technologies and assess whether to integrate them into our system. One such study we wish to share with the community is centered around Loki — a log aggregation system.
Loki is a solution for storing and viewing logs, and this stack provides a flexible system for analyzing logs and sending data to Prometheus. An update was released in May, which the creators are actively promoting. We were curious to see what Loki can do, what capabilities it offers, and to what extent it can serve as an alternative to ELK — the stack we currently use.
What is Loki
Grafana Loki is a set of components for a comprehensive log management system. Unlike other similar systems, Loki is based on the idea of indexing only log metadata — labels (just like in Prometheus), while compressing the actual logs into separate chunks.
,
Before diving into what you can do with Loki, I want to clarify what is meant by 'the idea of indexing only metadata.' Let's compare Loki's approach to indexing with traditional solutions like Elasticsearch, using an example log line from nginx:
172.19.0.4 - - [01/Jun/2020:12:05:03 +0000] "GET /purchase?user_id=75146478&item_id=34234 HTTP/1.1" 500 8102 "-" "Stub_Bot/3.0" "0.001"Traditional systems parse the entire log line, including fields with many unique values like user_id and item_id, and store everything in large indexes. The advantage of this approach is that complex queries can be executed quickly since almost all data is indexed. However, this comes at the cost of the index becoming large, leading to memory requirements. As a result, the full-text log index is comparable in size to the logs themselves. To search quickly, the index must be loaded into memory. The more logs there are, the faster the index grows and the more memory it consumes.
Loki's approach requires extracting only the necessary data from the stream, the number of values of which is small. This way, we obtain a small index and can search for data by filtering it based on time and indexed fields, and then scanning the remaining data using regular expressions or substring searches. The process seems not the fastest, but Loki splits the query into multiple parts and executes them in parallel, handling large amounts of data in a short time. The number of shards and parallel queries within them can be configured; thus, the amount of data that can be processed per unit of time is linearly dependent on the amount of resources provided.
This compromise between a large fast index and a small index with parallel full scanning allows Loki to control the system's cost. It can be flexibly adjusted and scaled according to needs.
The Loki stack consists of three components: Promtail, Loki, and Grafana. Promtail collects logs, processes them, and sends them to Loki. Loki stores them. Grafana can query data from Loki and display it. Overall, Loki can be used not only for storing logs and searching them. The entire stack provides great capabilities for processing and analyzing incoming data using the Prometheus way.
Installation process description can be found .
Log search
Logs can be searched in a special Grafana interface — Explorer. The queries use the LogQL language, which is very similar to PromQL used in Prometheus. Essentially, it can be seen as a distributed grep.
The search interface looks like this:
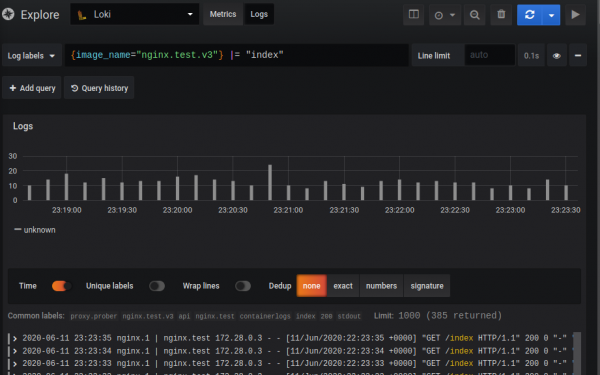
The query itself consists of two parts: selector and filter. The selector is a search of indexed metadata (labels) assigned to the logs, while the filter is the search string or regex used to filter records defined by the selector. In the provided example: The selector is in curly braces, and everything after is the filter.
{image_name="nginx.promtail.test"} |= "index"Due to Loki's operational principles, queries cannot be made without a selector, but labels can be made as general as desired.
A selector is a key-value pair in curly braces. Selectors can be combined, and different search conditions can be set using operators =, !=, or regular expressions:
{instance=~"kafka-[23]",name!="kafka-dev"}
// This will find logs with the label instance, having the value kafka-2, kafka-3, and exclude dev
A filter is a text or regex that filters all data obtained by the selector.
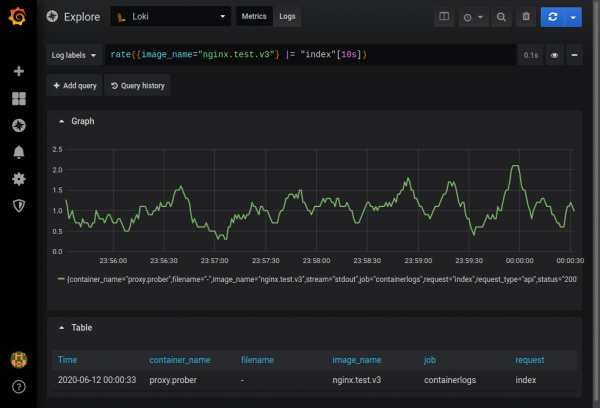
There is an option to get ad-hoc graphs for the obtained data in metrics mode. For example, you can find out the frequency of entries in the nginx logs that contain the string index:
A complete description of capabilities can be found in the documentation .
Log Parsing
There are several ways to collect logs:
- Using Promtail, the standard component of the stack for collecting logs.
- Directly from the Docker container using
- Using Fluentd or Fluent Bit, which can send data to Loki. Unlike Promtail, they have ready-made parsers for almost any type of log and handle multiline logs as well.
Usually, Promtail is used for parsing. It does three things:
- Finds data sources.
- Attaches labels to them.
- Sends data to Loki.
Currently, Promtail can read logs from local files and from systemd journal. It must be installed on every machine from which logs are collected.
There is integration with Kubernetes: Promtail automatically learns the state of the cluster through the Kubernetes REST API and collects logs from a node, service, or pod, immediately attaching labels based on metadata from Kubernetes (pod name, file name, etc.).
Labels can also be attached based on log data using a Pipeline. The Promtail Pipeline can consist of four types of stages. More details can be found in , here I will note some nuances.
- Parsing stages. This is the stage for RegEx and JSON. At this stage, we extract data from logs into what is called an extracted map. We can extract from JSON by simply copying the necessary fields into the extracted map, or through regular expressions (RegEx), where named groups are mapped in the extracted map. The extracted map represents a key-value storage, where key is the field name and value is its value from the logs.
- Transform stages. This stage has two options: transform, where we set transformation rules, and source — the data source for transformation from the extracted map. If there is no such field in the extracted map, it will be created. Thus, it is possible to create labels that are not based on the extracted map. At this stage, we can manipulate data in the extracted map using a sufficiently powerful Moreover, it is important to remember that the extracted map is fully loaded during parsing, which allows, for example, to check the value in it: “{{if .tag}tag value exists{end}}”. The template supports conditions, loops, and some string functions such as Replace and Trim.
- Action stagesAt this stage, you can do something with the extracted data:
- Create a label from extracted data, which will be indexed by Loki.
- Change or set the event time from the log.
- Modify the data (log text) that will go to Loki.
- Create metrics.
- Filtering stagesThe match stage, where you can either send unwanted records to /dev/null or direct them for further processing.
I will demonstrate how to parse standard nginx logs using Promtail.
For testing, we will use a modified nginx jwilder/nginx-proxy:alpine image as nginx-proxy and a small daemon that can query itself over HTTP. The daemon has several endpoints that can provide responses of various sizes, with different HTTP statuses and delays.
We will collect logs from Docker containers located at /var/lib/docker/containers//-json.log
In docker-compose.yml, we configure Promtail and specify the path to the config:
promtail:
  image: grafana/promtail:1.4.1
 // ...
 volumes:
   - /var/lib/docker/containers:/var/lib/docker/containers:ro
   - promtail-data:/var/lib/promtail/positions
   - ${PWD}/promtail/docker.yml:/etc/promtail/promtail.yml
 command:
   - '-config.file=/etc/promtail/promtail.yml'
 // ...
Add the path to the logs in promtail.yml (the config has an option "docker" that does the same thing in one line, but this would be more illustrative):
scrape_configs:
 - job_name: containers

   static_configs:
       labels:
         job: containerlogs
         __path__: /var/lib/docker/containers/*/*log  # for linux only
With such a configuration enabled, logs from all containers will be sent to Loki. To avoid this, we change the logging settings for the test nginx in docker-compose.yml — we add the log tag field:
proxy:
 image: nginx.test.v3
//…
 logging:
   driver: "json-file"
   options:
     tag: "{{.ImageName}}|{{.Name}}"
We edit promtail.yml and configure the Pipeline. The input will be logs in the following format:
{"log":"u001b[0;33;1mnginx.1    | u001b[0mnginx.test 172.28.0.3 - - [13/Jun/2020:23:25:50 +0000] \"GET /api/index HTTP/1.1\" 200 0 \"-\" \"Stub_Bot/0.1\" \"0.096\"n","stream":"stdout","attrs":{"tag":"nginx.promtail.test|proxy.prober"},"time":"2020-06-13T23:25:50.66740443Z"}
{"log":"u001b[0;33;1mnginx.1    | u001b[0mnginx.test 172.28.0.3 - - [13/Jun/2020:23:25:50 +0000] \"GET /200 HTTP/1.1\" 200 0 \"-\" \"Stub_Bot/0.1\" \"0.000\"n","stream":"stdout","attrs":{"tag":"nginx.promtail.test|proxy.prober"},"time":"2020-06-13T23:25:50.702925272Z"}
Pipeline stage:
 - json:
     expressions:
       stream: stream
       attrs: attrs
       tag: attrs.tag
We extract the fields stream, attrs, attrs.tag (if they exist) from the incoming JSON and put them into the extracted map.
 - regex:
     expression: ^(?P([^|]+))|(?P([^|]+))$
     source: "tag"
If we successfully put the field tag into the extracted map, we extract the image and container names using regex.
 - labels:
     image_name:
     container_name:
We assign labels. If the extracted data contains the keys image_name and container_name, their values will be assigned to the corresponding labels.
 - match:
     selector: '{job="docker",container_name="",image_name=""}'
     action: drop
We drop all logs that do not have the established labels image_name and container_name.
  - match:
     selector: '{image_name="nginx.promtail.test"}'
     stages:
       - json:
           expressions:
             row: log
For all logs where image_name is equal to nginx.promtail.test, we extract the field log from the original log and put it in the extracted map with the key row.
  - regex:
         # suppress forego colors
         expression: .+nginx.+|.+[0m(?P[a-z_.-]+) +(?P.+)
         source: logrow
We clean the input string with regular expressions and extract the nginx virtual host and the nginx log line.
     - regex:
         source: nginxlog
         expression: ^(?P[w.]+) - (?P[^ ]*) [(?P[^ ]+).*] "(?P[^ ]*) (?P[^ ]*) (?P[^ ]*)" (?P[d]+) (?P[d]+) "(?P[^"]*)" "(?P[^"]*)"( "(?P[d.]+)")?
We parse the nginx log using regular expressions.
    - regex:
           source: request_url
           expression: ^.+.(?Pjpg|jpeg|gif|png|ico|css|zip|tgz|gz|rar|bz2|pdf|txt|tar|wav|bmp|rtf|js|flv|swf|html|htm)$
     - regex:
           source: request_url
           expression: ^/photo/(?P[^/?]+).*$
       - regex:
           source: request_url
           expression: ^/api/(?P[^/?]+).*$
We analyze request_url. Using regex, we determine the purpose of the request: static, photo, API, and set the corresponding key in the extracted map.
       - template:
           source: request_type
           template: "{{if .photo}}photo{{else if .static_type}}static{{else if .api_request}}api{{else}}other{{end}}"
Using conditional operators in the Template, we check the established fields in the extracted map and set the values needed for the request_type field: photo, static, API. We assign other if none succeeded. Now request_type contains the type of request.
       - labels:
           api_request:
           virtual_host:
           request_type:
           status:
We set the labels api_request, virtual_host, request_type, and status (HTTP status) based on what we were able to put in the extracted map.
       - output:
           source: nginx_log_row
We change the output. Now the cleaned nginx log from the extracted map is sent to Loki.
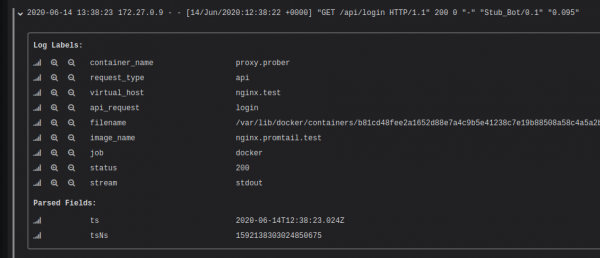
After starting the provided config, you can see that each entry has been assigned labels based on the data from the log.
It's important to note that extracting labels with high cardinality can significantly slow down Loki's performance. This means that, for instance, user_id should not be placed in the index. Read more about this in the article "". However, this doesn't mean that you cannot search by user_id without indexes. You need to use filters when searching ("grepping" through data), and the index here acts as a stream identifier.
Log Visualization
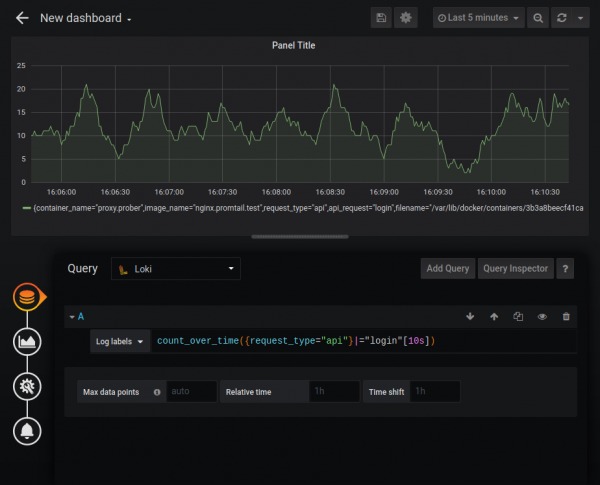
Loki can serve as a data source for Grafana charts using LogQL. The following functions are supported:
- rate — number of records per second;
- count over time — number of records in a specified range.
Additionally, there are aggregating functions like Sum, Avg, and others. It is possible to build quite complex graphs, for example, a graph of HTTP error counts:
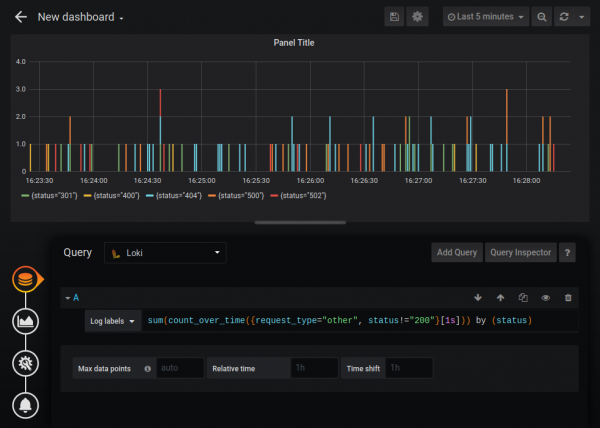
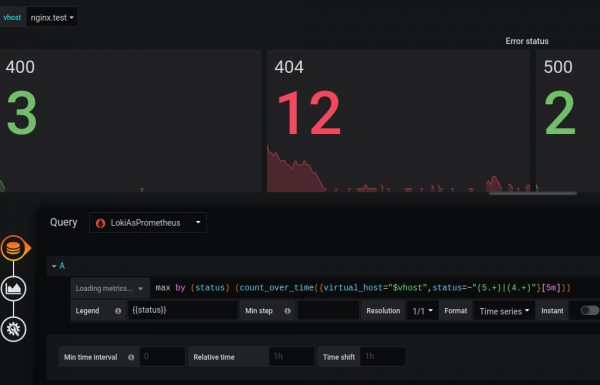
The standard Loki data source is somewhat limited in functionality compared to the Prometheus data source (for instance, you cannot change the legend), but Loki can be connected as a Prometheus type source. I'm not sure if this is documented behavior, but according to the developers' response "", for example, this is quite legitimate, and Loki is fully compatible with PromQL.
We add Loki as a Prometheus type data source and append the URL /loki:

And you can create graphs as if you were working with metrics from Prometheus:
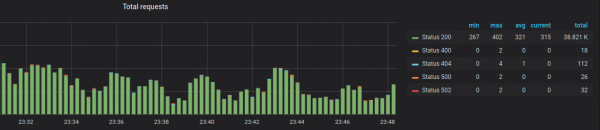
I believe the discrepancy in functionality is temporary and the developers will address this in the future.
Metrics
Loki provides the ability to extract numerical metrics from logs and send them to Prometheus. For example, the nginx log contains the number of bytes in the response, as well as, with a certain modification to the standard log format, the time in seconds taken for the response. This data can be extracted and sent to Prometheus.
We add another section in promtail.yml:
- match:
   selector: '{request_type="api"}'
   stages:
     - metrics:
         http_nginx_response_time:
           type: Histogram
           description: "response time ms"
           source: response_time
           config:
             buckets: [0.010,0.050,0.100,0.200,0.500,1.0]
- match:
   selector: '{request_type=~"static|photo"}'
   stages:
     - metrics:
         http_nginx_response_bytes_sum:
           type: Counter
           description: "response bytes sum"
           source: bytes_out
           config:
             action: add
         http_nginx_response_bytes_count:
           type: Counter
           description: "response bytes count"
           source: bytes_out
           config:
             action: inc
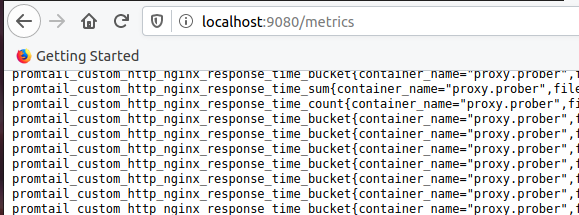
This option allows you to define and update metrics based on data from the extracted map. These metrics are not sent to Loki; they appear in the Promtail /metrics endpoint. Prometheus must be configured to receive the data obtained at this stage. In the example provided for request_type="api", we are collecting a histogram metric. This type of metric is useful for obtaining percentiles. For static and photo data, we collect the sum of bytes and the number of lines in which we received bytes to calculate the average.
Read more about metrics .
Opening a port on Promtail:
promtail:
     image: grafana/promtail:1.4.1
     container_name: monitoring.promtail
     expose:
       - 9080
     ports:
       - "9080:9080"
Ensure that the metrics prefixed with promtail_custom have appeared:
Configuring Prometheus. Adding the promtail job:
- job_name: 'promtail'
 scrape_interval: 10s
 static_configs:
   - targets: ['promtail:9080']
And drawing a graph:
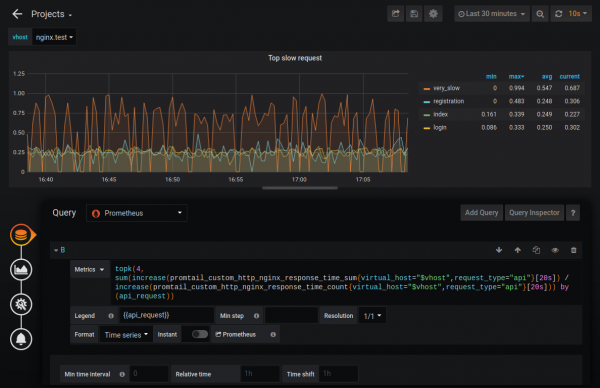
This way you can find out, for example, the four slowest requests. You can also set up monitoring on this metric data.
Scaling
Loki can operate in single binary mode or in horizontally scalable mode. In the latter case, it can store data in the cloud, with chunks and indexes stored separately. In version 1.5, the ability to store in one place was implemented, but it's not yet recommended for production use.
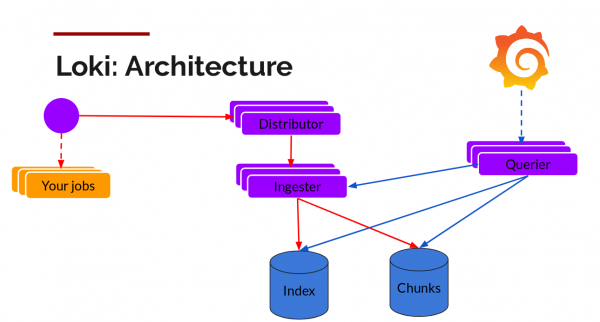
Chunks can be stored in S3-compatible storage, while indexes can use horizontally scalable databases: Cassandra, BigTable, or DynamoDB. Other parts of Loki, such as Distributors (for writing) and Querier (for queries), are stateless and also scale horizontally.
At the DevOpsDays Vancouver 2019 conference, one participant, Callum Styan, stated that with Loki, his project has petabytes of logs with an index size of less than 1% of the total size: “”.
Comparison of Loki and ELK
Index Size
For testing the resulting index size, I took logs from the nginx container for which the pipeline mentioned above was configured. The log file contained 406,624 lines with a total size of 109 MB. Logs were generated for an hour, with approximately 100 entries per second.
An example of two lines from the log:
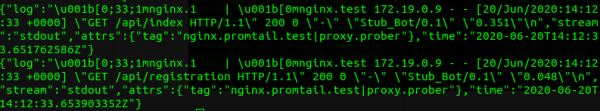
When indexed in ELK, this resulted in an index size of 30.3 MB:
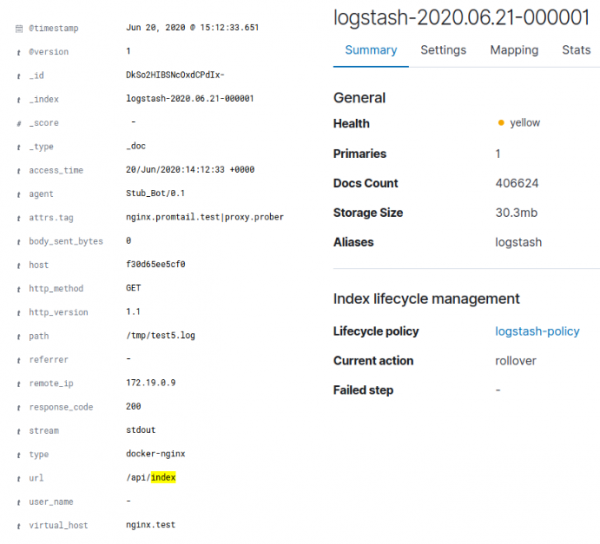
In the case of Loki, it resulted in approximately 128 KB of index and about 3.8 MB of data in chunks. It's worth noting that the log was artificially generated and did not exhibit much data variety. A simple gzip on the original Docker JSON log with data achieved a compression of 95.4%, and considering that only the cleaned nginx log was sent to Loki, compressing to 4 MB is understandable. The total number of unique values for Loki labels was 35, which explains the small size of the index. For ELK, the log was also cleaned. Thus, Loki compressed the original data by 96%, while ELK achieved a 70% compression.
Memory Consumption
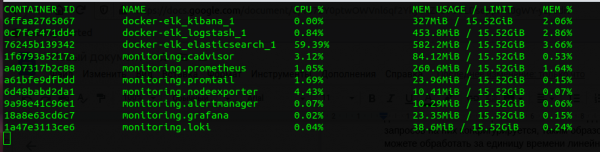
When comparing the entire Prometheus and ELK stack, Loki 'consumes' several times less. It's clear that a service running on Go uses less memory than one running on Java, and comparing the JVM Heap size of Elasticsearch with the allocated memory for Loki is not quite fair, yet it should be noted that Loki consumes significantly less memory. Its CPU advantage is not as obvious, but still present.
Speed
Loki consumes logs more quickly. The speed depends on many factors — the type of logs, how intricately we parse them, the network, the disk, etc. — but it is definitely higher than ELK (in my test, about twice as fast). This is explained by the fact that Loki writes significantly fewer data into the index and, consequently, spends less time on indexing. However, when it comes to search speed, the situation is the opposite: Loki noticeably slows down on data larger than a few gigabytes, while ELK's search speed is independent of the data size.
Log search
Loki significantly falls short of ELK in log search capabilities. Grep with regular expressions is a powerful tool, but it can't compete with a mature database. The absence of range queries, aggregation limited to labels, and the inability to search without labels — all these factors restrict our ability to find the desired information in Loki. This does not imply that nothing can be found using Loki, but it shapes the workflow with logs, where you first identify a problem using Prometheus graphs, and then search for what happened in the logs based on those labels.
The PerformanceResourceTiming
First of all, it looks good (sorry, I couldn't help it). Grafana has a visually appealing interface, but Kibana is far more functional.
Pros and Cons of Loki
Among the advantages, it is worth noting that Loki integrates with Prometheus, allowing us to get metrics and alerting out of the box. It is convenient for collecting and storing logs from Kubernetes Pods, as it inherits service discovery from Prometheus and automatically attaches labels.
The downsides include weak documentation. Some aspects, such as the features and capabilities of Promtail, I found only while studying the code, fortunately, it's open-source. Another drawback is limited parsing capabilities. For example, Loki cannot parse multiline logs. Additionally, it can be noted that Loki is a relatively young technology (version 1.0 was released in November 2019).
Conclusion
Loki is a 100% interesting technology suitable for small and medium projects, allowing to solve many tasks related to log aggregation, log searching, monitoring, and log analysis.
We do not use Loki at Badoo since we have an ELK stack that meets our needs and has been built up with various custom solutions over the years. The stumbling block for us is log searching. With nearly 100 GB of logs per day, it's crucial for us to be able to find everything and even more, and do it quickly. For charting and monitoring, we use other solutions tailored to our needs and integrated with each other. The Loki stack has noticeable advantages, but it won’t offer us more than we already have, and its benefits certainly won’t outweigh the migration costs.
And although after our research it became clear that we cannot use Loki, we hope this post helps you in your selection.
The repository with the code used in the article is located at .
Source: habr.com
