

For the last six months or so, I have been working on creating a fraud detection system without any initial infrastructure. The ideas we discovered and implemented in our system today help us detect various fraudulent actions and analyze them. In this article, I would like to discuss the principles we followed and what we did to reach the current state of our system without delving into the technical details.
Principles of Our System
When you hear terms like “automatic” and “fraud,” you likely start thinking about machine learning, Apache Spark, Hadoop, Python, Airflow, and other technologies from the Apache Foundation ecosystem and the Data Science field. I believe there is one aspect of using these tools that is often not mentioned: they require certain prerequisites in your corporate system before you can start using them. In short, you need a data platform that includes a data lake and a storage system. But what if you don’t have such a platform and still need to develop this practice? The principles I discuss below helped us reach a point where we can focus on improving our ideas rather than searching for what works. However, this is not a “plateau” for the project. There are still many things left to address from both technological and product perspectives.
Principle 1: Business Value Comes First
At the forefront of all our efforts, we prioritized “business value.” Generally, any automatic analysis system falls into the category of complex systems with a high level of automation and technical complexity. Creating a complete solution will take a significant amount of time if you build it from scratch. We decided to prioritize business value first and technological completeness second. In real life, this means we do not treat advanced technologies as dogma. We choose technology that works best for us at the moment. Over time, it may seem that we need to re-implement some modules. This is a compromise we accepted.
Principle 2: Augmented Intelligence
I bet that most people who are not deeply involved in developing machine learning solutions might think that replacing humans is the goal. In reality, machine learning solutions are far from perfect, and replacement is only possible in certain areas. We dismissed this idea from the outset for several reasons: unbalanced data on fraudulent activities and the inability to provide a comprehensive list of features for machine learning models. Instead, we opted for an augmented intelligence approach. This is an alternative concept of artificial intelligence that focuses on the supportive role of AI, emphasizing that cognitive technologies are meant to enhance human intelligence rather than replace it. [1]
Given this, developing a complete machine learning solution from the start would require immense efforts that would delay the creation of value for our business. We decided to build a system with an iteratively growing aspect of machine learning guided by our domain experts. The tricky part of developing such a system is that it needs to provide our analysts with cases not only in terms of whether it’s fraudulent activity or not. In general, any anomaly in customer behavior is a suspicious case that specialists need to investigate and respond to in some way. Only a portion of these recorded cases can genuinely be categorized as fraud.
Principle 3: the platform of extensive analytics
The most challenging aspect of our system is the seamless workflow verification process. Analysts and developers should easily access historical data sets with all the metrics used for analysis. Moreover, the data platform must provide a simple way to supplement the existing set of indicators with new ones. The processes we create, which are not only software processes, should allow for easy recalculation of previous periods, addition of new metrics, and modification of data forecasts. We could achieve this by accumulating all the data generated by our production system. In such a case, the data would gradually become a nuisance. We would need to store a growing volume of data that we do not use and protect it. In such a scenario, over time, the data would become increasingly irrelevant, yet still require our efforts to manage it. For us, data hoarding did not make sense, and we decided to take a different approach. We opted to organize real-time data warehouses around the target entities we want to classify and store only the data that allows for verification of the most recent and relevant periods. The complexity of these efforts lies in the fact that our system is heterogeneous with several data warehouses and software modules that require careful planning for consistent operation.
Constructive concepts of our system
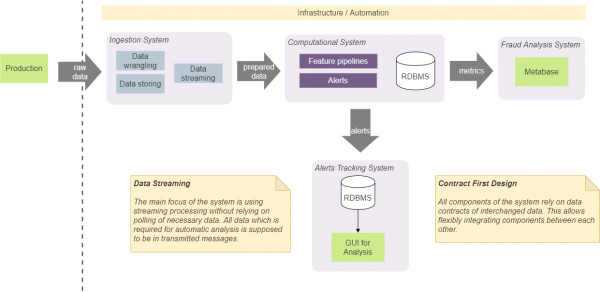
We have four main components in our system: ingestion system, computational, BI analysis, and tracking system. They serve specific isolated purposes, and we keep them isolated by following certain development approaches.
Contract-based design
First of all, we agreed that components should rely only on specific data structures (contracts) that are passed between them. This allows for easy integration between them without imposing a specific composition (and order) of components. For example, in some cases, this enables us to directly integrate the receipt system with the alert tracking system. In this case, it will be done according to the agreed alert contract. This means that both components will be integrated using a contract that can be utilized by any other component. We will not add an additional contract for adding alerts from the input system into the tracking system. This approach requires the use of a predetermined minimal number of contracts and simplifies the system and communications. Essentially, we are using an approach called 'Contract First Design' and applying it to streaming data contracts. [2]
Streaming Everywhere
Saving and managing state in a system will inevitably lead to complications in its implementation. Generally, the state should be accessible from any component, consistent, and provide the most current value for all components, and it must be reliable with the correct values. Moreover, making calls to persistent storage to fetch the latest state increases the number of input-output operations and adds complexity to the algorithms used in our real-time pipelines. Because of this, we have decided to eliminate state storage from our system entirely where possible. This approach requires bundling all necessary data into the transmitted data block (message). For example, if we need to compute the total number of certain observations (the number of operations or cases with specific characteristics), we compute it in memory and generate a stream of such values. Dependent modules will use partitioning and batching to break the stream into entities and operate on the latest values. This approach has removed the necessity of having persistent disk storage for such data. Our system uses Kafka as a message broker, and it can be utilized as a database with KSQL. [3] However, using it would tightly couple our solution to Kafka, so we chose not to use it. Our chosen approach allows us to replace Kafka with another message broker without significant internal changes to the system.
This concept does not imply that we do not use disk storage and databases. To validate and analyze the system's performance, we need to store a significant amount of data on disk that represents various metrics and states. An important point here is that real-time algorithms do not depend on such data. In most cases, we use the saved data for offline analysis, debugging, and tracking specific cases and results produced by the system.
Issues with our system
There are certain issues we have addressed to a certain extent, but they require more thoughtful solutions. Right now, I would just like to mention them here, as each point deserves a separate article.
- We still need to define the processes and policies that foster the accumulation of meaningful and relevant data for our automated analysis, detection, and data exploration.
- Incorporating human analysis results into the automated system tuning process for updating it with the latest data. This not only updates our model but also refreshes processes and enhances our understanding of the data.
- Finding a balance between a deterministic IF-ELSE approach and ML. Someone said, "ML is a tool for the desperate." This means you'll want to use ML when you no longer understand how to optimize and improve your algorithms. On the other hand, the deterministic approach does not allow for the detection of anomalies that were not anticipated.
- We need a simple way to test our hypotheses or correlations between metrics in the data.
- The system should have multiple levels of true positive results. Fraud cases are just part of all cases that can be deemed positive for the system. For instance, analysts want to receive all suspicious cases for verification, and only a small portion of them are fraud. The system must effectively provide analysts with all cases, regardless of whether it is actual fraud or just suspicious behavior.
- The data platform should allow for the retrieval of datasets from past periods with calculations that have been created and computed on the fly.
- Simple and automated deployment of any of the system components in at least three different environments: production, experimental (beta), and for developers.
- Last but not least, we need to create an extensive performance testing platform where we can analyze our models. [4]
Links
Source: habr.com
