

In this study, I wanted to see what performance improvements can be achieved by using ClickHouse as a data source instead of PostgreSQL. I know the performance advantages I gain from using ClickHouse. Will these advantages be preserved if I access ClickHouse from PostgreSQL via a foreign data wrapper (FDW)?
The database environments being examined are PostgreSQL v11, clickhousedb_fdw, and the ClickHouse database. Ultimately, we will run various SQL queries from PostgreSQL v11 routed through our clickhousedb_fdw to the ClickHouse database. We will then see how the performance of FDW compares to the same queries executed in native PostgreSQL and native ClickHouse.
Clickhouse database
ClickHouse is an open-source, columnar database management system that can achieve performance 100-1000 times faster than traditional database approaches, capable of processing over a billion rows in less than a second.
Clickhousedb_fdw
clickhousedb_fdw, the foreign data wrapper for ClickHouse, is an open-source project by Percona. .
.
As you will see, it provides an FDW for ClickHouse that allows SELECT from and INSERT INTO the ClickHouse database from a PostgreSQL v11 server.
The FDW supports advanced features such as aggregate and join. This significantly improves performance by utilizing the resources of the remote server for these resource-intensive operations.
Benchmark environment
- Supermicro server:
- Intel® Xeon® CPU E5-2683 v3 @ 2.00GHz
- 2 sockets / 28 cores / 56 threads
- Memory: 256GB of RAM
- Storage: Samsung SM863 1.9TB Enterprise SSD
- Filesystem: ext4/xfs
- OS: Linux smblade01 4.15.0-42-generic #45~16.04.1-Ubuntu
- PostgreSQL: version 11
Benchmark tests
Instead of using some machine-generated dataset for this test, we used data from "Performance over time, reporting operator run time" from 1987 to 2018. You can access the data .
The database size is 85 GB, providing one table with 109 columns.
Benchmark Queries
Here are the queries I used to compare ClickHouse, clickhousedb_fdw, and PostgreSQL.
Q#
Query Contains Aggregates and Group By
Q1
SELECT DayOfWeek, count(*) AS c FROM ontime WHERE Year >= 2000 AND Year <= 2008 GROUP BY DayOfWeek ORDER BY c DESC;
Q2
SELECT DayOfWeek, count(*) AS c FROM ontime WHERE DepDelay>10 AND Year >= 2000 AND Year <= 2008 GROUP BY DayOfWeek ORDER BY c DESC;
Q3
SELECT Origin, count(*) AS c FROM ontime WHERE DepDelay>10 AND Year >= 2000 AND Year <= 2008 GROUP BY Origin ORDER BY c DESC LIMIT 10;
Q4
SELECT Carrier, count() FROM ontime WHERE DepDelay>10 AND Year = 2007 GROUP BY Carrier ORDER BY count() DESC;
Q5
SELECT a.Carrier, c, c2, c1000/c2 as c3 FROM ( SELECT Carrier, count() AS c FROM ontime WHERE DepDelay>10 AND Year=2007 GROUP BY Carrier ) a INNER JOIN ( SELECT Carrier,count(*) AS c2 FROM ontime WHERE Year=2007 GROUP BY Carrier)b on a.Carrier=b.Carrier ORDER BY c3 DESC;
Q6
SELECT a.Carrier, c, c2, c1000/c2 as c3 FROM ( SELECT Carrier, count() AS c FROM ontime WHERE DepDelay>10 AND Year >= 2000 AND Year = 2000 AND Year <= 2008 GROUP BY Carrier ) b on a.Carrier=b.Carrier ORDER BY c3 DESC;
Q7
SELECT Carrier, avg(DepDelay) * 1000 AS c3 FROM ontime WHERE Year >= 2000 AND Year <= 2008 GROUP BY Carrier;
Q8
SELECT Year, avg(DepDelay) FROM ontime GROUP BY Year;
Q9
select Year, count(*) as c1 from ontime group by Year;
Q10
SELECT avg(cnt) FROM (SELECT Year,Month,count(*) AS cnt FROM ontime WHERE DepDel15=1 GROUP BY Year,Month) a;
Q11
select avg(c1) from (select Year,Month,count(*) as c1 from ontime group by Year,Month) a;
Q12
SELECT OriginCityName, DestCityName, count(*) AS c FROM ontime GROUP BY OriginCityName, DestCityName ORDER BY c DESC LIMIT 10;
Q13
SELECT OriginCityName, count(*) AS c FROM ontime GROUP BY OriginCityName ORDER BY c DESC LIMIT 10;
Query Contains Joins
Q14
SELECT a.Year, c1/c2 FROM ( select Year, count()1000 as c1 from ontime WHERE DepDelay>10 GROUP BY Year) a INNER JOIN (select Year, count(*) as c2 from ontime GROUP BY Year ) b on a.Year=b.Year ORDER BY a.Year;
Q15
SELECT a.”Year”, c1/c2 FROM ( select “Year”, count()1000 as c1 FROM fontime WHERE “DepDelay”>10 GROUP BY “Year”) a INNER JOIN (select “Year”, count(*) as c2 FROM fontime GROUP BY “Year” ) b on a.”Year”=b.”Year;
Table-1: Queries used in benchmark
Query executions
Here are the results of each query executed under different database settings: PostgreSQL with and without indexes, custom ClickHouse and clickhousedb_fdw. Time is displayed in milliseconds.
Q#
PostgreSQL
PostgreSQL (Indexed)
ClickHouse
clickhousedb_fdw
Q1
27920
19634
23
57
Q2
35124
17301
50
80
Q3
34046
15618
67
115
Q4
31632
7667
25
37
Q5
47220
8976
27
60
Q6
58233
24368
55
153
Q7
30566
13256
52
91
Q8
38309
60511
112
179
Q9
20674
37979
31
81
Q10
34990
20102
56
148
Q11
30489
51658
37
155
Q12
39357
33742
186
1333
Q13
29912
30709
101
384
Q14
54126
39913
124
1364212
Q15
97258
30211
245
259
Table-1: Time taken to execute the queries used in benchmark
View Results
The graph shows the execution time of the query in milliseconds; the X-axis represents the query number from the tables above, while the Y-axis shows the execution time in milliseconds. Results from ClickHouse and data obtained from PostgreSQL using clickhousedb_fdw are displayed. The table shows that there is a huge difference between PostgreSQL and ClickHouse, but minimal difference between ClickHouse and clickhousedb_fdw.
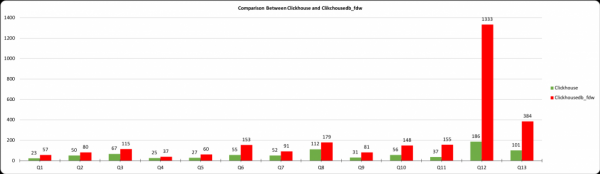
This graph illustrates the difference between ClickHouseDB and clickhousedb_fdw. In most queries, the overhead of FDW is not significant and is hardly noticeable, except for Q12. This query involves joins and an ORDER BY clause. Due to the ORDER BY clause, the GROUP BY and ORDER BY are not skipped in ClickHouse.
In Table 2, we observe a spike in the execution time for queries Q12 and Q13. Again, this is due to the presence of the ORDER BY clause. To confirm this, I executed queries Q-14 and Q-15, both with and without the ORDER BY clause. Without the ORDER BY clause, the completion time is 259 ms, whereas with the ORDER BY clause, it jumps to 1364212 ms. For debugging this query, I have provided explanations for both queries, with the results included here.
Q15: Without ORDER BY Clause
bm=# EXPLAIN VERBOSE SELECT a."Year", c1/c2
     FROM (SELECT "Year", count(*)*1000 AS c1 FROM fontime WHERE "DepDelay" > 10 GROUP BY "Year") a
     INNER JOIN(SELECT "Year", count(*) AS c2 FROM fontime GROUP BY "Year") b ON a."Year"=b."Year";
Q15: Query Without ORDER BY Clause
QUERY PLAN
Hash Join  (cost=2250.00..128516.06 rows=50000000 width=12)
Output: fontime."Year", (((count(*) * 1000)) / b.c2)
Inner Unique: true   Hash Cond: (fontime."Year" = b."Year")
->  Foreign Scan  (cost=1.00..-1.00 rows=100000 width=12)
Output: fontime."Year", ((count(*) * 1000))
Relations: Aggregate on (fontime)
Remote SQL: SELECT "Year", (count(*) * 1000) FROM "default".ontime WHERE (("DepDelay" > 10)) GROUP BY "Year"
->  Hash  (cost=999.00..999.00 rows=100000 width=12)
Output: b.c2, b."Year"
->  Subquery Scan on b  (cost=1.00..999.00 rows=100000 width=12)
Output: b.c2, b."Year"
->  Foreign Scan  (cost=1.00..-1.00 rows=100000 width=12)
Output: fontime_1."Year", (count(*))
Relations: Aggregate on (fontime)
Remote SQL: SELECT "Year", count(*) FROM "default".ontime GROUP BY "Year"(16 rows)
Q14: Query With ORDER BY Clause
bm=# EXPLAIN VERBOSE SELECT a."Year", c1/c2 FROM(SELECT "Year", count(*)*1000 AS c1 FROM fontime WHERE "DepDelay" > 10 GROUP BY "Year") a
     INNER JOIN(SELECT "Year", count(*) as c2 FROM fontime GROUP BY "Year") b  ON a."Year"= b."Year"
     ORDER BY a."Year";
Q14: Query Plan with ORDER BY Clause
QUERY PLAN
Merge Join  (cost=2.00..628498.02 rows=50000000 width=12)
Output: fontime."Year", (((count(*) * 1000)) / (count(*)))
Inner Unique: true   Merge Cond: (fontime."Year" = fontime_1."Year")
->  GroupAggregate  (cost=1.00..499.01 rows=1 width=12)
Output: fontime."Year", (count(*) * 1000)
Group Key: fontime."Year"
->  Foreign Scan on public.fontime  (cost=1.00..-1.00 rows=100000 width=4)
Remote SQL: SELECT "Year" FROM "default".ontime WHERE (("DepDelay" > 10))
            ORDER BY "Year" ASC
->  GroupAggregate  (cost=1.00..499.01 rows=1 width=12)
Output: fontime_1."Year", count(*)         Group Key: fontime_1."Year"
->  Foreign Scan on public.fontime fontime_1  (cost=1.00..-1.00 rows=100000 width=4)

Remote SQL: SELECT "Year" FROM "default".ontime ORDER BY "Year" ASC(16 rows)
Output
The results of these experiments show that ClickHouse offers truly impressive performance, and clickhousedb_fdw provides the performance benefits of ClickHouse from PostgreSQL. While there are some overheads when using clickhousedb_fdw, they are minimal and comparable to the performance achieved when running natively in ClickHouse. This also confirms that FDW in PostgreSQL delivers remarkable results.
Telegram chat about ClickHouse
Telegram chat about PostgreSQL
Source: habr.com
