

I suggest you check out the transcript of Andrey Salnikov's report from early 2016 titled 'Typical errors in applications that lead to bloat in PostgreSQL.'
In this report, I will discuss the main errors in applications that occur during the design and coding stages. I will focus only on those errors that lead to bloat in PostgreSQL. Typically, this marks the beginning of the end for your system's performance as a whole, even though there may not have been any initial signs of it.
Hello everyone! This report is not as technical as my colleague's previous one. It is mainly aimed at backend system developers because we have a considerable number of clients, and they all make the same mistakes. I will talk to you about these errors and explain the fatal and adverse consequences they lead to.
Why do errors occur? They happen for two reasons: either by chance, thinking it might work, or from a lack of understanding of certain mechanisms occurring at the interface between the database and the application, as well as within the database itself.
I will provide you with three examples with alarming visuals illustrating how things have gone wrong. I will briefly explain the mechanisms at play and how to address these issues when they arise, along with preventive methods to avoid errors. I will also discuss auxiliary tools and share useful links.
I used a test database with two tables. One table contains client accounts, and the other has transactions for these accounts. Periodically, we update the balances for these accounts.
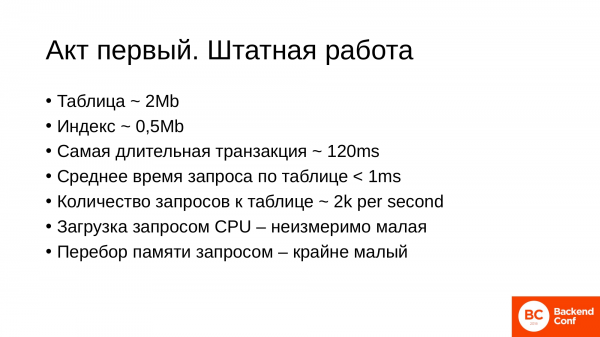
The source data for the table is relatively small, at 2 MB. The response time for the database, particularly for this table, is also very good, with a decent load of 2,000 operations per second on the table.
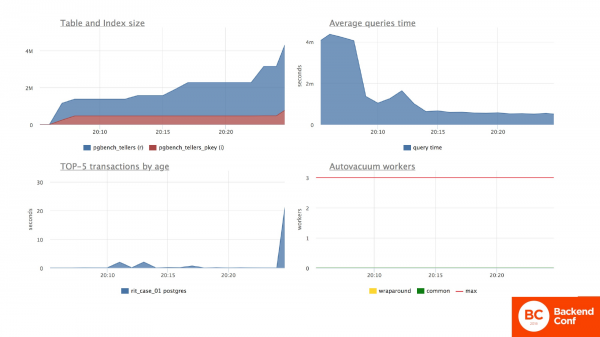
Throughout this report, I will show you graphs to clearly illustrate what is happening. There will always be two slides with graphs. The first slide shows what is happening in general on the server.
In this situation, we see that our table is indeed small. The index is also small at 2 MB. This is the first graph on the left.
The average response time for the server is also stable and low. This is the top right graph.
The bottom left chart represents the longest transactions. We see that transactions are executed quickly. The autovacuum is not yet working here because this was a start test. It will work further and be useful to us.
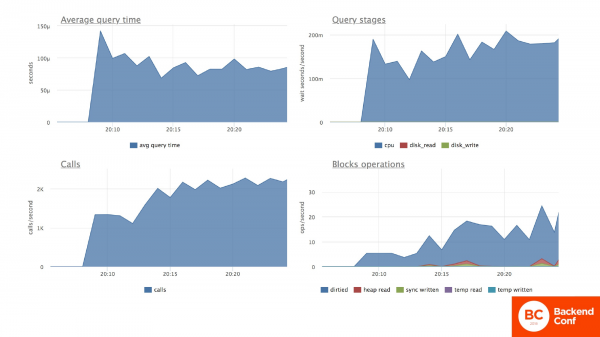
The second slide will always focus on the test table. In this situation, we are constantly updating balances on the client's accounts. We see that the average response time for the update operation is quite good, less than a millisecond. We can see that CPU resources (this is the top right chart) are also consumed evenly and at a relatively low level.
The bottom right chart shows how much memory we are using, both operational and disk, in searching for the necessary line before we update it. The number of operations on the table is 2,000 per second, as I mentioned before.
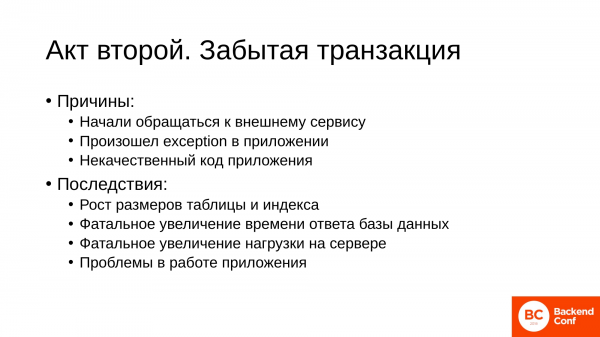
And now we face a tragedy. For some reason, a long forgotten transaction occurs. The reasons are usually quite trivial:
- One of the most common reasons is that we started calling an external service in the application code. And this service does not respond to us. That is, we opened a transaction, made a change in the database, and went to check our email or visit another service within our infrastructure, and for some reason, it does not respond. Our session hangs in a state of being unknown when it will be resolved.
- The second situation occurs when there is an exception in the code for some reason. And we did not handle the closing of the transaction in the exception. We end up with a hanging session with an open transaction.
- Lastly, this is also a fairly common case. This is poor quality code. Some frameworks open a transaction. It hangs, and you may not know in the application that it is hanging.
What do these things lead to?
They lead to our tables and indexes beginning to swell rapidly. This is precisely the bloat effect. For the database, this will express itself in a sharp increase in database response time, an increase in load on the database server. As a result, the application will suffer. Because if you used to spend 10 milliseconds on a query to the database and 10 milliseconds on your logic, your function executed in 20 milliseconds. Now your situation will be quite grim.
Let's take a look at what's happening. The bottom left graph shows that we have a long-running transaction. If we look at the top left graph, we see that the size of the table jumped drastically from two megabytes to 300 megabytes. However, the amount of data in the table hasn't changed, meaning there's a significant amount of garbage.
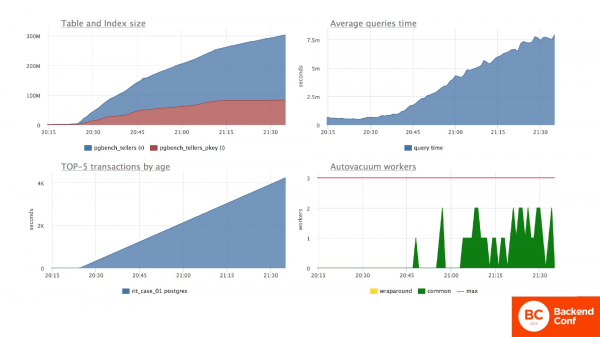
The overall situation with the average server response time has also changed by several orders of magnitude. All requests to the server have started to drop significantly. At the same time, internal Postgres processes like autovacuum are running, trying to do something and consuming resources.
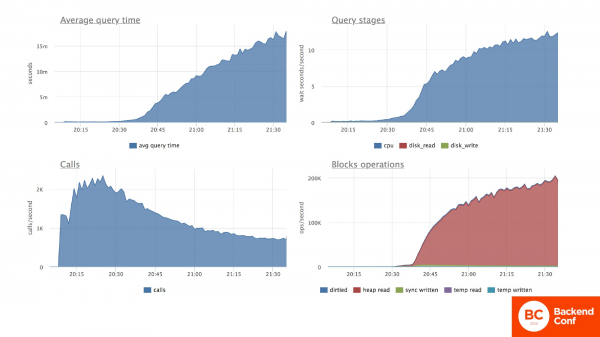
What is happening with our table? The same thing. The average response time for the table has surged by several orders of magnitude. Specifically regarding resource consumption, we see that CPU load has increased significantly. This is shown in the upper right graph. It's increased because the CPU has to sift through a lot of useless rows in search of one needed row. This is shown in the lower right graph. As a result, the number of calls per second has started to fall sharply because the database can't process the same number of requests.
We need to get back to normal. We dive into the internet and find out that long transactions lead to problems. We locate and terminate that transaction. Everything returns to normal. Everything works as it should.
We calmed down, but after a while, we start to notice that the application isn't performing as it did before the incident. Requests are still being processed more slowly, significantly slower in fact. In my case, it’s one and a half to two times slower. The server load is also higher than it was before the incident.
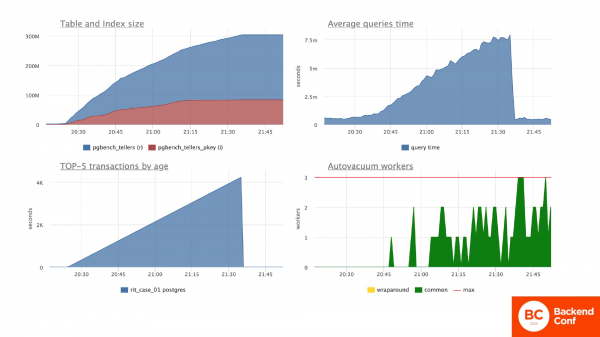
And the question is: "What is happening with the database at this moment?" The following situation is occurring in the database. In the transaction graph, you can see that it has stopped and there are indeed no long-running transactions. However, the size of the table during the incident has drastically increased. Since then, it hasn't decreased. The average response time for the database has stabilized. Responses seem to be flowing adequately at a speed acceptable to us. Autovacuum has become more active and has started to do something with the table because it needs to process a larger amount of data.
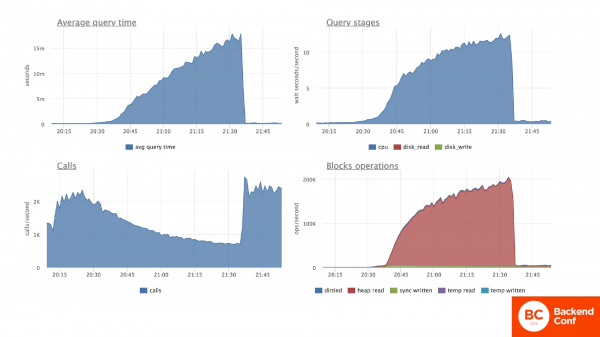
Specifically regarding the tested table with accounts, where we change balances: the response time for the request seems to have returned to normal. But in reality, it is one and a half times higher.
And regarding the CPU load, we see that the load has not returned to the desired level since the failure. The reasons are just hidden in the lower right graph. It is evident that there is an overload of some amount of memory. That is, to find the necessary row, we are spending database server resources on sifting through useless data. The number of transactions per second has stabilized.
Overall, it’s good, but the situation is worse than it was. There is an obvious degradation of the database as a consequence of our application that works with this database.
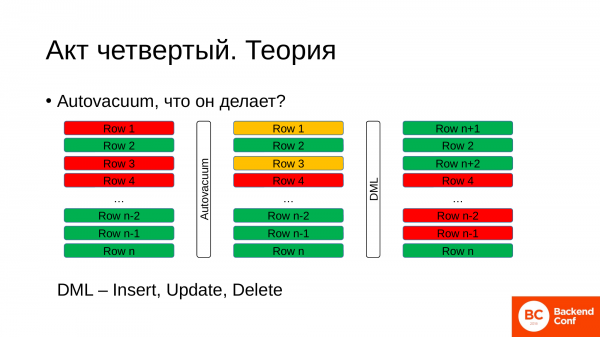
And to understand what is happening, if you were not at the previous report, here’s a bit of theory. Theory about the internal process. What is vacuuming and what does it do?
In brief for understanding. At some point in time, we have a table. In the table, we have rows. These rows can be active, alive, and needed right now. In the image, they are marked in green. And there are dead rows, which have already been processed, updated, and new records have appeared based on them. They are marked as no longer interesting to the database. But they remain in the table due to the nature of Postgres.
What is the purpose of vacuuming? At some point, the vacuum process comes, accesses the database, and asks it: ‘Please give me the id of the oldest transaction that is currently open in the database.’ The database returns this id. And the vacuum process, relying on it, sifts through the rows in the table. If it sees that some rows have been changed by much older transactions, it has the right to mark them as rows that we can reuse in the future by writing new data into them. This is a background process.
During this time, we continue to work with the database, continuing to make changes to the table. And for those rows that we can reuse, we record new data. Thus, we get a cycle, that is, there are always some dead old rows appearing there, and in their place, we write new rows that we need. And this is a normal state for working with PostgreSQL.
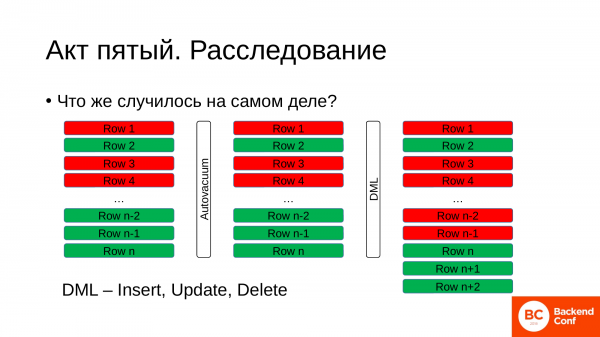
What happened during the crash? How did that process unfold?
We had a table in a certain state, with some live and some dead rows. The autovacuum came. It asked the database about our oldest transaction and its id. It retrieved this id, which could be hours old or just ten minutes old, depending on the load on your database. Then it went looking for rows it could mark as reusable, but it found none in our table.
But during this time, we continue to work with the table. We are updating it, changing data. And what does the database do then? It has no choice but to append new rows to the end of the existing table. This results in our table size starting to swell.
In reality, we need green rows for our work. But during such issues, we find that the percentage of green rows is extremely low in the total volume of the table.
When we execute a query, the database has to go through all the rows: both red and green, to find the needed row. This effect of table bloat due to useless data is called 'bloat,' which also consumes our disk space. Remember, it was 2 MB, and now it's 300 MB? Now, replace megabytes with gigabytes, and you will quickly find yourself running out of disk resources.
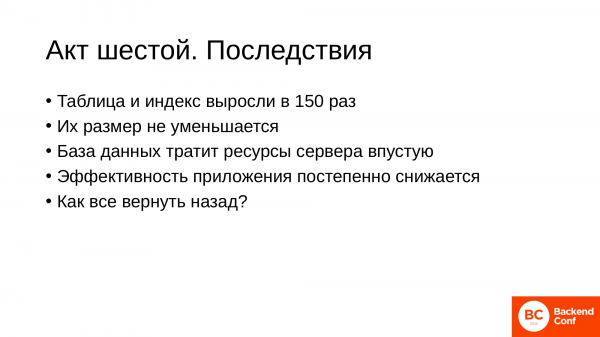
What consequences might there be for us?
- In my example, the table and index grew 150 times. Some of our clients have faced even more severe cases where disk space was simply running out.
- The size of tables themselves never decreases. Autovacuum may remove the tail of the table in some cases if it only contains dead rows. But since there is constant rotation, one green row may end up stuck at the end and not get updated, while all others will be recorded somewhere near the beginning of the table. However, this is such an unlikely event that you shouldn't count on your table size decreasing on its own.
- The database has to sift through all the piles of useless rows. We are wasting disk resources, CPU resources, and electricity.
- And this directly affects our application, because if at the beginning we spent 10 milliseconds on a request and 10 milliseconds on our code, during the crash we ended up spending a second on the request and 10 milliseconds on the code, i.e., the application's performance decreased significantly. When the crash was resolved, our time for the request was reduced to 20 milliseconds and 10 milliseconds for the code. This means that we still saw a one and a half times drop in performance. And it all stemmed from a single transaction that hung, possibly due to our fault.
- And the question is: "How do we get everything back to where it was?" So that everything runs as smoothly as it did before the crash.
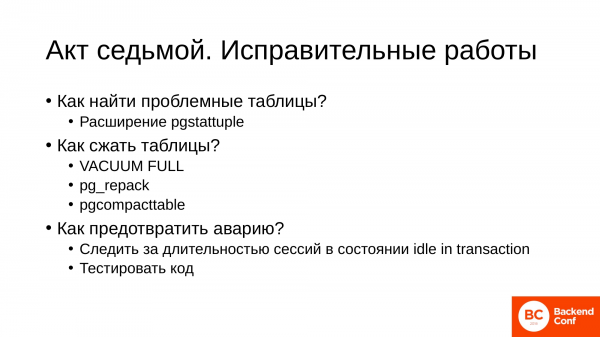
For this, there is a specific work cycle that needs to be conducted.
First, we need to identify the problematic tables that have bloated. We understand that for some tables, the write operations are more active, and for others, less so. This is where the extension comes into play. By installing this extension, you can execute queries that will help you find tables that have bloated significantly.
After you have identified these tables, they need to be compressed. There are already tools available for this. In our company, we use three tools. The first is the built-in VACUUM FULL. It's harsh, brutal, and relentless, but sometimes it is very effective. and – these are third-party utilities for compressing tables. They are more gentle with the database.
They are used based on what is more convenient for you. But I will talk more about that at the end. The important thing is that there are three tools available. You have options.
After we've corrected everything and ensured that everything is back to normal, we need to know how to prevent this situation from happening again:
- It can be prevented quite easily. You need to monitor the duration of sessions on the Master server. Particularly dangerous are sessions in an idle in transaction state.These are the ones that opened a transaction, did something, and then left or simply hung, getting lost in the code.
- As developers, it's crucial for you to test the code in situations where these issues arise. It's not difficult to do. It will be a valuable check. You will avoid a lot of "child" problems related to long transactions.
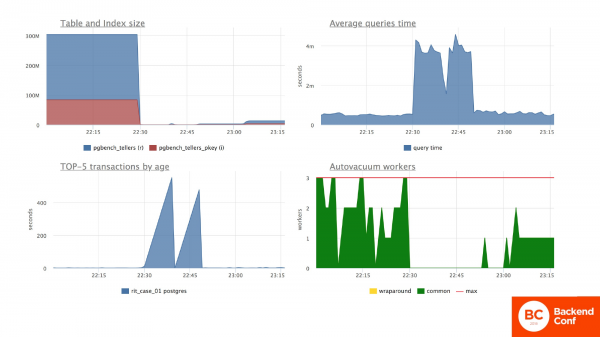
In these graphs, I wanted to show you how the table and the behavior of the database changed after I ran VACUUM FULL on the table in this case. This is not in production for me.
The table size immediately returned to a normal operational state of a couple of megabytes. It did not significantly affect the average response time from the server.
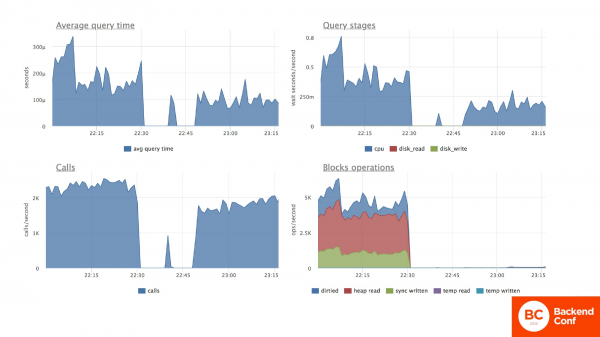
But specifically for our test table, where we updated account balances, we see that the average response time for data update requests in the table has dropped to pre-issue levels. The resources consumed by the processor to execute this query have also declined to pre-issue levels. The lower right graph shows that we are now finding exactly the row we need immediately, without sifting through a bunch of dead rows that existed before the table compression. The average query time has remained about the same, but here, I am more likely looking at an error in my hardware.
That concludes the first story. It is the most common one and occurs to everyone, regardless of the client's experience or the qualifications of the programmers. Sooner or later, this happens.
The second story involves distributing the load and optimizing server resources.
- We have already grown and become serious players. We understand that we have a replica, and it would be good to balance the load: writing to the Master and reading from the replica. This situation usually arises when we want to prepare some reports or perform ETL. The business is very pleased with this. They want diverse reports with plenty of complex analytics.
- The reports take hours because complex analytics cannot be calculated in milliseconds. We, as brave guys, are writing code. We make inserts in the application, directing writes to the Master and executing reports on the replica.
- We are distributing the load.
- Everything works great. We are doing well.
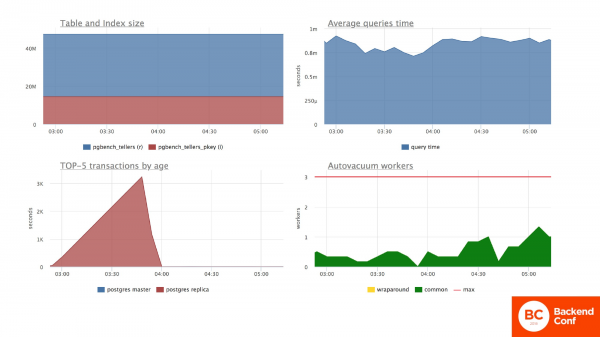
And how does this situation look? Specifically in these graphs, I also added the duration of transactions from the replica for transaction duration. All other graphs relate only to the Master server.
The report table has grown by this point. There are more of them now. We see that the average server response time is stable. We notice that there is a long transaction on the replica that lasts 2 hours. We observe the calm operation of the autovacuum, which is processing dead rows. Everything is running smoothly.
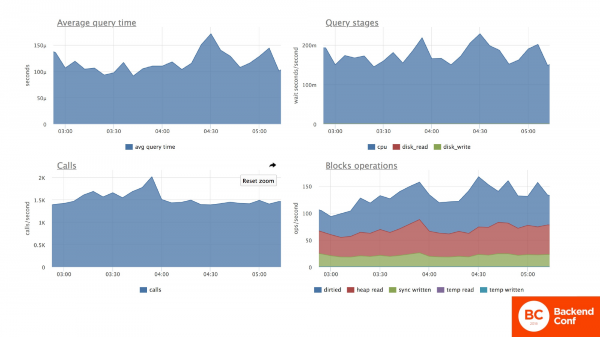
Specifically regarding the test table, we continue to update the balances there. We also have stable response time for queries and stable resource consumption. Everything is going well.
Everything is fine until these reports start firing off due to replication conflicts. And they fire off with regularity.
We dive into the internet and start reading about why this is happening. And we find a solution.
The first solution is to increase the replication delay. We know that our report runs for 3 hours. We set the replication delay to 3 hours. We start everything up, but we still have issues with reports sometimes firing off.
We want everything to be perfect. We dig deeper and find a great setting on the internet – hot_standby_feedback. We enable it. Hot_standby_feedback allows us to hold back the autovacuum work on the Master. This way, we completely eliminate replication conflicts. And everything works well with the reports.
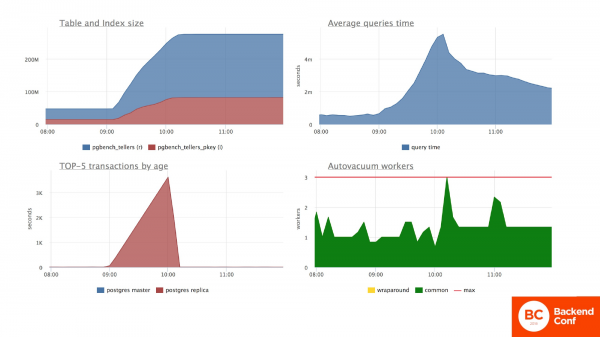
What is happening with the Master server during this time? There is a total disaster occurring on the Master server. Right now, we are observing graphs after I enabled both of these settings. We see that the session on the replica somehow started to affect the situation on the Master server. It truly influences it because it paused the autovacuum that cleans dead rows. The size of the table has skyrocketed again. The average query execution time across the database has also skyrocketed. The autovacuums are slightly stressed.
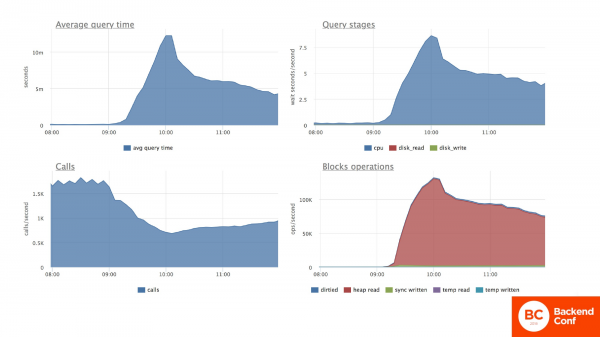
Specifically regarding our table, we see that the data updates have also skyrocketed. CPU resource consumption has similarly increased significantly. We are again processing a large number of dead useless rows. And the response time for this table and the number of transactions have dropped.
What will this look like if we don’t know what I mentioned earlier?
- We are starting to look for problems. If we encountered issues in the first part, we know that it could be due to long transactions, and we dive into the Master. The problem lies with the Master. It's acting up. It's overheating, and its Load Average is nearing a hundred.
- Requests there are lagging, but we don’t see any prolonged transactions. We don’t understand what’s going on. We don’t know where to look.
- We are checking the server hardware. Maybe our RAID has failed. Perhaps a memory stick has burned out. Anything could happen. But no, the servers are new, and everything is working perfectly.
- Everyone is running around: administrators, developers, and the director. Nothing helps.
- And at some point, everything unexpectedly begins to fix itself.
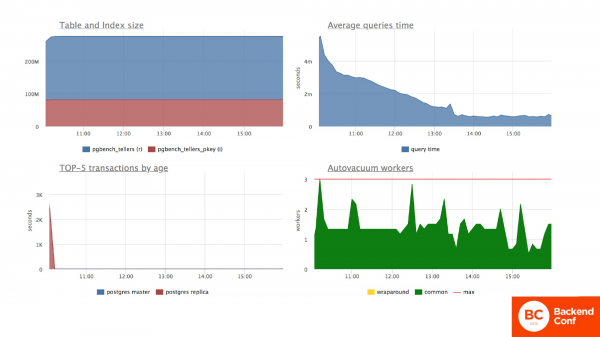
In the meantime, a request on the replica has executed and completed. We received a report. The business is still satisfied. As we can see, our table has grown again and isn’t shrinking. On the session graph, I've left a snippet of this long transaction from the replica so you can evaluate how much time passes until the situation stabilizes.
The session has ended. And only after a while does the server start to restore itself somewhat. The average response time for requests on the Master server returns to normal. Because, finally, the autovacuum has had the chance to clean up, mark those dead rows. And the speed at which it does its job will determine how quickly we return to normal.
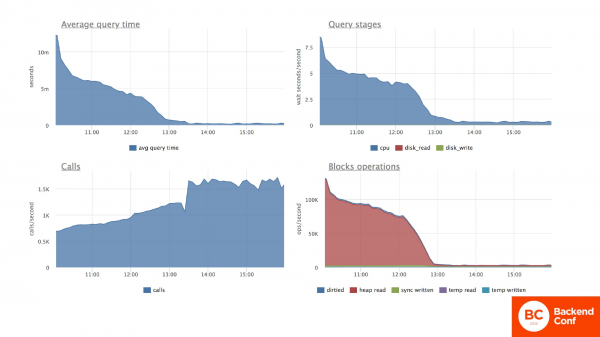
In the test table, where we update the account balances, we see exactly the same pattern. The average time for updating an account is also gradually normalizing. The CPU resource consumption is decreasing as well. And the number of transactions per second is returning to normal. But it's not returning to the level it was at before the outage.
In any case, we experience a drop in performance, just like in the first case, by one and a half to two times, and sometimes even more.
It seems we did everything right. We distributed the load. The equipment isn't idle. We logically divided requests, but it still turned out poorly.
- Should hot_standby_feedback be disabled? Yes, it is generally not recommended to enable it without strong reasons. This setting directly affects the Master server and pauses the autovacuum process there. If you enable it on a replica and forget about it, you could jeopardize the Master and face significant application issues.
- Should max_standby_streaming_delay be increased? Yes, when it comes to reports, that’s true. If you have a three-hour report and you don’t want it to fail due to replication conflicts, simply increase the delay. A long-running report never requires data that has just been inserted into the database. If it runs for three hours, it means you are retrieving data from a previous period. Whether there is a three-hour delay or a six-hour delay makes no difference; you'll consistently receive reports without the risk of failures.
- Naturally, it's necessary to monitor long sessions on replicas, especially if you’ve decided to enable hot_standby_feedback on a replica. Anything can happen. Perhaps you've given this replica to a developer for testing queries. They wrote a complex query, ran it, and went off to have some tea, leaving us with an overloaded Master. Or, we might have allowed an inappropriate application access. There are various scenarios. Sessions on replicas need to be monitored as carefully as they are on the Master.
- If you have fast and long-running queries on replicas, it’s better to distribute the load. This pertains to streaming_delay. For fast queries, maintain one replica with a small replication delay. For lengthy reporting queries, have a replica that can lag by six hours or even a day. This is a perfectly normal situation.
We address the consequences in the same way:
- We identify bloated tables.
- And compress them using the most suitable tool available to us.
The second story concludes here. Let's move on to the third story.
This is also quite common for us, where we perform migration.
- Any software product grows. Its requirements change. We want to evolve regardless. Sometimes, it becomes necessary to update the data in the table, specifically to run an update as part of our migration to accommodate new functionalities that we are implementing in our development.
- The old data format does not suit us. Let's say we now refer to the second table, where I have transactions for these accounts. And suppose they were in rubles, but we decided to increase accuracy and work in kopecks. For that, we need to update: multiply the transaction amount field by one hundred.
- In today's world, we use automated database version control tools. For example, . We document our migration there. We test it on our test database. Everything is great. The update goes through. It blocks activity for a while, but we get updated data. We can launch new functionality based on that. Everything has been tested and confirmed.
- We carried out scheduled work and completed the migration.
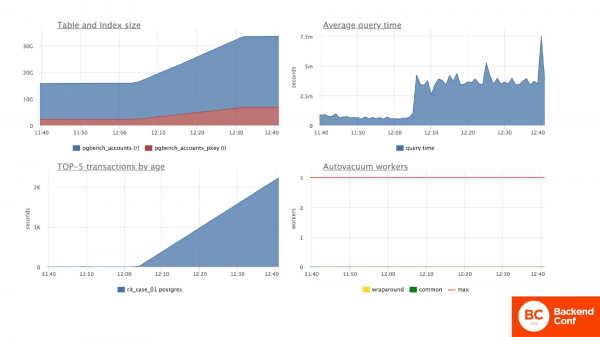
Here is the migration with the update presented before you. Since these are my account operations, the table was 15 GB. And since we are updating each row, we bloated the table twice because we re-recorded every row.
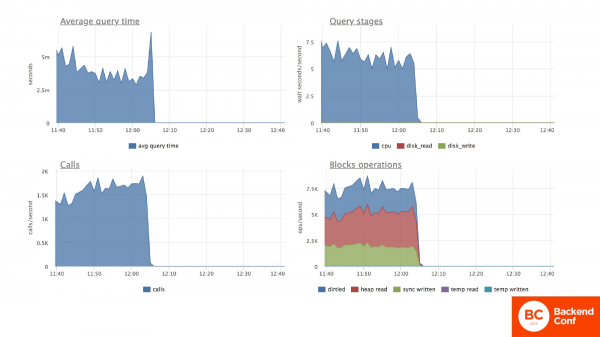
During the migration, we couldn't do anything with this table because all requests to it were queued and waiting for this update to finish. But here I want to draw your attention to the numbers on the vertical axis. That is, we have an average query time before migration of about 5 milliseconds and CPU load, with fewer block read operations from disk memory than 7.5.
We conducted the migration and encountered problems again.
The migration was successful, but:
- The old functionality has become slower.
- The table has grown in size again.
- The server load has increased more than it was.
- And, of course, while we are still working on the functionality that was working well, we have improved it a little.
And this is again bloat, which makes our lives difficult.
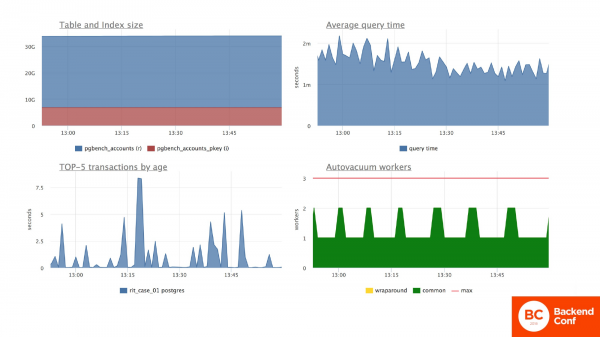
Here I demonstrate that the table, as in the previous two cases, does not intend to return to its previous size. The average server load seems to be adequate.
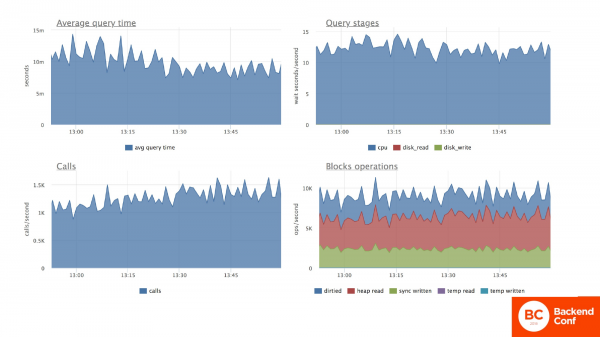
If we look at the billing table, we can see that the average query time has doubled for this table. The CPU load and the number of lines processed in memory have jumped above 7.5, whereas it was below that. And it jumped by a factor of two for CPUs and by 1.5 for block operations, which means we have experienced a degradation in server performance. Consequently, this has led to a degradation in the performance of our application. Meanwhile, the number of calls remained approximately at the same level.
Here, it is crucial to understand how to properly execute such migrations. These need to be done. We consistently perform these migrations.
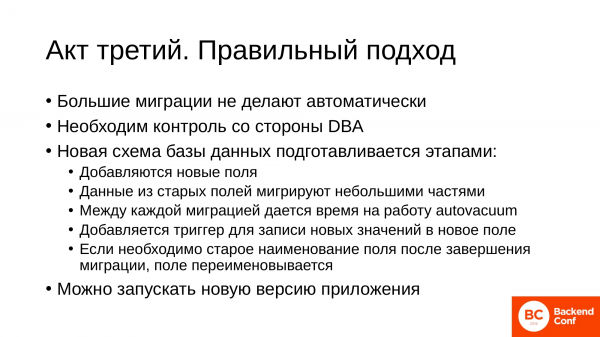
- Such large migrations are not done automatically. They should always be under control.
- Control is necessary from a knowledgeable person. If you have a DBA on your team, let them handle it. That’s their job. If not, then the most experienced person who knows how to work with databases should do it.
- A new database schema, even if we are updating just one column, is always prepared in stages, i.e., in advance before the new version of the application is rolled out:
- New fields are added where we will write the updated data.
- We transfer data from the old field to the new field in small batches. Why do we do this? First, we always control this process. We know how many batches we’ve transferred and how many are left.
- Secondly, a positive aspect is that between each batch, we close the transaction, open a new one, and this allows the autovacuum to process the table, marking dead rows for reuse.
- For the rows that will appear during the application's operation (since our old application is still running), we add a trigger that records the new values in the new fields. In our case, this involves multiplying the old value by one hundred.
- If we are stubborn and want to keep the same field, then after all migrations are completed and before deploying the new version of the application, we simply rename the fields. The old ones to some invented name, and the new fields to the names of the old ones.
- Only after that do we launch the new version of the application.
This way, we will not encounter bloat and will not see a drop in performance.
This is where the third story ends.
And now, a bit more detail about the tools I mentioned in the very first story.
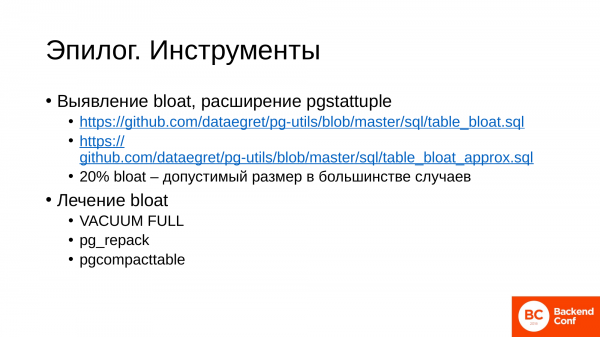
Before looking for bloat, you must definitely install the extension. .
To save you from having to come up with queries, we've already written these queries in our work. You can use them. Here are two queries presented.
- The first one takes quite a while to run, but it will show you the exact bloat values for the table.
- The second one runs faster and is very effective when you need a quick assessment of whether there is bloat or not in the table. And you should also understand that bloat in a Postgres table always exists. This is a feature of its MVCC model.
- And 20% bloat is normal for tables in most cases. So, you don't need to worry about compressing that table.
We figured out how to identify tables that have bloated, especially when they bloated with useless data.
Now, about how to fix bloat:
- If we have a small table and good disks, i.e., on a table up to a gigabyte, you can safely use VACUUM FULL. It will take an exclusive lock on the table for a few seconds, and that'll be fine, as it will execute everything quickly and efficiently. What does VACUUM FULL do? It takes an exclusive lock on the table and rewrites live rows from old tables into a new table. Then it swaps them. It deletes the old files and replaces them with the new ones. But during its operation, it takes an exclusive lock on the table. This means you won't be able to do anything with this table: not write to it, not read from it, nor modify it. And VACUUM FULL requires additional disk space to write the data.
- The next tool is similar in principle to VACUUM FULL because it also rewrites data from old files to new and replaces them in the table. However, it does not take an exclusive lock on the table at the very beginning; it only takes one when it has ready data to replace the files. Its disk resource requirements are similar to those of VACUUM FULL. You will need additional disk space, which can sometimes be critical if you have terabyte tables. It's also quite CPU-intensive because it actively engages in input-output operations.
- The third utility is It handles resources more carefully because it operates on slightly different principles. The main idea of pgcompacttable is that it moves all live rows to the top of the table during updates. Then it runs a vacuum on this table because we know that the live rows are at the beginning and the dead rows are at the end. The vacuum then trims this tail, meaning it doesn’t require much additional disk space. Additionally, it can be resource-conservative.
Everything is with the tools.
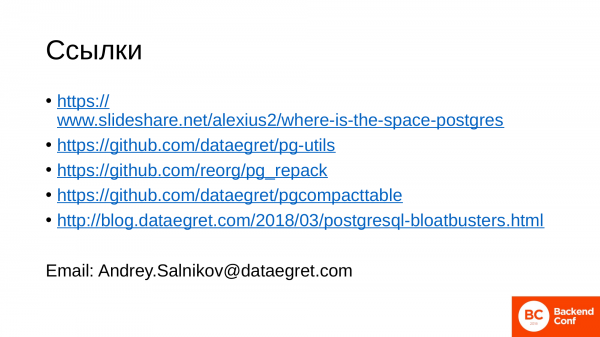
If you find the topic of bloat interesting for further exploration, here are some useful links:
- – this is a presentation by my colleague. It provides an overview of where space goes in Postgres during its operation and lifespan. There is a substantial technical segment for database administrators regarding bloat.
- – this is a link to our repository where we store a bunch of useful scripts for checking the database state. There, you can find scripts for identifying bloat.
- and links to tools that will help you compact tables.
- – this is a post by my colleague. He seriously and technically examines bloat at a level close to that of administrators.
I tried to illustrate the alarming aspects for developers because they are our direct database clients and need to understand the implications of their actions. I hope I succeeded. Thank you for your attention!
Questions
Thank you for the presentation! You spoke about how to identify issues. How can we prevent them? I had a situation where queries were hanging not only because they called some external services. There were just some crazy joins. There were some tiny harmless queries that hung for a day and then started causing issues. This closely resembles what you described. How can this be monitored? Should we sit and constantly check which query is stuck? How can we prevent this?
In this case, it is a task for your company's administrators, not necessarily for the DBA.
I am an administrator.
In PostgreSQL, there is a view called pg_stat_activity, which shows the hanging queries. You can see how long they have been stuck there.
Do I have to check every 5 minutes?
Set up cron and check. If you have a long-running query, send an email and that's it. You don't need to watch it with your own eyes; this can be automated. You will receive an email, and you respond to it. Alternatively, you could automate the notifications.
Are there clear reasons why this is happening?
I listed some. Other examples are more complex, and the discussion could take a long time.
Thank you for the report! I wanted to clarify about the pg_repack utility. If it doesn't create an exclusive lock, then...
It does create an exclusive lock.
… then I might potentially lose data. My application shouldn't be writing to it during this time?
No, it works with the table just fine, meaning pg_repack first moves over all the live rows. Naturally, there is some kind of write occurring in the table. It just appends that extra tail.
So, in the end, it does?
In the end, it takes an exclusive lock to swap those files.
Will this be faster than VACUUM FULL?
VACUUM FULL, as soon as it starts, immediately takes an exclusive lock. And it won't release it until everything is done. Whereas pg_repack only takes an exclusive lock at the moment of file replacement. At that moment, you won't be able to write to it, but the data won't be lost and everything will be okay.
Hello! You talked about the operation of autovacuum. There was a chart with red, yellow, and green cells. That is, the yellow ones were marked as deleted. Can something new be written into them as a result?
Yes. Postgres doesn't delete rows. That's its specific nature. If we update a row, we mark the old one as deleted. The transaction ID that changed this row is placed there, and we write a new row. We have sessions that can potentially read them. At some point, they become quite old. The essence of autovacuum's operation is that it goes through these rows and marks them as unnecessary. You can then overwrite the data there.
I understand. But the question is slightly different. I didn't finish my thought. Suppose we have a table. It has variable size fields. If I try to insert something new, it may simply not fit in the old cell.
No, in any case the entire line is updated. Postgres has two data storage models. It chooses based on the data type. Some data is stored directly in the table, while other data, such as tos-data, is stored separately. These are large volumes of data: text, json. They are kept in separate tables, and the same story with bloat occurs there, meaning everything remains the same. They are just placed separately.
Thank you for the presentation! How acceptable is it to use statement timeout to limit the duration of requests?
Very acceptable. We use it everywhere. Since we do not have our own services and provide remote support, we have quite diverse clients. Everyone is quite satisfied with this. We have cron jobs that monitor this. The session duration is agreed upon with the client, less than which we do not terminate. It can be a minute or 10 minutes. It depends on the load on the database and its purpose. But we use pg_stat_activity for all clients.
Thank you for the presentation! I'm trying to relate your talk to my applications. It seems we start transactions everywhere and explicitly finish them everywhere. If there is an exception, a rollback still occurs. And then I started to wonder. A transaction can be started implicitly, right? This advice is probably for the lady. If I simply update a record, will the transaction begin in PostgreSQL and will it only end when the connection is terminated?
If you are now talking about the application level, it depends on the driver you are using and the ORM that is employed. There are many settings. If you have auto commit on, the transaction starts and closes immediately.
So it closes right after the update?
It depends on the settings. I mentioned one setting: auto commit on. It is quite common. If it is enabled, the transaction opens and closes immediately. If you did not explicitly say 'start transaction' and 'end transaction', but just executed a request in the session.
Hello! Thank you for the presentation! Let's imagine we have a database that is swelling and there is no more space on the server. Are there any tools to fix this situation?
Space on the server needs to be monitored properly.
For example, the DBA went to drink tea, was on vacation, etc.
When a file system is created, at least some reserved space is generated where no data is written.
What if it’s completely empty?
It’s called reserved space, meaning it can be freed up, and depending on how large it was created, you get free space. By default, I don't know how much is there. In another case, you need to deliver disks to have space for recovery operations. You can delete a table that you are sure you don't need.
Are there no other tools?
It's always manual work. It’s determined on-site what’s best to do because there are critical and non-critical data. For each database and application that works with it, it depends on the business. It’s always decided on-site.
Thank you for your presentation! I have two questions. First, you showed slides illustrating that in the case of hung transactions, both the volume of table space and the index size increase. Then there were a lot of utilities in the presentation that pack the table. What about the index?
They also pack them.
But vacuum does not affect the index?
Some work with the index. For example, pg_rapack, pgcompacttable. Vacuum recreates indexes; it does affect them. The essence of VACUUM FULL is to rewrite everything, meaning it works with all of them.
And the second question. I didn’t understand why reports on replicas are so dependent on the replication itself. I thought reports are for reading, and replication is for writing.
What causes a replication conflict? We have a Master where processes occur. We have autovacuum happening. What does autovacuum actually do? It removes some old rows. If at this time a request on the replica is reading those old rows, and on the Master the autovacuum has marked those rows as possible for rewriting, we rewrite them. When we receive a data packet, needing to rewrite the rows requested on the replica, the replication process will wait for the timeout you’ve configured. Then PostgreSQL will decide what is more important for it. Replication is more important than the request, so it will terminate the request to make those changes on the replica.
Andrey, I have a question. Those wonderful graphs you showed during the presentation, are they the result of some utility of yours? What tool did you use to create the graphs?
This is a service .
Is this a commercial product?
Yes. This is a commercial product.
Source: habr.com
