

Legitimate traffic in the DDoS-Guard network recently surpassed one hundred gigabits per second. Currently, 50% of all our traffic is generated by our clients' web services. This includes many tens of thousands of domains, very diverse and, in most cases, requiring an individual approach.
Below we explain how we manage front nodes and issue SSL Certificates for hundreds of thousands of websites.
Setting up a front for a single website, even a very large one, is simple. We take nginx or haproxy or lighttpd, configure it according to guides, and forget about it. If something needs to change, we reload and forget again.
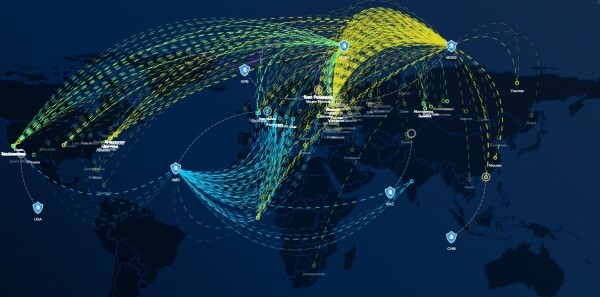
Everything changes when you handle large volumes of traffic on the fly, assess the legitimacy of requests, compress and cache user content, and change parameters several times per second. A user expects to see results on all external nodes immediately after changing settings in their personal account. Also, a user may upload several thousand (sometimes even tens of thousands) domains with individual traffic processing parameters via API. All of this needs to work immediately in America, Europe, and Asia — a not trivial task, considering that in Moscow alone there are several physically dispersed filtering nodes.
Why have many large reliable nodes around the world?
- The quality of service for client traffic — requests from the USA need to be processed in the USA (including for attacks, parsing, and other anomalies), rather than being routed to Moscow or Europe, unpredictably increasing processing latency.
- Attacking traffic needs to be localized — transit operators may degrade during attacks, whose volumes often exceed 1Tbps. Transporting attacking traffic over transatlantic or transasiatic links is not the best idea. We've had real cases where Tier-1 operators said: 'The volumes of attacks you are taking are dangerous for us.' This is why we accept incoming flows as close to their sources as possible.
- Stringent service continuity requirements mean that the cleaning centers must not depend on each other or on local events in our rapidly changing world. Did a power outage affect all 11 floors of MMT-9 for a week? — No problem. No client, not physically connected to this location, will be impacted, and web services will remain unaffected under any circumstances.
How to manage all this?
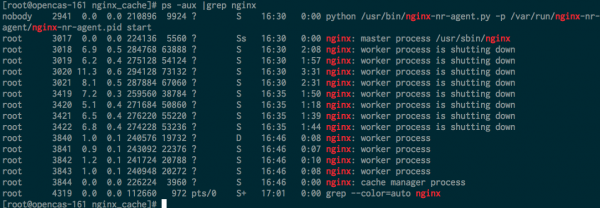
Service configurations must be propagated to all front nodes as quickly as possible (ideally instantly). It is not sufficient to just modify text configurations and restart daemons with each change — even nginx holds on to terminating processes (worker shutting down) for several minutes (and sometimes even hours if there are long websocket sessions).
During the configuration reload of nginx, the following scenario is quite normal:
Regarding memory usage:
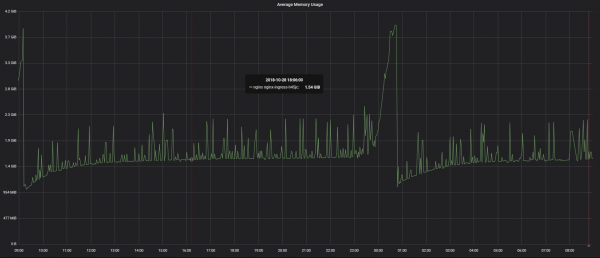
Old workers consume memory, including non-linearly dependent on the number of connections — this is normal. When the client connections close, this memory will be freed up.
Why wasn’t this an issue when nginx was just starting to develop? There were neither HTTP/2 nor WebSocket, nor a multitude of long keep-alive connections. 70% of our web traffic is HTTP/2, which involves very long connections.
The solution is simple — do not use nginx, do not manage front ends based on text files, and certainly do not transmit compressed text configurations across transoceanic channels. The channels are guaranteed and reserved, but they are no less transcontinental.
We have our own front-server balancer, the details of which I will discuss in upcoming articles. The main capability is to apply thousands of configuration changes per second on the fly, without restarts, reloads, or surges in memory usage. This is quite similar to Hot Code Reload, as seen in Erlang. Data is stored in a geo-distributed key-value database and is immediately accessed by the front-end execution mechanisms. For instance, you uploaded an SSL certificate through the web interface or API in Moscow, and within seconds, it is ready for use in our clearing center in Los Angeles. If a world war breaks out, and the internet goes down globally, our nodes will continue to operate autonomously and will resolve split-brain conditions once one of the dedicated channels—Los Angeles-Amsterdam-Moscow, Moscow-Amsterdam-Hong Kong-Los Angeles or even one of the backup overlay GRE—is available.
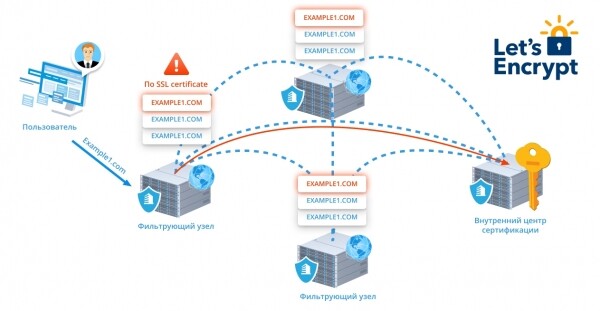
This same mechanism allows us to instantly issue and renew Let’s Encrypt certificates. In very simple terms, this works like this:
- As soon as we see at least one HTTPS request for our client's domain without a certificate (or with an expired certificate), the external node that received the request informs the internal certification center.

- If the user has not prohibited the issuance of Let’s Encrypt, the certification center generates a CSR, obtains a validation token from LE and sends it to all fronts over an encrypted channel. Now any node can validate the request from LE.
- In just a few moments, we will receive a valid certificate and private key and promptly distribute them to the fronts again without rebooting the daemons.
- Seven days before the expiration date, the certificate renewal procedure is initiated.
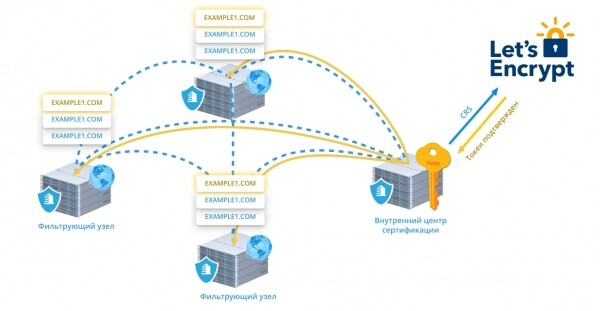
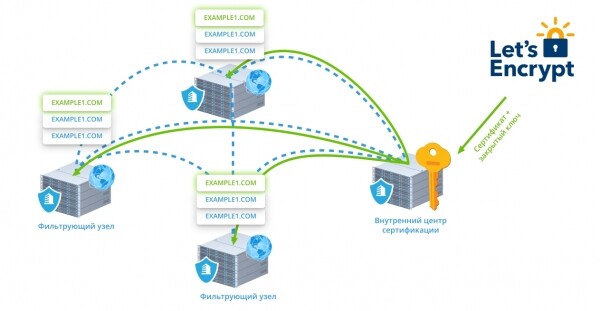
Right now, we are rotating 350,000 certificates in real-time completely transparently for users.
In the upcoming articles of this series, I will discuss other features of real-time processing of large web traffic—such as analyzing RTT using incomplete data to improve service quality for transit clients, safeguarding transit traffic against terabit attacks, information delivery and aggregation about traffic, WAF, an almost limitless CDN, and numerous content delivery optimization mechanisms.
Only registered users can participate in the survey. Please log in, please.
What would you like to learn about first?
- 14,3%Clustering algorithms and web traffic quality analysis<3
- 33,3%The inner workings of DDoS-Guard Load Balancers7
- 9,5%Protection of transit L3/L4 traffic2
- 0,0%Protection of websites on transit traffic0
- 14,3%Web Application Firewall3
- 28,6%Protection against scraping and clicking6
21 users voted. 6 users abstained.
Source: habr.com
