

VictoriaMetrics — a fast and scalable time-series database for storing and processing time-series data (a record consists of time and a set of corresponding values for that time, such as those obtained through periodic polling of sensor states or gathering metrics).
My name is Pavel Kolobaev. DevOps, SRE, LeroyMerlin, everything as code — it's all about us: about me and other LeroyMerlin employees.
There is a cloud based on OpenStack. There's a small link to the tech radar.
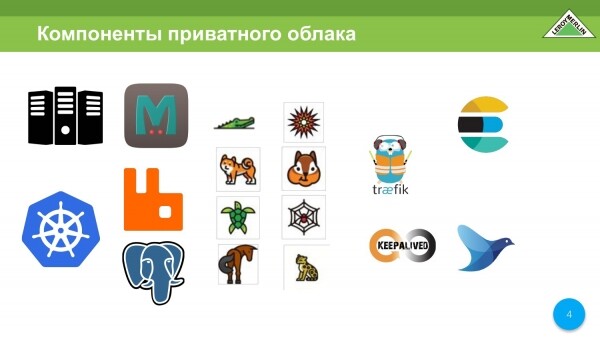
It is built on Kubernetes hardware, along with all the accompanying services for OpenStack and logging.
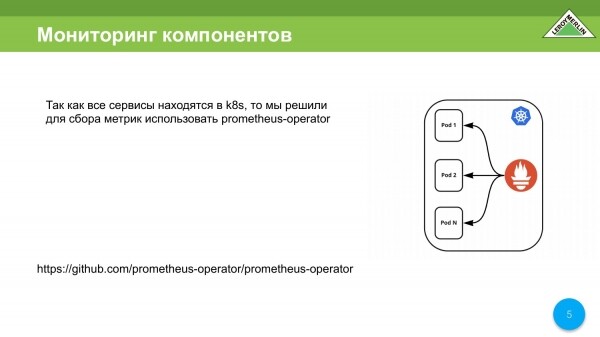
Here's the scheme we had during development. When we were developing all this, we had a Prometheus operator that stored data within the K8s cluster itself. It automatically finds what needs to be scraped and puts it together, so to speak.
We need to move all data outside the Kubernetes cluster because if something happens, we must understand what and where it is.
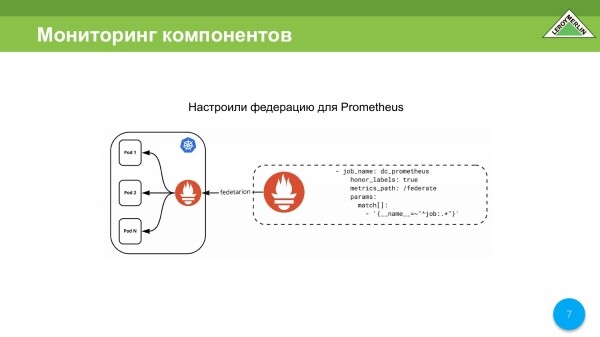
The first solution is to use federation when we have an external Prometheus that queries the Kubernetes cluster through the federation mechanism.
But there are some minor problems. In our case, problems started when we had 250,000 metrics, and when it grew to 400,000 metrics, we realized we couldn’t operate this way. We increased the scrape_timeout to 25 seconds.
Why did we have to do this? Prometheus starts counting the timeout from the moment of collection. It doesn’t matter that the data is still flowing. If the data hasn’t been processed and the session isn’t closed via http within this specified time frame, the session is considered failed, and the data doesn't reach Prometheus.
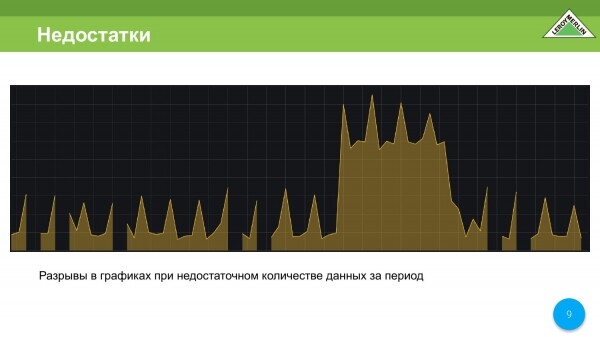
Everyone is familiar with the graphs we get when some data is missing. The graphs are jagged, and that's unacceptable for us.
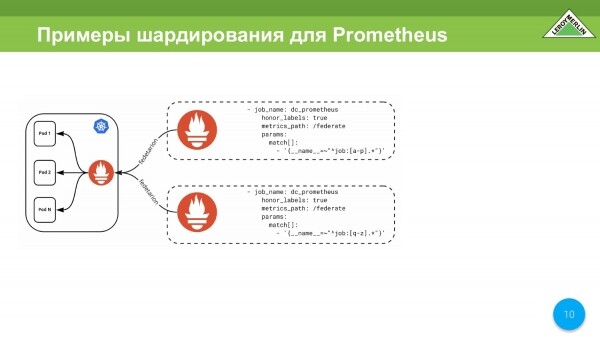
The next option is sharding based on two different Prometheus instances through the same federation mechanism.
For instance, just take and shard them by name. This can also be used, but we decided to move further.
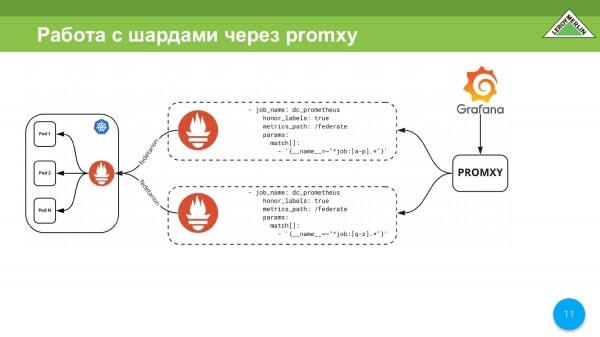
Now we need to somehow process these shards. We can use promxy, which goes to the shard area and multiplies the data. It operates with two shards as a single entry point. This can be implemented through promxy, but it is currently too complex.
The first option — we want to abandon the federation mechanism because it is very slow.
The developers of Prometheus clearly state: "Guys, use other TimescaleDB, because we won't support long-term storage of metrics." It's not their responsibility. 
We note down on paper that we still need to export data to avoid storing everything in one place.
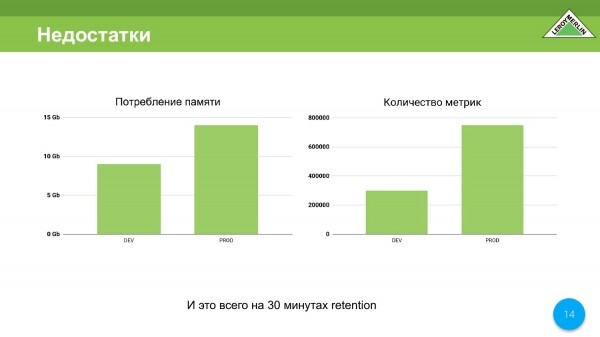
The second drawback is memory consumption. Yes, I understand that many will say that in 2020, a couple of gigabytes of memory is inexpensive, but nonetheless.
Currently, we have dev and prod environments. In dev, that's about 9 gigabytes for 350,000 metrics. In prod, it's just over 14 gigabytes for 780,000 metrics. Meanwhile, our retention time is only 30 minutes. This is bad. And I'll explain why.
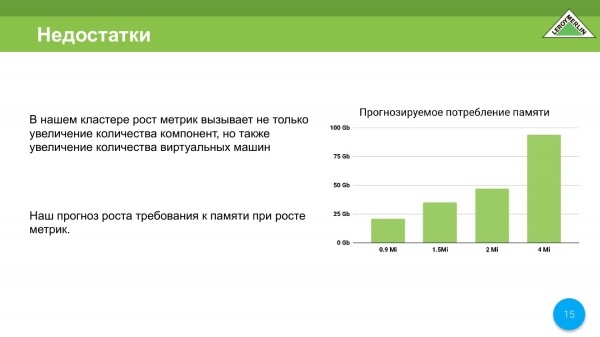
We're calculating that with one and a half million metrics, which we're already nearing, at the design stage we would need 35-37 gigabytes of memory. By the time we reach 4 million metrics, about 90 gigabytes of memory would be required. This was calculated based on the formula provided by the Prometheus developers. We looked at the correlation and realized we don't want to pay a couple of million for a server solely for monitoring.
Not only will the number of machines increase, but we are also monitoring the virtual machines themselves. Thus, the more virtual machines, the more different kinds of metrics, and so on. We will see a special growth in our cluster regarding metrics.
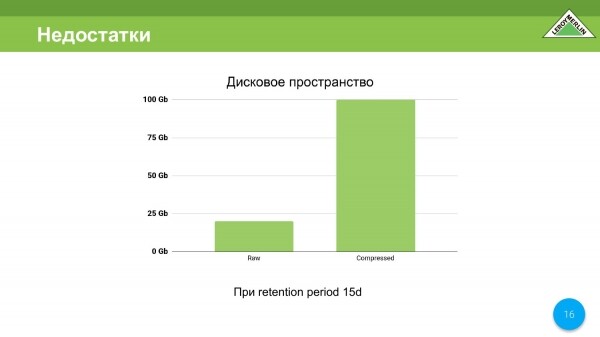
The situation with disk space isn't as dire, but improvements would be welcome. Over 15 days, we accumulated a total of 120 gigabytes, of which 100 are compressed data, 20 are uncompressed data, but we always wish for less.
Accordingly, we add another point — the high resource consumption, which we still want to save, because we don't want our monitoring cluster to consume more resources than our cluster managing OpenStack.
There's another drawback of Prometheus that we've identified, which is a lack of any memory limits. Things are much worse with Prometheus since it doesn't have any knobs to tweak here. Using limits in Docker is also not an option. If your RAF fails and there are 20-30 gigabytes in use, recovery will take a very long time.
This is yet another reason why Prometheus is unsuitable for us — it doesn't allow you to limit memory consumption.
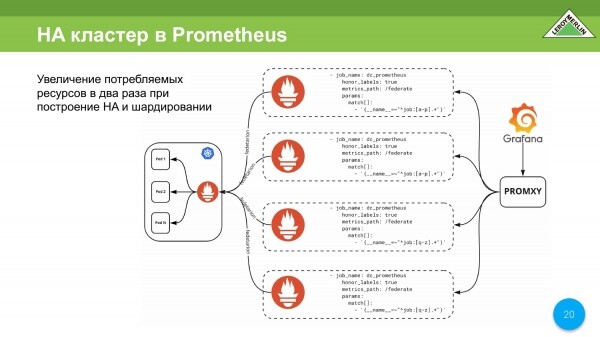
We could adopt such a scheme. This scheme is necessary for us to organize an HA cluster. We want our metrics to be available at all times and everywhere, even if the server that stores these metrics goes down. Therefore, we need to build this kind of setup.
This scheme indicates that there will be duplication of shards, and consequently, duplication of the resources consumed. It can scale almost horizontally, but nevertheless, resource consumption will be immense.
The shortcomings in the order we outlined for ourselves are as follows:
- Metrics need to be exported externally.
- High resource consumption.
- Memory consumption cannot be limited.
- Complex and resource-intensive HA implementation.
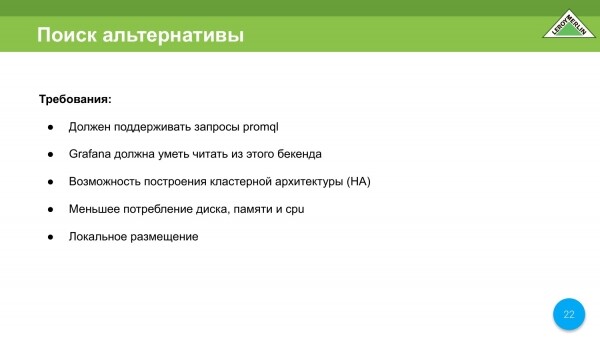
We've decided to move away from Prometheus as a storage solution.
We have also determined additional requirements that we need. These are:
- Support for promql, because a lot has already been written for Prometheus: queries, alerts.
- And then there's Grafana, which is also developed for Prometheus as a backend. We don't want to rewrite the dashboards.
- We want to build a proper HA architecture.
- We aim to reduce the consumption of any resources.
- There's one more small nuance. We can't use various cloud metric collection systems. We don't know what will end up in these metrics yet. Since anything could be sent there, we're forced to stick to local deployment.
The choice was limited. We gathered everything we had experience with. We looked at the Prometheus integration page, read a bunch of articles, and assessed what is available. For ourselves, we chose VictoriaMetrics as a replacement for Prometheus.
Why? Because:
- It supports promql.
- It has a modular architecture.
- It requires no changes in Grafana.
- And most importantly, we may provide metric storage within our company as a service, so we are proactively looking into various limitations, allowing users to use cluster resources in a limited way, as there is a chance it will be multitenant.
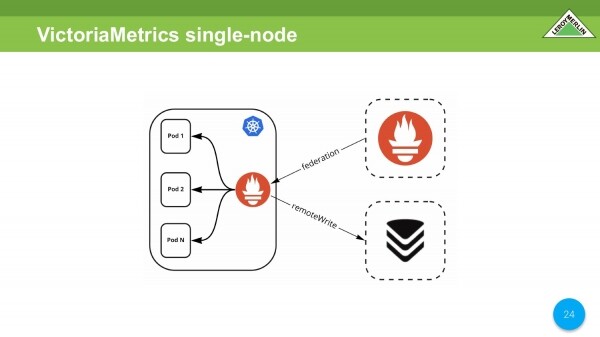
We are making the first comparison. We take the same Prometheus within the cluster, with external Prometheus accessing it. We add VictoriaMetrics via remoteWrite.
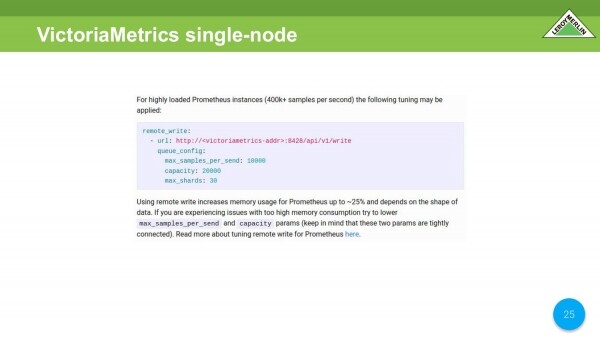
Let me clarify that we've observed a slight increase in CPU usage from VictoriaMetrics here. The VictoriaMetrics wiki indicates which parameters are best suited. We checked them, and they significantly reduced CPU consumption.
In our case, the memory usage of Prometheus running in the Kubernetes cluster increased only slightly.
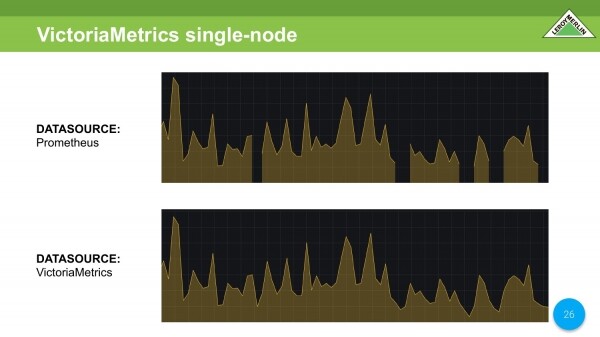
We are comparing two data sources of the same data. In Prometheus, we see all the same missing data. In VictoriaMetrics, everything is fine.
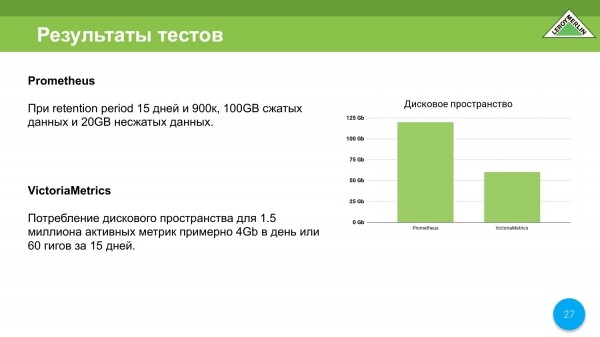
Test results regarding disk space. We accumulated 120 gigabytes in Prometheus. With VictoriaMetrics, we're getting about 4 gigabytes per day. The mechanism there is slightly different from what we are used to in Prometheus. In other words, the data is already well compressed within just a day or even half an hour. They are already well compressed within that timeframe, even though the data will later be merged. As a result, we saved on disk space.
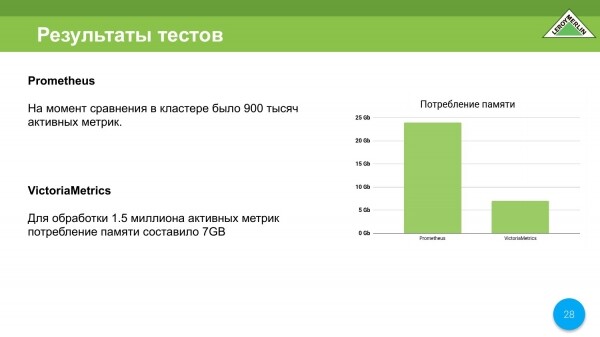
We also save on memory resource consumption. During the tests, Prometheus was deployed on a virtual machine with 8 cores and 24 gigabytes of RAM. Prometheus consumes almost everything and crashed due to the OOM Killer, while only feeding on 900,000 active metrics. That amounts to about 25,000-27,000 metrics per second.
We ran VictoriaMetrics on a two-core virtual machine with 8 gigabytes of RAM. We managed to make VictoriaMetrics work efficiently by tweaking a few things on an 8-gigabyte machine. Ultimately, we kept it under 7 gigabytes while achieving a content delivery speed, that is, metrics output, even higher than Prometheus.
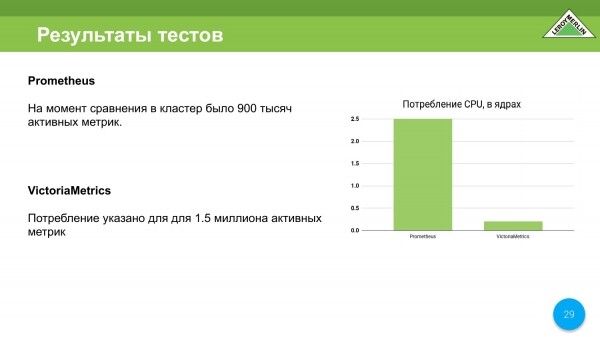
CPU usage improved significantly compared to Prometheus. Here, Prometheus consumes 2.5 cores while VictoriaMetrics uses only 0.25 cores. Initially, it was 0.5 cores. As it merges, it approaches one core, but that's extremely rare.
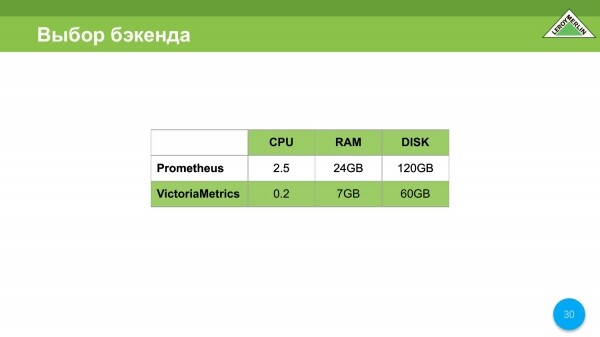
In our case, we opted for VictoriaMetrics for obvious reasons; we wanted to save costs and we did.
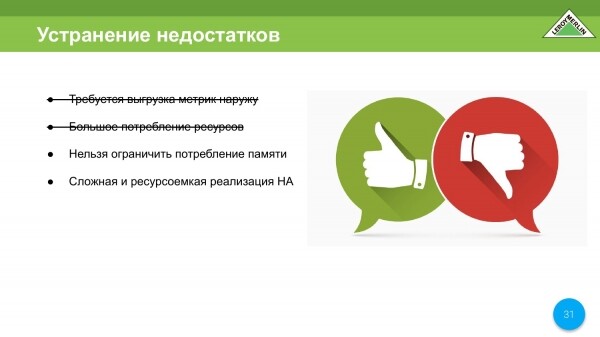
We can immediately dismiss two points: exporting metrics and high resource consumption. We still need to address two points that we've kept for ourselves.
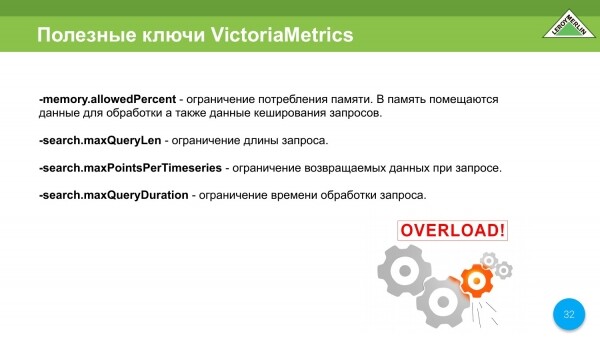
Here, I should specify that we consider VictoriaMetrics as a metrics storage solution. However, since we will likely provide VictoriaMetrics as a storage option for all of Leroy, we need to restrict those who will use this cluster to prevent it from being overloaded.
There is a wonderful parameter that allows us to limit by time, data volume, and execution time.
There is also a great option that lets us limit memory consumption, thereby allowing us to find the right balance to achieve normal operating speed and reasonable resource consumption.
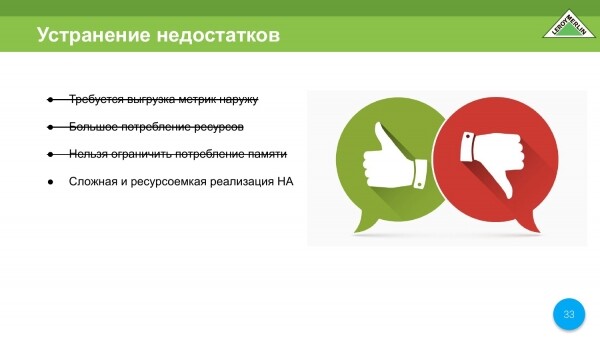
Another point to note is that we cannot limit memory consumption.
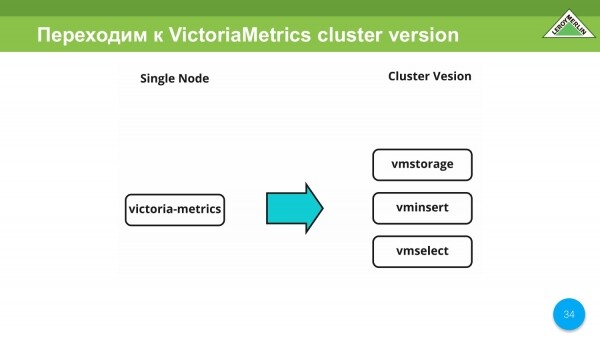
In the initial iterations, we tested VictoriaMetrics Single Node. Next, we move on to the VictoriaMetrics Cluster Version.
Here we have more flexibility in distributing different services in VictoriaMetrics based on what they will run on and what resources they will consume. This is a very flexible and convenient solution. We've used it ourselves.
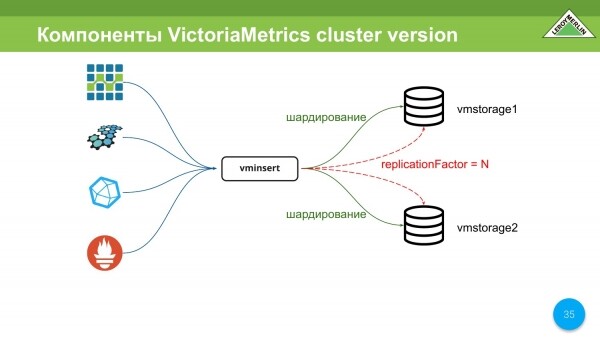
The main components of VictoriaMetrics Cluster Version are vmstorage. There can be an N number of these. For now, we have 2.
And there is vminsert. This is a proxy server that allows us to shard across all the storages we’ve informed it about, and it also allows replication, which means you will have both sharding and replication.
Vminsert supports the protocols OpenTSDB, Graphite, InfluxDB, and remoteWrite from Prometheus.
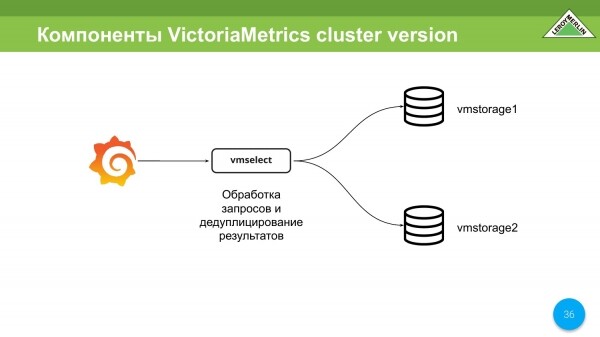
There is also vmselect. Its main task is to query vmstorage, fetch data from them, deduplicate this data, and return it to the client.
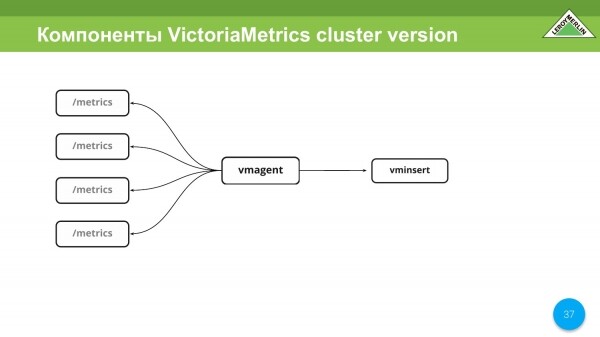
There is a wonderful thing called vmagent. We really like it. It configures just like Prometheus and works exactly the same way. That is, it collects metrics from different entities and services and sends them to vminsert. After that, it all depends on you.
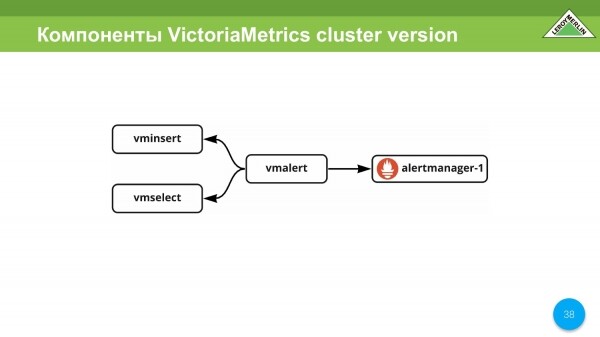
Another fantastic service is vmalert, which allows using VictoriaMetrics as a backend, receiving processed data from vminsert and sending it to vmselect. It processes alerts and rules. In the case of alerts, we receive the alert through alertmanager.
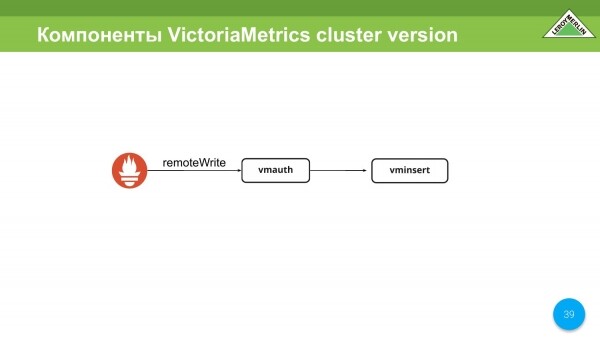
There is a component called wmauth. We might use it, or we might not (we haven’t decided yet) as an authorization system for the multitenancy version of clusters. It supports remoteWrite for Prometheus and can authorize based on the URL, specifically its second part, which determines where you are allowed or not allowed to write.
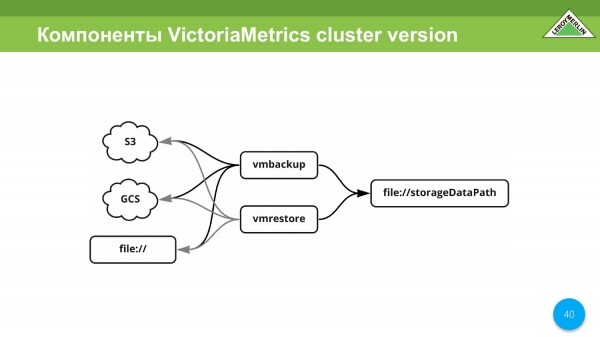
There is also vmbackup and vmrestore. Essentially, these are recovery and backup of all data. It supports S3, GCS, and file.
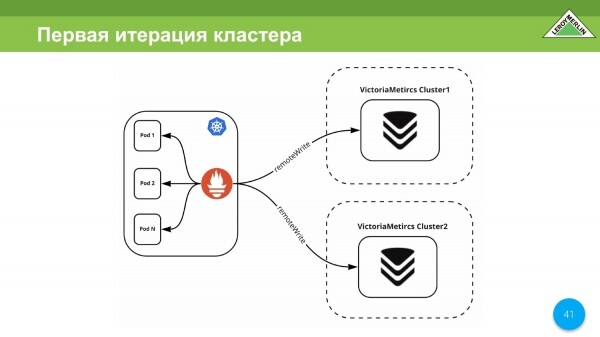
The first iteration of our cluster was made during the quarantine. At that time, there was no replica, so our iteration consisted of two different and independent clusters, from which we received data via remoteWrite.
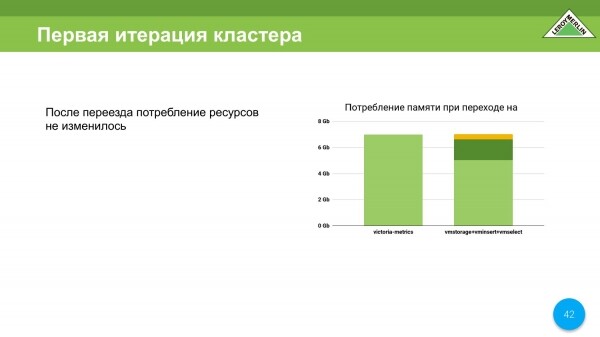
Here I should clarify that when we transitioned from VictoriaMetrics Single Node to VictoriaMetrics Cluster Version, we remained within the same resource consumption, i.e., the primary concern was memory. This is how our data was distributed in terms of resource consumption.
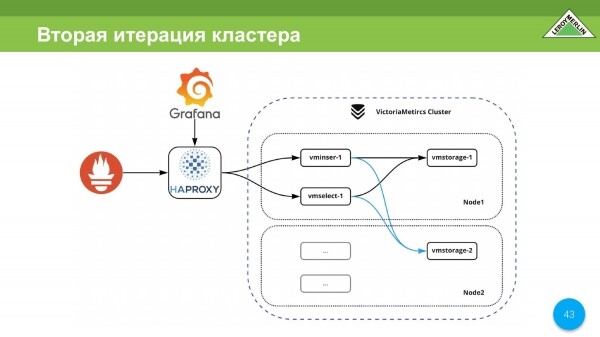
A replica was added here. We combined everything into one relatively large cluster. All our data is both sharded and replicated.
The entire cluster has N entry points, meaning Prometheus can add data through HAPROXY. Here is our entry point. This entry point allows access with Grafana.
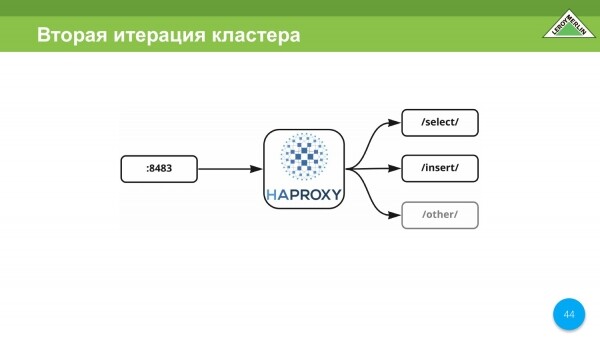
In our case, HAPROXY is the only port that proxies select, insert, and other services into this cluster. We couldn’t use a single address; we had to create several entry points because the virtual machines running the VictoriaMetrics cluster are located in different zones of one cloud provider, i.e., outside of our cloud, not inside.
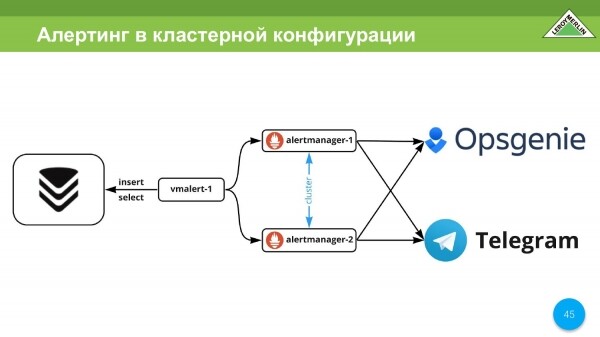
We have alerting in place. We utilize Prometheus' alertmanager. For alert delivery, we use Opsgenie and Telegram. In Telegram, we receive alerts from development, possibly some from production, but mostly statistical information needed by engineers. Opsgenie handles critical alerts. These include calls and incident management.
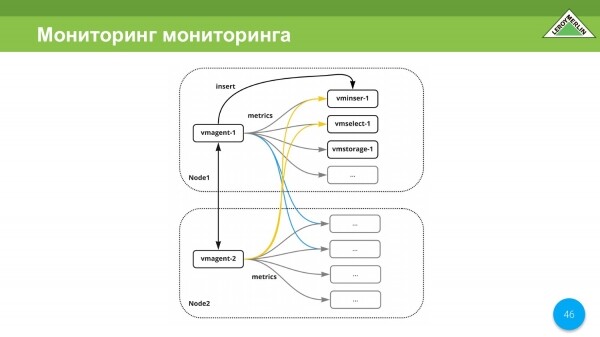
The eternal question: 'Who monitors the monitoring?'. In our case, monitoring itself monitors the monitoring because we use vmagent on every node. And since our nodes are spread across different data centers of one provider, each data center has its own channel; they are independent. Even if there is a split brain scenario, we will still receive alerts. Yes, there will be more alerts, but it's better to get more alerts than none.
We conclude our list with the implementation of HA.
I would also like to highlight my experience communicating with the VictoriaMetrics community. It has been very positive. The team is responsive. They try to understand every case presented.
I opened issues on GitHub. They were resolved very quickly. There are still a couple of issues that are not fully closed, but I can already see from the code that work in this direction is ongoing.
The main pain point during iterations for me was that when I shut down a node, the first 30 seconds my vminsert couldn't understand that the backend was down. This has now been resolved. Now, within a second or two, data is retrieved from all remaining nodes, and the request no longer waits for the missing node.
At one point, we wanted to have the VictoriaMetrics operator. We have now got it. We are currently actively building a wrapper over the VictoriaMetrics operator to incorporate all pre-calculating rules, etc., from Prometheus, as we actively use the rules that come with the Prometheus operator.
There are suggestions for improving the cluster implementation. I outlined them above.
And I would really like downsampling. In our case, downsampling is needed solely for trend analysis. In rough terms, one metric throughout the day is sufficient for me. These trends are needed for one year, three years, five years, ten years. One metric value is quite adequate.
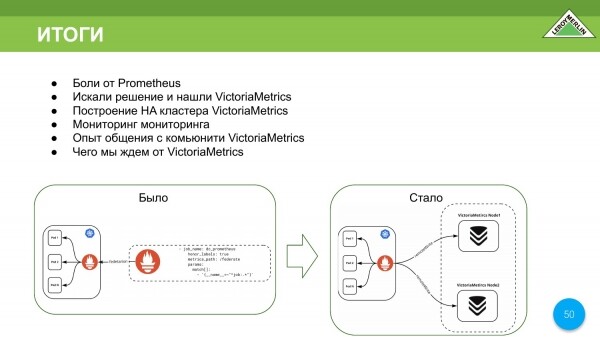
- We have felt the pain, like some of our colleagues, when using Prometheus.
- We have chosen VictoriaMetrics for ourselves.
- It scales quite well both vertically and horizontally.
- We can distribute various components across different nodes in the cluster, limit them by memory usage, increase memory, etc.
We will use VictoriaMetrics internally because we liked it very much. Here’s what it was and what it has become.
A couple of QR codes for the VictoriaMetrics chat, my contacts, the tech radar of LeroyMerlin.
Source: habr.com
