

Today we will discuss the principles and models of GitOps, as well as how these models are implemented on the OpenShift platform. An interactive guide on this topic is available. .
In brief, GitOps is a set of practical methods for using Git pull requests to manage infrastructure and application configurations. In GitOps, the Git repository is viewed as the single source of truth for the system state, with any changes to this state being fully traceable and auditable.
The idea of tracking changes in GitOps is not new; this approach has long been widely applied in application source code management. GitOps simply implements similar functions (review checks, pull requests, tags, etc.) for managing infrastructure and application configurations, providing similar benefits as in source code management.
GitOps does not have any academic definition or approved set of rules; it is simply a set of principles that underpin this practice:
- The declarative description of the system is stored in a Git repository (configs, monitoring, etc.).
- State changes are made through pull requests.
- The state of running systems is aligned with the data in the repository using Git push requests.
GitOps Principles
- System definitions are described as source code.
System configurations are treated as code, allowing them to be stored and automatically versioned in a Git repository, which serves as the single source of truth. This approach makes it easy to rollout and rollback changes in systems.
- The desired state and configurations of systems are defined and versioned in Git.
By storing and versioning the desired state of systems in Git, we gain the ability to easily rollout and rollback changes in systems and applications. We can also leverage Git mechanisms for security to control code ownership and verify its authenticity.
- Changes to configurations can be automatically applied through pull requests.
Using Git pull requests, we can easily manage how changes are applied to configurations in the repository. For example, they can be submitted for review to other team members or run through CI tests.
And there’s no need to hand out admin privileges left and right. To commit changes to the configuration, users only need the appropriate permissions in the Git repository where these configurations are stored.
- Eliminating uncontrolled configuration drift
When the desired state of the system is stored in a Git repository, all we need to do is find software that monitors whether the current state of the system corresponds to its desired state. If not, this software should — depending on the settings — either resolve the discrepancy automatically or notify us of the configuration drift.
GitOps Models for OpenShift
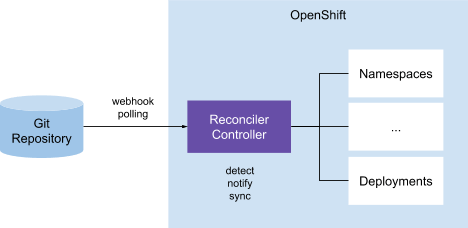
On-Cluster Resource Reconciler
According to this model, there is a controller in the cluster that is responsible for comparing Kubernetes resources (YAML files) in the Git repository with the actual resources in the cluster. When discrepancies are identified, the controller sends out notifications and may take action to resolve the inconsistencies. This GitOps model is used in Anthos Config Management and Weaveworks Flux.
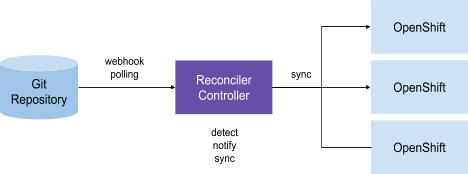
External Resource Reconciler (Push)
This model can be viewed as a variation of the previous one, where we have one or more controllers responsible for synchronizing resources between the pairs "Git repository – Kubernetes cluster". The difference here is that not every managed cluster necessarily needs its own separate controller. The pairs "Git – k8s cluster" are often defined as CRD descriptions (custom resource definitions), in which it is possible to describe how the controller should perform synchronization. Within this model, the controllers compare the Git repository specified in the CRD with the Kubernetes cluster resources also defined in the CRD and take appropriate actions based on the comparison results. In particular, this GitOps model is used in ArgoCD.
GitOps on the OpenShift platform
Managing multi-cluster Kubernetes infrastructure
With the spread of Kubernetes and the growing popularity of multi-cloud strategies and edge computing, the average number of OpenShift clusters per customer is also increasing.
For example, when using edge computing, a single client's clusters can be deployed in hundreds or even thousands. As a result, they are forced to manage several independent or coordinated OpenShift clusters in the public cloud and on-premise.
At the same time, they face a multitude of problems, including:
- Ensuring that the clusters are in identical states (configs, monitoring, storage, etc.)
- Re-creating (or restoring) clusters to a known state.
- Creating new clusters from a known state.
- Applying changes to multiple OpenShift clusters.
- Rolling back changes on multiple OpenShift clusters.
- Linking templated configurations with various environments.
Application configurations
Throughout their lifecycle, applications often go through a chain of clusters (dev, stage, etc.) before reaching the production cluster. Moreover, due to availability and scalability requirements, clients often deploy applications across several on-premise clusters or in multiple regions of a public cloud platform.
In doing so, the following tasks must be addressed:
- Ensuring the movement of applications (binaries, configs, etc.) between clusters (dev, stage, etc.).
- Applying changes in applications (binaries, configs, etc.) across multiple OpenShift clusters.
- Rolling back application changes to a previous known state.
OpenShift GitOps use cases
1. Applying changes from a Git repository
A cluster administrator can store OpenShift cluster configurations in a Git repository and automatically apply them to effortlessly create new clusters and bring them to a state identical to the known state stored in the Git repository.
2. Synchronization with Secret Manager
The administrator will also benefit from the ability to synchronize OpenShift secret objects with corresponding software like Vault, to manage them with specialized tools created for this purpose.
3. Configuration drift monitoring
The admin would be all for OpenShift GitOps self-identifying and alerting discrepancies between actual configurations and those defined in the repository, to allow for prompt reactions to drift.
4. Configuration Drift Notifications
These are useful when an admin wants to promptly learn about configuration drift occurrences to quickly take appropriate actions themselves.
5. Manual Configuration Synchronization in Case of Drift
Allows the admin to synchronize the OpenShift cluster with the Git repository in case of configuration drift, quickly restoring the cluster to its last known state.
6. Automatic Configuration Synchronization in Case of Drift
The admin can also set up the OpenShift cluster for automatic synchronization with the repository upon detecting drift, ensuring that the cluster's configuration always matches the Git settings.
7. Multiple Clusters – One Repository
The admin can store configurations for multiple different OpenShift clusters in one Git repository and selectively apply them as needed.
8. Cluster Configuration Hierarchy (Inheritance)
The admin can define a hierarchy of cluster configurations in the repository (stage, prod, app portfolio, etc. with inheritance). In other words, they can determine how configurations should be applied – to one or multiple clusters.
For example, if the admin sets up a hierarchy in the Git repository as 'Production Clusters (prod) → System X Clusters → Production Clusters of System X', the following configs will be merged and applied to the production clusters of System X:
- Configs common to all production clusters.
- Configs for the System X cluster.
- Configs for the production cluster of System X.
9. Templates and Configuration Overrides
The admin can override the set of inherited configs and their values, for instance, to fine-tune the configuration for specific clusters to which they will be applied.
10. Selective Includes and Excludes for Configurations, Application Configurations
The admin can specify conditions for applying or not applying certain configurations to clusters with specific characteristics.
11. Template Support
Developers will find it useful to choose how application resources will be defined (Helm Chart, pure Kubernetes yaml, etc.) to use the most suitable format for each specific application.
GitOps Tools on the OpenShift Platform
ArgoCD
ArgoCD implements the External Resource Reconcile model and offers a centralized UI for orchestrating the relationships between clusters and Git repositories in a 'one-to-many' scheme. A drawback of this program is the inability to manage applications when ArgoCD is not operational.
Flux
Flux implements the On-Cluster Resource Reconcile model, and consequently, there is no centralized management of the definitions repository, which is a weak point. On the other hand, due to the lack of centralization, the ability to manage applications is preserved even when one cluster fails.
Installing ArgoCD on OpenShift
ArgoCD offers a great command-line interface and a web console, so we will not cover Flux and other alternatives here.
To deploy ArgoCD on the OpenShift 4 platform, follow these steps as a cluster administrator:
Deploying ArgoCD components on the OpenShift platform
# Create a new namespace for ArgoCD components
oc create namespace argocd
# Apply the ArgoCD Install Manifest
oc -n argocd apply -f https://raw.githubusercontent.com/argoproj/argo-cd/v1.2.2/manifests/install.yaml
# Get the ArgoCD Server password
ARGOCD_SERVER_PASSWORD=$(oc -n argocd get pod -l "app.kubernetes.io/name=argocd-server" -o jsonpath='{.items[*].metadata.name}')
Tweaking the ArgoCD Server to be recognized by OpenShift Route
# Patch ArgoCD Server so no TLS is configured on the server (--insecure)
PATCH='{"spec":{"template":{"spec":{"$setElementOrder/containers":[{"name":"argocd-server"}],"containers":[{"command":["argocd-server","--insecure","--staticassets","/shared/app"],"name":"argocd-server"}]}}}}'
oc -n argocd patch deployment argocd-server -p $PATCH
# Expose the ArgoCD Server using an Edge OpenShift Route so TLS is used for incoming connections
oc -n argocd create route edge argocd-server --service=argocd-server --port=http --insecure-policy=Redirect
Deploying the ArgoCD CLI Tool
# Download the argocd binary, place it under /usr/local/bin and give it execution permissions
curl -L https://github.com/argoproj/argo-cd/releases/download/v1.2.2/argocd-linux-amd64 -o /usr/local/bin/argocd
chmod +x /usr/local/bin/argocd
Changing the admin password for the ArgoCD Server
# Get ArgoCD Server Route Hostname
ARGOCD_ROUTE=$(oc -n argocd get route argocd-server -o jsonpath='{.spec.host}')
# Login with the current admin password
argocd --insecure --grpc-web login ${ARGOCD_ROUTE}:443 --username admin --password ${ARGOCD_SERVER_PASSWORD}
# Update admin's password
argocd --insecure --grpc-web --server ${ARGOCD_ROUTE}:443 account update-password --current-password ${ARGOCD_SERVER_PASSWORD} --new-password
After completing these steps, you can interact with the ArgoCD Server through the ArgoCD WebUI or the ArgoCD CLI tool.
GitOps – it’s never too late
‘The train has left’ – this phrase is often used when an opportunity to do something has been missed. In the case of OpenShift, the eagerness to immediately use this new cool platform often creates such a situation with managing and maintaining routes, deployments, and other OpenShift objects. But is the chance always definitively gone?
Continuing the series of articles on , today we will show how to transform a manually created application and its resources into a process managed entirely by GitOps tools. To begin, we will first deploy the httpd application manually. The screenshot below shows how we create a namespace, deployment, and service, and then expose this service to create a route.
oc create -f https://raw.githubusercontent.com/openshift/federation-dev/master/labs/lab-4-assets/namespace.yaml
oc create -f https://raw.githubusercontent.com/openshift/federation-dev/master/labs/lab-4-assets/deployment.yaml
oc create -f https://raw.githubusercontent.com/openshift/federation-dev/master/labs/lab-4-assets/service.yaml
oc expose svc/httpd -n simple-app
So, we have a manually created application. Now, it needs to be transitioned under GitOps management without losing availability. In short, this is done as follows:
- Create a Git repository for the code.
- We export our current objects and load them into the Git repository.
- We select and deploy the GitOps toolkit.
- We add our repository to this toolkit.
- We define the application in our GitOps toolkit.
- We perform a trial run of the application using the GitOps toolkit.
- We synchronize the objects using the GitOps toolkit.
- We enable pruning and auto-synchronization of the objects.
As mentioned earlier, in GitOps there is one and only one source of truth for all objects in the Kubernetes cluster(s) — the Git repository. We assume that you already have a Git repository in your organization. It may be public or private, but it must be accessible to the Kubernetes clusters. This can be the same repository used for application code, or a separate repository created specifically for deployments. It is recommended to have strict permissions in the repository, as it will store secret objects, routes, and other sensitive security-related items.
In our example, we will create a new public repository on GitHub. You can name it anything you like; we will use the name blogpost.
If the object YAML files were not stored locally or in Git, you will need to use the oc or kubectl binaries. In the screenshot below, we request the YAML for our namespace, deployment, service, and route. Before this, we cloned the newly created repository and navigated into it using the cd command.
oc get namespace simple-app -o yaml --export > namespace.yaml
oc get deployment httpd -o yaml -n simple-app --export > deployment.yaml
oc get service httpd -o yaml -n simple-app --export > service.yaml
oc get route httpd -o yaml -n simple-app --export > route.yaml
Now let's edit the deployment.yaml file to remove the field that Argo CD cannot synchronize.
sed -i '/sgeneration: .*}/d' deployment.yamlAdditionally, we need to modify the route. First, we will set a multi-line variable, then replace ingress: null with the contents of this variable.
export ROUTE="  ingress:
    - conditions:
        - status: 'True'
          type: Admitted"

sed -i "s/  ingress: null/$ROUTE/g" route.yaml
So, we've dealt with the files; now we need to save them in the Git repository. After this, this repository becomes the one and only source of truth, and any manual changes to the objects should be strictly prohibited.
git commit -am 'initial commit of objects'
git push origin master
Next, we assume that ArgoCD is already deployed (for instructions, see the previous) ). Therefore, let's add the repository we created in Argo CD, which contains the application code from our example. Just make sure to specify the exact repository you created earlier.
argocd repo add https://github.com/cooktheryan/blogpostNow we create an application. The application specifies values so that the GitOps toolkit understands which repository and paths to use, which OpenShift is needed to manage the objects, and which specific branch of the repository is required, as well as whether resource auto-sync should occur.
argocd app create --project default
--name simple-app --repo https://github.com/cooktheryan/blogpost.git
--path . --dest-server https://kubernetes.default.svc
--dest-namespace simple-app --revision master --sync-policy none
Once the application is defined in Argo CD, this toolkit begins checking the already deployed objects against the definitions in the repository. In our example, auto-sync and cleanup are disabled, so the elements remain unchanged for now. Note that in the Argo CD interface, our application will have the status 'Out of Sync' because there is no label set by ArgoCD.
This is why, when we initiate synchronization a bit later, redeployment of objects will not take place.
Now let's perform a dry run to ensure there are no errors in our files.
argocd app sync simple-app --dry-runIf there are no errors, we can proceed to synchronization.
argocd app sync simple-appAfter executing the argument 'argocd get' on our application, we should see that the application's status has changed to Healthy or Synced. This will mean that all resources in the Git repository now match those that are already deployed.
argocd app get simple-app
Name:               simple-app
Project:            default
Server:             https://kubernetes.default.svc
Namespace:          simple-app
URL:                https://argocd-server-route-argocd.apps.example.com/applications/simple-app
Repo:               https://github.com/cooktheryan/blogpost.git
Target:             master
Path:               .
Sync Policy:
Sync Status:        Synced to master (60e1678)
Health Status:      Healthy
...
Now it is time to enable auto-sync and cleanup to ensure that nothing is created manually and that every time an object is created or updated in the repository, a deployment will occur.
argocd app set simple-app --sync-policy automated --auto-prune We have successfully transitioned an application to GitOps management that initially did not use GitOps at all.
Source: habr.com
