

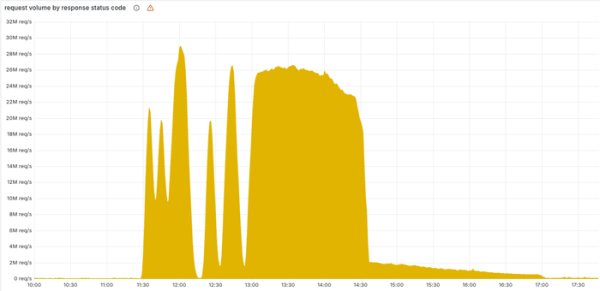
Cloudflare has published an analysis of one of the largest incidents in its infrastructure, which caused a significant part of the content delivery network to be non-operational for over 3 hours yesterday. The failure occurred after a change in the database structure hosted in ClickHouse, after which the configuration file for the bot mitigation system doubled in size. Duplicate tables were created in the database, while the SQL query to generate the file simply retrieved all data from all tables by key, without filtering out duplicates. SELECT name, type FROM system.columns WHERE table = 'http_requests_features' order by name;
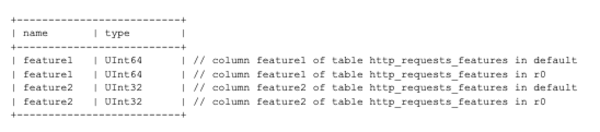
The generated file was distributed across all nodes of the cluster processing incoming requests. In the handler using this file to check for bot requests, the specified parameters in the file were stored in memory, and to prevent excessive memory usage, the code had a limit on the maximum allowable file size. Under normal conditions, the actual file size was significantly below the set limit, but after the table duplication, it exceeded the limit.
The problem was that instead of correctly handling the limit exceeding and continuing to use the previous version of the file while informing the monitoring system of the incident, the handler triggered an emergency termination, which blocked further traffic routing. The error was caused by the use of the unwrap() method with the Result type in Rust code.
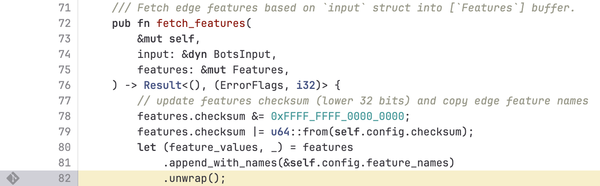
When the Result value is in the 'Ok' state, the unwrap() method returns the object associated with that state, but if the result is not successful, the call leads to a crash (the panic! macro is invoked). Typically, unwrap() is used during debugging or while writing test code and is not recommended for use in production projects.
Source: opennet.ru
