

Märkus tõlkes: see translation of the public postmortem from the engineering blog of the company . It describes the issue with conntrack in the Kubernetes cluster that led to partial downtime of some production services.
This article may be useful for those who want to learn a bit more about postmortems or prevent some potential DNS issues in the future.
This is not DNS
It cannot be that this is DNS
This was DNS
A bit about postmortems and processes at Preply
The postmortem describes a failure or any event in production. A postmortem includes a timeline of events, user impact description, root cause, actions, and lessons learned.
At weekly meetings with pizza, in the circle of the technical team, we share various information. One of the most important parts of such meetings are postmortems, which are usually accompanied by a slideshow presentation and a more in-depth analysis of the incident that occurred. Although we do not 'clap' after postmortems, we try to cultivate a 'blameless' culture (). We believe that writing and presenting postmortems can help us (and not only us) in preventing similar incidents in the future, which is why we share them.
Individuals involved in the incident should feel that they can talk about it in detail without fear of punishment or retribution. No blame! Writing a postmortem is not punishment, but a learning opportunity for the entire company.
DNS issues in Kubernetes. Postmortem
Kuupäev: 28.02.2020
Autorid: Amet U., Andrey S., Igor K., Alexey P.
Olek: Completed
Lühidalt: Partial DNS unavailability (26 min) for some services in the Kubernetes cluster
Impact: 15,000 events lost for services A, B, and C
Root Cause: Kube-proxy was unable to correctly remove the old entry from the conntrack table, so some services were still trying to connect to non-existent pods.
E0228 20:13:53.795782 1 proxier.go:610] Failed to delete kube-system/kube-dns:dns endpoint connections, error: error deleting conntrack entries for UDP peer {100.64.0.10, 100.110.33.231}, error: conntrack command returned: ...Trigger: Due to low load inside the Kubernetes cluster, the CoreDNS autoscaler reduced the number of pods in the deployment from three to two.
Lahendus: Järjekordne rakenduse juurutamine tõi kaasa uute sõlmede loomise, CoreDNS-autoscaler lisas klastrite teenindamiseks rohkem pude, mis põhjustas conntrack tabeli ülekirjutamise.
Avastamine: Prometheuse jälgimine tuvastas suure hulga 5xx vigu teenustes A, B ja C ning algatas väljakutse valveinseneridele.
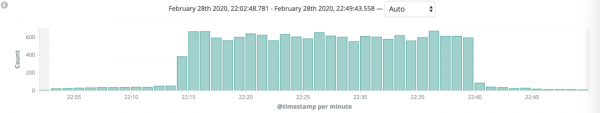
5xx vead Kibanas
Tegevused
Tegevus
Tüüp
Vastutav
Ülesanne
Keela CoreDNS-i automaatne skaleerimine
ennetama.
Amet U.
DEVOPS-695
Paigalda vahemälu DNS-server
vähendama.
Max V.
DEVOPS-665
Seadista conntrack jälgimine
ennetama.
Amet U.
DEVOPS-674
Õpitud õppetunnid
Mis läks hästi:
- Jälgimine toimis sujuvalt. Reaktsioon oli kiire ja organiseeritud.
- Me ei kohanud sõlmedes mingeid piiranguid.
Mis polnud õige:
- Siiani on reaalne põhjus teadmata, tundub olevat conntrackis.
- Kõik tegevused parandavad vaid tagajärgi, mitte põhjuslikku tegurit (viga).
- Me teadsime, et varem või hiljem võivad meil tekkida DNS-iga seotud probleemid, kuid ei prioriseerinud ülesandeid.
Kus meil vedas:
- Järjekordne juurutamine käivitas CoreDNS-autoscale'i, mis ülekirjutas conntrack tabeli.
- See viga puudutas ainult osa teenustest.
Kronoloogia (EET)
Aeg
Tegevus
22:13
CoreDNS-autoscaler vähendas pude arvu kolmest kaheni.
22:18
Valveinsenerid hakkasid saama väljakutseid jälgimissüsteemilt.
22:21
Valveinsenerid hakkasid uurima vigade põhjust.
22:39
Valveinsenerid alustasid ühte hiljutist teenust eelnevale versioonile tagasiviimist.
22:40
5xx vead lõpetasid ilmumise, olukord stabiliseerus.
- Aeg avastamiseni: 4 min
- Aeg tegevuste tegemiseks: 21 min
- Aeg parandamiseks: 1 min
Lisainformatsioon
- [INFO] 10.1.28.1:52495 - 2606 "A IN mrkaran.hello.svc.cluster.local. udp 49 false 512" NXDOMAIN qr,aa,rd 142 0.000524939s [INFO] 10.1.28.1:59287 - 57522 "A IN mrkaran.svc.cluster.local. udp 43 false 512" NXDOMAIN qr,aa,rd 136 0.000368277s [INFO] 10.1.28.1:53086 - 4863 "A IN mrkaran.cluster.local. udp 39 false 512" NXDOMAIN qr,aa,rd 132 0.000355344s [INFO] 10.1.28.1:56863 - 41678 "A IN mrkaran. udp 25 false 512" NXDOMAIN qr,rd,ra 100 0.034629206s
I0228 20:13:53.507780 1 event.go:221] Üritus(v1.ObjectReference{Tüüp:"Deployment", Nimi:"kube-system", Nimi:"coredns", UID:"2493eb55-3dc0-11ea-b3a2-02bb48f8c230", APIVersioon:"apps/v1", Ressursiversioon:"132690686", Valdkonna tee:""}): tüüp: 'Normaalne' põhjus: 'ReplicaSeti skaleerimine' Vähendatud replica set coredns-6cbb6646c9 kaheks. - Lingid Kibana (väljalõikega), Grafana (väljalõikega)
Protsessori kasutamise minimeerimiseks kasutab Linuxi südamik sarnast asja nagu conntrack. Lühidalt öeldes on see utiliit, mis sisaldab NAT-kirjete nimekirja, mis hoitakse spetsiaalses tabelis. Kui järgmine paket tuleb samast pude koos sama podiga nagu varem, siis lõpp- IP-aadressi ei arvutata uuesti, vaid võetakse conntrack tabelist.
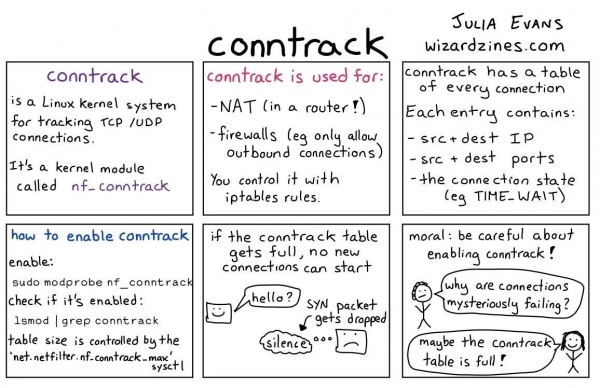
Kuidas conntrack töötab
Summary
See oli näide meie postmortem'ist koos kasulike linkidega. Konkreetselt selles artiklis jagame teavet, mis võib teistele ettevõtetele kasulik olla. Just seetõttu ei karda me vigu teha ja just seetõttu tegime ühe oma postmortem'itest avalikuks. Siin on veel mõned huvitavad avalikud postmortem'id:
- GitLab:
- Dropbox:
- Spotify:
- Palju teisi siit ja hoidla
- Samuti avaliku postmortemi SRE raamatuga
Allikas: habr.com
