

Introduzione o come è nata l'idea della suddivisione
L'inizio della storia è qui: Dopo che quasi tutte le risorse per l'ottimizzazione della query erano state esaurite, si è posto il problema: e adesso cosa? È così che è nata l'idea della suddivisione.
Una digressione lirica:
Proprio 'a quel tempo', perché . Grazie e Habr!
Quindi, come si può rendere il cliente un po' felice e allo stesso tempo migliorare le proprie competenze?
Se dobbiamo semplificare al massimo, ci sono solo due modi significativi per migliorare le prestazioni del database:
1) Percorso estensivo — aumentiamo le risorse, cambiamo la configurazione;
2) Percorso intensivo — ottimizzazione delle query
Poiché, ripeto, a quel tempo non era chiaro cosa potessimo ancora cambiare nella query per velocizzarla, è stata scelta la via — modifiche al design delle tabelle.
Quindi — sorge la domanda principale: cosa e come cambieremo?
Condizioni iniziali
Prima di tutto, c'è un ERD come questo (mostrato in modo semplificato):
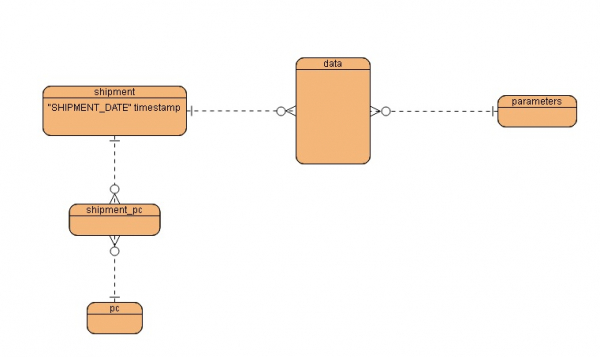
Caratteristiche principali:
- relazioni 'molti a molti'
- la tabella ha già una potenziale chiave di suddivisione
Query di origine:
SELECT
            p."PARAMETER_ID" as  parameter_id,
            pc."PC_NAME" AS pc_name,
            pc."CUSTOMER_PARTNUMBER" AS customer_partnumber,
            w."LASERMARK" AS lasermark,
            w."LOTID" AS lotid,
            w."REPORTED_VALUE" AS reported_value,
            w."LOWER_SPEC_LIMIT" AS lower_spec_limit,
            w."UPPER_SPEC_LIMIT" AS upper_spec_limit,
            p."TYPE_CALCUL" AS type_calcul,
            s."SHIPMENT_NAME" AS shipment_name,
            s."SHIPMENT_DATE" AS shipment_date,
            extract(year from s."SHIPMENT_DATE") AS year,
            extract(month from s."SHIPMENT_DATE") as month,
            s."REPORT_NAME" AS report_name,
            p."SPARAM_NAME" AS SPARAM_name,
            p."CUSTOMERPARAM_NAME" AS customerparam_name
        FROM data w INNER JOIN shipment s ON s."SHIPMENT_ID" = w."SHIPMENT_ID"
             INNER JOIN parameters p ON p."PARAMETER_ID" = w."PARAMETER_ID"
             INNER JOIN shipment_pc sp ON s."SHIPMENT_ID" = sp."SHIPMENT_ID"
             INNER JOIN pc pc ON pc."PC_ID" = sp."PC_ID"
             INNER JOIN ( SELECT w2."LASERMARK" , MAX(s2."SHIPMENT_DATE") AS "SHIPMENT_DATE"
                          FROM shipment s2 INNER JOIN data w2 ON s2."SHIPMENT_ID" = w2."SHIPMENT_ID"
                          GROUP BY w2."LASERMARK"
                         ) md ON md."SHIPMENT_DATE" = s."SHIPMENT_DATE" AND md."LASERMARK" = w."LASERMARK"
        WHERE
             s."SHIPMENT_DATE" >= '2018-07-01' AND s."SHIPMENT_DATE" <= '2018-09-30';
Risultati dell'esecuzione su un database di test:
Costo : 502 997.55
Tempo di esecuzione: 505 secondi.
Cosa vediamo? Una query normale, per intervallo di tempo.
Facciamo una semplice ipotesi logica: se c'è un campione di intervallo temporale, ci aiuterà? Giusto — la partizionamento.
Cosa partizionare?
A prima vista, la scelta è ovvia — la partizione dichiarativa della tabella «shipment» in base alla chiave «SHIPMENT_DATE» (anticipando molto — alla fine in produzione è andata un po' diversamente).
Come partizionare?
Anche questa domanda non è troppo difficile. Fortunatamente, in PostgreSQL 10, ora c'è un meccanismo di partizionamento umano.
Ecco:
- Salviamo il dump della tabella originale — pg_dump source_table
- Eliminiamo la tabella originale — drop table source_table
- Creiamo la tabella principale con partizionamento per intervallo — create table source_table
- Creiamo le partizioni — create table source_table, create index
- Importiamo il dump creato nel passo 1 — pg_restore
Script per il partizionamento
Per semplicità e comodità, i passi 2, 3, 4 sono stati uniti in uno script.
Ecco:
Salviamo il dump della tabella originale
pg_dump postgres --file=\/dump\/shipment.dmp --format=c --table=shipment --verbose > \/dump\/shipment.log 2>&1Eliminiamo la tabella originale + Creiamo la tabella principale con partizionamento per intervallo + Creiamo le partizioni
--create_partition_shipment.sql
do language plpgsql $$
declare
rec_shipment_date RECORD ;
partition_name varchar;
index_name varchar;
current_year varchar ;
current_month varchar ;
begin_year varchar ;
begin_month varchar ;
next_year varchar ;
next_month varchar ;
first_flag boolean ;
i integer ;
begin
  RAISE NOTICE 'CREA UNA TABELLA TEMPORANEA PER SHIPMENT_DATE';
  CREATE TEMP TABLE tmp_shipment_date as select distinct "SHIPMENT_DATE" from shipment order by "SHIPMENT_DATE" ;

  RAISE NOTICE 'ELIMINA LA TABELLA shipment';
  drop table shipment cascade ;

  CREATE TABLE public.shipment
  (
    "SHIPMENT_ID" integer NOT NULL DEFAULT nextval('shipment_shipment_id_seq'::regclass),
    "SHIPMENT_NAME" character varying(30) COLLATE pg_catalog."default",
    "SHIPMENT_DATE" timestamp without time zone,
    "REPORT_NAME" character varying(40) COLLATE pg_catalog."default"
  )
  PARTITION BY RANGE ("SHIPMENT_DATE")
  WITH (
      OIDS = FALSE
  )
  TABLESPACE pg_default;

  RAISE NOTICE 'CREA PARTIZIONI PER LA TABELLA shipment';

  current_year:='0';
  current_month:='0';

  begin_year := '0' ;
  begin_month := '0'  ;
  next_year := '0' ;
  next_month := '0'  ;

  FOR rec_shipment_date IN SELECT * FROM tmp_shipment_date LOOP

      RAISE NOTICE 'SHIPMENT_DATE=%',rec_shipment_date."SHIPMENT_DATE";

      current_year := date_part('year' ,rec_shipment_date."SHIPMENT_DATE");
      current_month := date_part('month' ,rec_shipment_date."SHIPMENT_DATE") ;

      IF to_number(current_month,'99') = to_date( begin_year||'.'||begin_month, 'YYYY.MM') AND
         to_date( current_year||'.'||current_month, 'YYYY.MM') < to_date( next_year||'.'||next_month, 'YYYY.MM') AND
         NOT first_flag
      THEN
         CONTINUE ;
      ELSE
       --NUOVI confini solo per la seconda volta e oltre
       begin_year := current_year ;
       begin_month := current_month ;

        IF current_month = '12' THEN
          next_year := date_part('year' ,rec_shipment_date."SHIPMENT_DATE" + interval '1 year') ;
        ELSE
          next_year := current_year ;
        END IF;

       next_month := date_part('month' ,rec_shipment_date."SHIPMENT_DATE" + interval '1 month') ;

      END IF;

      partition_name := 'shipment_shipment_date_'||begin_year||'-'||begin_month||'-01-'|| next_year||'-'||next_month||'-01'  ;

     EXECUTE format('CREATE TABLE ' || quote_ident(partition_name) || ' PARTITION OF shipment FOR VALUES FROM ( %L ) TO ( %L )  ' , current_year||'-'||current_month||'-01' , next_year||'-'||next_month||'-01'  ) ;

      index_name := partition_name||'_shipment_id_idx';
      RAISE NOTICE 'NOME INDICE =%',index_name;
      EXECUTE format('CREATE INDEX ' || quote_ident(index_name) || ' ON '|| quote_ident(partition_name) ||' USING btree ("SHIPMENT_ID") TABLESPACE pg_default ' ) ;

      --Elimina il flag prima volta
      first_flag := false ;

  END LOOP;

end
$$;
Importiamo il dump
pg_restore -d postgres --data-only --format=c --table=shipment --verbose shipment.dmp > /tmp/data_dump/shipment_restore.log 2>&1Controlliamo i risultati della partizionatura
Cosa abbiamo ottenuto in risultato? Il testo completo del piano di esecuzione è lungo e noioso, quindi è possibile limitarsi ai numeri finali.
Era
Costo: 502 997.55
Tempo di esecuzione: 505 secondi.
Diventato
Costo: 77 872.36
Tempo di esecuzione: 79 secondi.
Un risultato piuttosto buono. Abbiamo ridotto i costi e il tempo di esecuzione. Pertanto, l'uso della partizionamento dà l'effetto atteso e, in generale, nessuna sorpresa.
Compiacere il cliente
I risultati dei test sono stati presentati al cliente per la revisione. E dopo la consultazione gli è stato dato un verdetto piuttosto inaspettato: «Ottimo, partiziona la tabella 'data'».
Sì, ma abbiamo esaminato una tabella completamente diversa, 'shipment', la tabella 'data' non ha il campo 'SHIPMENT_DATE'.
Nessun problema, aggiungete, cambiate. L'importante è che il cliente sia soddisfatto del risultato finale, i dettagli dell'implementazione non sono così importanti.
Partizioniamo la tabella principale 'data'
In realtà non ci sono state particolari difficoltà. Anche se, ovviamente, l'algoritmo di partizionamento è cambiato un po'.
Aggiungiamo la colonna 'SHIPMENT_DATA' nella tabella 'data'
psql -h host -U database -d user
=> ALTER TABLE data ADD COLUMN "SHIPMENT_DATE" timestamp without time zone ;
Compiliamo i valori della colonna 'SHIPMENT_DATA' nella tabella 'data' con i valori della colonna omonima della tabella 'shipment'
-----------------------------
--update_data.sql
--aggiornamento per la tabella "data" alterata con i valori di "shipment_data" dalla tabella "shipment"
--versione 1.0
do language plpgsql $$
dichiarare
rec_shipment_data RECORD ;
shipment_date timestamp without time zone ;
row_count integer ;
total_rows integer ;
inizio

  select count(*) into total_rows from shipment ;
  RAISE NOTICE 'Totale %',total_rows;
  row_count:= 0 ;

  FOR rec_shipment_data IN SELECT * FROM shipment LOOP

   update data set "SHIPMENT_DATE" = rec_shipment_data."SHIPMENT_DATE" where "SHIPMENT_ID" = rec_shipment_data."SHIPMENT_ID";

   row_count:=  row_count +1 ;
   RAISE NOTICE 'conteggio righe = % , da %',row_count,total_rows;
  END LOOP;

fine
$$;
Salviamo il dump della tabella 'data'
pg_dump postgres --file=/dump/data.dmp --format=c --table=data --verbose > /dump/data.log 2>&1Ricreiamo la tabella partizionata 'data'
--create_partition_data.sql
--crea partizioni per la tabella "wafer data" per intervallo della colonna "shipment_data" con una durata di un mese
--versione 1.0
do language plpgsql $$
declare
rec_shipment_date RECORD ;
partition_name varchar;
index_name varchar;
current_year varchar ;
current_month varchar ;
begin_year varchar ;
begin_month varchar ;
next_year varchar ;
next_month varchar ;
first_flag boolean ;
i integer ;

begin

  RAISE NOTICE 'CREA TABELLA TEMPORANEA PER SHIPMENT_DATE';
  CREATE TEMP TABLE tmp_shipment_date as select distinct "SHIPMENT_DATE" from shipment order by "SHIPMENT_DATE" ;


  RAISE NOTICE 'DROP TABLE data';
  drop table data cascade ;


  RAISE NOTICE 'CREA TABELLA PARTIZIONATA data';

  CREATE TABLE public.data
  (
    "RUN_ID" integer,
    "LASERMARK" character varying(20) COLLATE pg_catalog."default" NOT NULL,
    "LOTID" character varying(80) COLLATE pg_catalog."default",
    "SHIPMENT_ID" integer NOT NULL,
    "PARAMETER_ID" integer NOT NULL,
    "INTERNAL_VALUE" character varying(75) COLLATE pg_catalog."default",
    "REPORTED_VALUE" character varying(75) COLLATE pg_catalog."default",
    "LOWER_SPEC_LIMIT" numeric,
    "UPPER_SPEC_LIMIT" numeric ,
    "SHIPMENT_DATE" timestamp without time zone
  )
  PARTITION BY RANGE ("SHIPMENT_DATE")
  WITH (
    OIDS = FALSE
  )
  TABLESPACE pg_default ;


  RAISE NOTICE 'CREA PARTIZIONI PER LA TABELLA data';

  current_year:='0';
  current_month:='0';

  begin_year := '0' ;
  begin_month := '0'  ;
  next_year := '0' ;
  next_month := '0'  ;
  i := 1;

  FOR rec_shipment_date IN SELECT * FROM tmp_shipment_date LOOP

      RAISE NOTICE 'SHIPMENT_DATE=%',rec_shipment_date."SHIPMENT_DATE";

      current_year := date_part('year' ,rec_shipment_date."SHIPMENT_DATE");
      current_month := date_part('month' ,rec_shipment_date."SHIPMENT_DATE") ;

      --Inizializza i confini
      IF   begin_year = '0' THEN
       RAISE NOTICE '***Inizializza i confini';
       first_flag := true ; --flag prima volta
       begin_year := current_year ;
       begin_month := current_month ;

        IF current_month = '12' THEN
          next_year := date_part('year' ,rec_shipment_date."SHIPMENT_DATE" + interval '1 year') ;
        ELSE
          next_year := current_year ;
        END IF;

       next_month := date_part('month' ,rec_shipment_date."SHIPMENT_DATE" + interval '1 month') ;

      END IF;

--      RAISE NOTICE 'current_year=% , current_month=% ',current_year,current_month;
--      RAISE NOTICE 'begin_year=% , begin_month=% ',begin_year,begin_month;
--      RAISE NOTICE 'next_year=% , next_month=% ',next_year,next_month;

      -- Controlla la data corrente nei confini NON per la prima volta

      RAISE NOTICE 'Dati correnti = %',to_char( to_date( current_year||'.'||current_month, 'YYYY.MM'), 'YYYY.MM');
      RAISE NOTICE 'Dati di inizio = %',to_char( to_date( begin_year||'.'||begin_month, 'YYYY.MM'), 'YYYY.MM');
      RAISE NOTICE 'Dati successivi = %',to_char( to_date( next_year||'.'||next_month, 'YYYY.MM'), 'YYYY.MM');

      IF to_date( current_year||'.'||current_month, 'YYYY.MM') >= to_date( begin_year||'.'||begin_month, 'YYYY.MM') AND
         to_date( current_year||'.'||current_month, 'YYYY.MM') < to_date( next_year||'.'||next_month, 'YYYY.MM') AND
         NOT first_flag
      THEN
         RAISE NOTICE '***CONTINUA';
         CONTINUE ;
      ELSE
       --NUOVI confini solo per la seconda volta e oltre
       RAISE NOTICE '***NUOVI CONFINI';
       begin_year := current_year ;
       begin_month := current_month ;

        IF current_month = '12' THEN
          next_year := date_part('year' ,rec_shipment_date."SHIPMENT_DATE" + interval '1 year') ;
        ELSE
          next_year := current_year ;
        END IF;

       next_month := date_part('month' ,rec_shipment_date."SHIPMENT_DATE" + interval '1 month') ;


      END IF;

      IF to_number(current_month,'99') < 10 THEN
        current_month := '0'||current_month ;
      END IF ;

      IF to_number(begin_month,'99') < 10 THEN
        begin_month := '0'||begin_month ;
      END IF ;

      IF to_number(next_month,'99') < 10 THEN
        next_month := '0'||next_month ;
      END IF ;

      RAISE NOTICE 'current_year=% , current_month=% ',current_year,current_month;
      RAISE NOTICE 'begin_year=% , begin_month=% ',begin_year,begin_month;
      RAISE NOTICE 'next_year=% , next_month=% ',next_year,next_month;

      partition_name := 'data_'||begin_year||begin_month||'01_'||next_year||next_month||'01'  ;

      RAISE NOTICE 'NUMERO PARTIZIONE % , NOME TABELLA =%',i , partition_name;

      EXECUTE format('CREA TABELLA ' || quote_ident(partition_name) || ' PARTIZIONE di data PER VALORI DA ( %L ) A ( %L )  ' , begin_year||'-'||begin_month||'-01' , next_year||'-'||next_month||'-01'  ) ;

      index_name := partition_name||'_shipment_id_parameter_id_idx';
      RAISE NOTICE 'NOME INDICE =%',index_name;
      EXECUTE format('CREA INDICE ' || quote_ident(index_name) || ' ON '|| quote_ident(partition_name) ||' USING btree ("SHIPMENT_ID", "PARAMETER_ID") TABLESPACE pg_default ' ) ;

      index_name := partition_name||'_lasermark_idx';
      RAISE NOTICE 'NOME INDICE =%',index_name;
      EXECUTE format('CREA INDICE ' || quote_ident(index_name) || ' ON '|| quote_ident(partition_name) ||' USING btree ("LASERMARK" COLLATE pg_catalog."default") TABLESPACE pg_default ' ) ;

      index_name := partition_name||'_shipment_id_idx';
      RAISE NOTICE 'NOME INDICE =%',index_name;
      EXECUTE format('CREA INDICE ' || quote_ident(index_name) || ' ON '|| quote_ident(partition_name) ||' USING btree ("SHIPMENT_ID") TABLESPACE pg_default ' ) ;

      index_name := partition_name||'_parameter_id_idx';
      RAISE NOTICE 'NOME INDICE =%',index_name;
      EXECUTE format('CREA INDICE ' || quote_ident(index_name) || ' ON '|| quote_ident(partition_name) ||' USING btree ("PARAMETER_ID") TABLESPACE pg_default ' ) ;

      index_name := partition_name||'_shipment_date_idx';
      RAISE NOTICE 'NOME INDICE =%',index_name;
      EXECUTE format('CREA INDICE ' || quote_ident(index_name) || ' ON '|| quote_ident(partition_name) ||' USING btree ("SHIPMENT_DATE") TABLESPACE pg_default ' ) ;

      --Rimuovi flag prima volta
      first_flag := false ;

  END LOOP;
end
$$;
Stiamo caricando il dump creato al passo 3.
pg_restore -h host -user -d database --data-only --format=c --table=data --verbose data.dmp > data_restore.log 2>&1Creiamo una sezione separata per i dati più vecchi
---------------------------------------------------
--create_partition_for_old_dates.sql
--creare partizioni per mantenere le date più vecchie
--versione 1.0
do language plpgsql $$
declare
rec_shipment_date RECORD ;
partition_name varchar;
index_name varchar;

begin

      SELECT min("SHIPMENT_DATE") AS min_date INTO rec_shipment_date from data ;

      RAISE NOTICE 'La data più vecchia è %',rec_shipment_date.min_date ;

      partition_name := 'data_old_dates'  ;

      RAISE NOTICE 'IL NOME DELLA PARTIZIONE È %',partition_name;

      EXECUTE format('CREATE TABLE ' || quote_ident(partition_name) || ' PARTITION OF data FOR VALUES FROM ( %L ) TO ( %L )  ' , '1900-01-01' ,
              to_char( rec_shipment_date.min_date,'YYYY')||'-'||to_char(rec_shipment_date.min_date,'MM')||'-01'  ) ;

      index_name := partition_name||'_shipment_id_parameter_id_idx';
      EXECUTE format('CREATE INDEX ' || quote_ident(index_name) || ' ON '|| quote_ident(partition_name) ||' USING btree ("SHIPMENT_ID", "PARAMETER_ID") TABLESPACE pg_default ' ) ;

      index_name := partition_name||'_lasermark_idx';
      EXECUTE format('CREATE INDEX ' || quote_ident(index_name) || ' ON '|| quote_ident(partition_name) ||' USING btree ("LASERMARK" COLLATE pg_catalog."default") TABLESPACE pg_default ' ) ;

      index_name := partition_name||'_shipment_id_idx';
      EXECUTE format('CREATE INDEX ' || quote_ident(index_name) || ' ON '|| quote_ident(partition_name) ||' USING btree ("SHIPMENT_ID") TABLESPACE pg_default ' ) ;

      index_name := partition_name||'_parameter_id_idx';
      EXECUTE format('CREATE INDEX ' || quote_ident(index_name) || ' ON '|| quote_ident(partition_name) ||' USING btree ("PARAMETER_ID") TABLESPACE pg_default ' ) ;

      index_name := partition_name||'_shipment_date_idx';
      EXECUTE format('CREATE INDEX ' || quote_ident(index_name) || ' ON '|| quote_ident(partition_name) ||' USING btree ("SHIPMENT_DATE") TABLESPACE pg_default ' ) ;

end
$$;
Risultati finali:
Era
Costo: 502 997.55
Tempo di esecuzione: 505 secondi.
Diventato
Costo: 68 533.70
Tempo di esecuzione: 69 secondi
Meritevole, decisamente meritevole. E considerando che lungo il cammino si è riusciti a comprendere il meccanismo di partizionamento in PostgreSQL 10 — Ottimo risultato.
Divagazione lirica
E si può fare ancora meglio — SÌ, SI PUÒ!Per questo è necessario utilizzare una MATERIALIZED VIEW.
CREATE MATERIALIZED VIEW LASERMARK_VIEW
CREATE MATERIALIZED VIEW LASERMARK_VIEW
AS
SELECT w."LASERMARK" , MAX(s."SHIPMENT_DATE") AS "SHIPMENT_DATE"
FROM shipment s INNER JOIN data w ON s."SHIPMENT_ID" = w."SHIPMENT_ID"
GROUP BY w."LASERMARK" ;

CREATE INDEX lasermark_vw_shipment_date_ind on lasermark_view USING btree ("SHIPMENT_DATE") TABLESPACE pg_default;
analyze lasermark_view ;
Ancora una volta riscriviamo la query:
Query utilizzando la materialized view
SELECT
            p."PARAMETER_ID" as  parameter_id,
            pc."PC_NAME" AS pc_name,
            pc."CUSTOMER_PARTNUMBER" AS customer_partnumber,
            w."LASERMARK" AS lasermark,
            w."LOTID" AS lotid,
            w."REPORTED_VALUE" AS reported_value,
            w."LOWER_SPEC_LIMIT" AS lower_spec_limit,
            w."UPPER_SPEC_LIMIT" AS upper_spec_limit,
            p."TYPE_CALCUL" AS type_calcul,
            s."SHIPMENT_NAME" AS shipment_name,
            s."SHIPMENT_DATE" AS shipment_date,
            extract(year from s."SHIPMENT_DATE") AS year,
            extract(month from s."SHIPMENT_DATE") as month,
            s."REPORT_NAME" AS report_name,
            p."STC_NAME" AS STC_name,
            p."CUSTOMERPARAM_NAME" AS customerparam_name
        FROM data w INNER JOIN shipment s ON s."SHIPMENT_ID" = w."SHIPMENT_ID"
             INNER JOIN parameters p ON p."PARAMETER_ID" = w."PARAMETER_ID"
             INNER JOIN shipment_pc sp ON s."SHIPMENT_ID" = sp."SHIPMENT_ID"
             INNER JOIN pc pc ON pc."PC_ID" = sp."PC_ID"
             INNER JOIN LASERMARK_VIEW md ON md."SHIPMENT_DATE" = s."SHIPMENT_DATE" AND md."LASERMARK" = w."LASERMARK"
        WHERE
              s."SHIPMENT_DATE" >= '2018-07-01' AND s."SHIPMENT_DATE" <= '2018-09-30';
E otteniamo un altro risultato:
Era
Costo: 502 997.55
Tempo di esecuzione: 505 secondi
Diventato
Costo: 42 481.16
Tempo di esecuzione: 43 secondi.
Sebbene, naturalmente, un risultato così promettente sia ingannevole, bisogna aggiornare le presentazioni. Quindi il tempo totale per l'ottenimento dei dati non sarà di grande aiuto. Ma come esperimento è piuttosto interessante.
In realtà, come si è scoperto, ancora una volta grazie e a Habr !-
Postfazione
Quindi, il cliente è soddisfatto. E bisogno sfruttare la situazione.
Nuovo compito: Cosa si può pensare per approfondire ed espandere?
E qui mi viene in mente — ragazzi, ma non abbiamo il monitoraggio dei nostri database PostgreSQL.
A dire il vero, c'è una certa forma di monitoraggio tramite Cloud Watch su AWS. Ma quale utilità ha questo monitoraggio per un DBA? In effetti, praticamente nessuna.
Se c'è l'opportunità di fare qualcosa di utile e interessante anche per se stessi, non si può perdere tale occasione …
PERCHÉ
Così siamo arrivati al punto più interessante:
3 Dicembre 2018.
Decisione di iniziare i lavori per l'analisi delle possibilità di monitoraggio delle prestazioni delle query PostgreSQL.
Ma questa è già un'altra storia.
Continua, a seguire …
Fonte: habr.com
