

This article describes the implementation of pipes in the Unix kernel. I was somewhat disappointed that a recent article titled “” turned out to be do not about the internal structure. I became curious and dug into old sources to find the answer.
What is it about?
Pipes — "probably the most important invention in Unix" — are a defining characteristic of the underlying Unix philosophy of combining small programs, as well as a familiar command line notation:
$ echo hello | wc -c
6
This functionality depends on the system call provided by the kernel pipe, which is described in the documentation pages and :
Pipes provide a unidirectional channel for inter-process communication. A pipe has an input (write end) and an output (read end). Data written to the pipe's input can be read from its output.
A pipe is created with the call
pipe(2), which returns two file descriptors: one refers to the input of the pipe, the other to the output.
The results of tracing the command above demonstrate the creation of a pipe and the flow of data through it from one process to another:
$ strace -qf -e execve,pipe,dup2,read,write
    sh -c 'echo hello | wc -c'

execve("/bin/sh", ["sh", "-c", "echo hello | wc -c"], …)
pipe([3, 4])                            = 0
[pid 2604795] dup2(4, 1)                = 1
[pid 2604795] write(1, "hellon", 6)    = 6
[pid 2604796] dup2(3, 0)                = 0
[pid 2604796] execve("/usr/bin/wc", ["wc", "-c"], …)
[pid 2604796] read(0, "hellon", 16384) = 6
[pid 2604796] write(1, "6n", 2)        = 2
The parent process calls pipe(), to obtain the connected file descriptors. One child process writes to one descriptor, while another process reads the same data from another descriptor. The shell, using dup2, "renames" descriptors 3 and 4 to correspond to stdin and stdout.
Without pipes, the shell would have to write the result of one process to a file and pass it to another process for reading from that file. As a result, we would waste more resources and disk space. However, pipes are beneficial not only because they allow avoiding temporary files:
If a process tries to read from an empty pipe, then
read(2)will block until data is available. If a process attempts to write to a full pipe, thenwrite(2)will block until enough data is read from the pipeline to perform the write.
Like the POSIX requirement, this is an important property: writing to the pipeline up to PIPE_BUF bytes (at least 512) must be atomic so that processes can interact with each other through the pipeline in a way that regular files (which do not provide such guarantees) cannot.
When using a regular file, a process can write all of its output to it and transfer it to another process. Or processes can operate in a strictly parallel mode, using an external signaling mechanism (like a semaphore) to notify each other when writing or reading is complete. Pipelines save us from all these hassles.
What are we looking for?
I'll explain it simply so you can better imagine how a pipeline might work. You'll need to allocate a buffer in memory and some state. You'll need functions for adding and removing data from the buffer. You will need some means to invoke functions during read and write operations on file descriptors. And you'll need locks to implement the special behavior described above.
Now we are ready to interrogate the source code of the kernel under bright light, to confirm or refute our vague mental model. But always be prepared for surprises.
Where are we looking?
I don't know where my copy of the famous book "" with the source code of Unix 6 is, but thanks to we can search online for of even older versions of Unix.
Wandering through the archives of TUHS is akin to visiting a museum. We can look back at our shared history, and I have great respect for the years of effort that went into recovering all this material bit by bit from old tapes and printouts. And I acutely feel the fragments that are still missing.
Having satisfied my curiosity about the ancient history of pipelines, for comparison, we can look at modern kernels.
By the way, pipe is syscall number 42 in the sysent[]table. Coincidence?
Traditional Unix kernels (1970–1974)
I found no traces pipe(2) either in (January 1970), or in (November 1971), nor in the incomplete source code (June 1972).
TUHS claims that (February 1973) was the first version with pipelines:
The third edition of Unix was the last version with a kernel written in assembly language, but it was the first version with pipelines. In 1973, work was underway to improve the third edition, and the kernel was rewritten in C, leading to the fourth edition of Unix.
One reader found a scan of a document in which Doug McIlroy proposed the idea of "connecting programs like a garden hose."
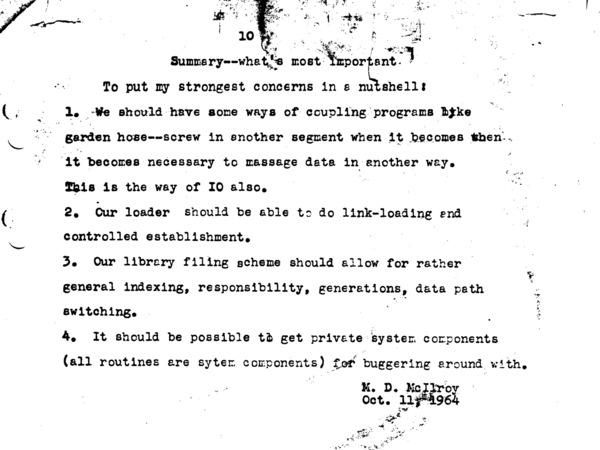
In Brian Kernighan's book "", this document is also mentioned in the history of pipelines: "… it hung on the wall in my office at Bell Labs for 30 years." Here is , and another story from :
When Unix emerged, my fascination with coroutines led me to ask the OS author, Ken Thompson, to allow data written in one process to go not only to a device but also to another process. Ken agreed that this was feasible. However, as a minimalist, he wanted each system function to play a significant role. Did direct writing between processes really have a major advantage over writing to an intermediate file? It was only when I made a specific proposal with the catchy title "pipeline" and a description of process interaction syntax that Ken finally exclaimed, "I'll do it!"
And he did. One fateful evening, Ken modified the kernel and shell, corrected several standard programs, standardizing their input procedures (which could come from pipelines), and also changed file names. The next day, pipelines began to be widely used in applications. By the end of the week, secretaries were using them to send documents from text editors to the printer. Shortly thereafter, Ken replaced the original API and syntax for shell pipeline usage with cleaner conventions that have been used ever since.
Unfortunately, the source code for the third edition Unix kernel is lost. While we have the C written source code for the , released in November 1973, it came out a few months before the official release and does not contain an implementation of pipelines. It is unfortunate that the source code of the legendary Unix feature is likely lost forever.
We have the text of the documentation for pipe(2) from both releases, so you can start by searching the documentation (by certain words, manually underlined, the line of literals ^H followed by an underscore!). This proto-pipe(2) is written in assembly language and returns only one file descriptor, but already provides the expected core functionality:
The system call pipe creates an input/output mechanism called a pipeline. The returned file descriptor can be used for read and write operations. When something is written to the pipeline, it is buffered up to 504 bytes of data, after which the write process is paused. When reading from the pipeline, the buffered data is retrieved.
By the next year, the kernel was rewritten in C, and acquired its modern form with the prototype "pipe(fildes)»:
The system call pipe creates an input/output mechanism called a pipeline. The returned file descriptors can be used in read and write operations. When something is written to the pipeline, the descriptor returned in r1 (corresponding to fildes[1]) is used, buffering up to 4096 bytes of data, after which the write process is paused. When reading from the pipeline, the descriptor returned in r0 (corresponding to fildes[0]) retrieves the data.
It is assumed that after defining the pipeline, two (or more) interacting processes (created by subsequent calls fork) will transfer data from the pipeline using calls write and exit.
The shell has syntax for defining a linear array of processes connected via a pipeline.
Calls to read from an empty pipeline (not containing buffered data), with only one end (all writing file descriptors closed), return "end of file". Calls to write in a similar situation are ignored.
The earliest refers (June 1974), but it is almost identical to that which appeared in the next release. Only comments have been added, so the fifth edition can be skipped.
The sixth edition of Unix (1975)
Let's start reading the source code of Unix (May 1975). Much thanks to Lions it's much easier to find it than the source code of earlier versions:
For many years the book Lions was the only document on the Unix core available outside the walls of Bell Labs. Although the sixth edition license allowed educators to use its source code, the seventh edition license excluded this possibility, so the book was distributed in the form of illegal typewritten copies.
Today, you can buy a reprinted copy of the book, which features students at a copying machine on the cover. And thanks to Warren Toomey (who initiated the TUHS project), you can download I want to give you an idea of how much effort went into creating the file:
More than 15 years ago, I typed up a copy of the source code presented in Lions, because I was not satisfied with the quality of my copy from an unknown number of other copies. TUHS didn’t exist yet, and I had no access to old sources. But in 1988, I found an old 9-track tape with a backup from a PDP11 computer. It was difficult to tell if it worked, but there was an intact tree /usr/src/, in which most files were dated 1979, which already looked ancient by then. This was the seventh edition or its derivative PWB, as I believed.
I took this find as a basis and manually edited the sources to the state of the sixth edition. Some of the code remained the same, some had to be tweaked a little, changing the modern token += to the outdated =+. I deleted some parts, and some I had to rewrite completely, but not too many.
And today we can read the source code of the sixth edition online on TUHS from .
By the way, at first glance, the main feature of C code prior to the Kernighan and Ritchie era is its brevity.I don't often get to insert code snippets without extensive editing to fit them into the relatively narrow viewing area on my website.
At the beginning there is an explanatory comment (and yes, there is still ):
/*
 * Max allowable buffering per pipe.
 * This is also the max size of the
 * file created to implement the pipe.
 * If this size is bigger than 4096,
 * pipes will be implemented in LARG
 * files, which is probably not good.
 */
#define    PIPSIZ    4096
The buffer size hasn't changed since the fourth edition. But here, without any public documentation, we see that at one time, pipelines used files as a backup storage!
As for the LARG files, they correspond to , which is used by the "large addressing algorithm" for processing. to support larger file systems. Since Ken said it's better not to use them, I will gladly take his word for it.
Here is the real system call pipe:
/*
 * The sys-pipe entry.
 * Allocate an inode on the root device.
 * Allocate 2 file structures.
 * Put it all together with flags.
 */
pipe()
{
    register *ip, *rf, *wf;
    int r;

    ip = ialloc(rootdev);
    if(ip == NULL)
        return;
    rf = falloc();
    if(rf == NULL) {
        iput(ip);
        return;
    }
    r = u.u_ar0[R0];
    wf = falloc();
    if(wf == NULL) {
        rf->f_count = 0;
        u.u_ofile[r] = NULL;
        iput(ip);
        return;
    }
    u.u_ar0[R1] = u.u_ar0[R0]; /* wf's fd */
    u.u_ar0[R0] = r;           /* rf's fd */
    wf->f_flag = FWRITE|FPIPE;
    wf->f_inode = ip;
    rf->f_flag = FREAD|FPIPE;
    rf->f_inode = ip;
    ip->i_count = 2;
    ip->i_flag = IACC|IUPD;
    ip->i_mode = IALLOC;
}
The comment clearly describes what is happening here. However, understanding the code isn't straightforward, partly due to how parameters and return values are passed using "" and registers R0 and R1 for passing system call parameters and return values.
Let's try to use to allocate on disk , and using to allocate in memory for two . If everything goes well, we will set flags to mark these files as the two ends of a pipe, specify them in the same inode (whose reference count will become 2), and mark the inode as modified and in use. Note the calls to in error paths to decrease the reference count in the new inode.
pipe() should return file descriptor numbers for reading and writing. R0 and R1 returns a pointer to a file structure but also "returns" through falloc() u.u_ar0[R0] and the file descriptor. That is, the code saves in the file descriptor for reading and assigns the descriptor for writing directly from r after the second call and the file descriptor. That is, the code saves in FPIPE falloc().
Flag , which we set when creating the pipe, manages the function's behaviorrdwr() in sys2.c The function
/*
 * common code for read and write calls:
 * check permissions, set base, count, and offset,
 * and switch out to readi, writei, or pipe code.
 */
rdwr(mode)
{
    register *fp, m;

    m = mode;
    fp = getf(u.u_ar0[R0]);
        /* … */

    if(fp->f_flag&FPIPE) {
        if(m==FREAD)
            readp(fp); else
            writep(fp);
    }
        /* … */
}
readp() pipe.c downward API support (simultaneously with this in reads data from the pipe. But it's better to trace the implementation starting from writep() . I reiterate, the code has become complex due to the peculiarities of the argument-passing convention, but some details can be omitted.writep(fp) { register *rp, *ip, c;rp = fp; ip = rp->f_inode; c = u.u_count;loop: /* If all done, return. */plock(ip); if(c == 0) { prele(ip); u.u_count = 0; return; }/* * If there are not both read and write sides of the * pipe active, return error and signal too. * /if(ip->i_count i_size1 == PIPSIZ) { ip->i_mode |= IWRITE; prele(ip); sleep(ip+1, PPIPE); goto loop; }/* Write what is possible and loop back. */u.u_offset[0] = 0; u.u_offset[1] = ip->i_size1; u.u_count = min(c, PIPSIZ-u.u_offset[1]); c -= u.u_count; writei(ip); prele(ip); if(ip->i_mode & IREAD) { ip->i_mode &= ~IREAD; wakeup(ip+2); } goto loop; }
At the input of the pipe, we want to write bytes
u.u_count . First, we need to lock the inode (see below)plock prele/prele).
Then we check the inode link counter. While both ends of the pipeline remain open, the counter should be equal to 2. We hold one link (from rp->f_inode), so if the counter is less than 2, it should mean that the reading process has closed its end of the pipeline. In other words, we are trying to write to a closed pipeline, which is an error. For the first time, the error code EPIPE and signal SIGPIPE appeared in the sixth edition of Unix.
But even if the pipeline is open, it can be full. In this case, we release the lock and go to sleep, hoping that another process will read from the pipeline and free up enough space in it. Upon waking, we return to the start, re-lock, and initiate a new write cycle.
If there is enough free space in the pipeline, we write data to it using . The parameter i_size1 of the inode (when the pipeline is empty, it can be equal to 0) indicates the end of the data that is already contained in it. If there is enough space to write, we can fill the pipeline from i_size1 up to PIPESIZ. We then release the lock and try to wake up any process that is waiting to read from the pipeline. We return to the start to see if we managed to write as many bytes as we needed. If not, we start a new write cycle.
Typically, the parameter i_mode of the inode is used to store permissions. r, w and xBut in the case of pipelines, we signal waiting by some writing or reading process using the bits IREAD and IWRITE respectively. A process sets a flag and calls sleep(),and it is expected that in the future, some other process will call wakeup()..
The real magic happens in sleep(), and wakeup().. They are implemented in , the source of the famous comment ‘You are not expected to understand this’. Luckily, we are not required to understand the code, we just look at some comments:
/*
 * Give up the processor till a wakeup occurs
 * on chan, at which time the process
 * enters the scheduling queue at priority pri.
 * The most important effect of pri is that when
 * pri<0 a signal cannot disturb the sleep;
 * if pri>=0 signals will be processed.
 * Callers of this routine must be prepared for
 * premature return, and check that the reason for
 * sleeping has gone away.
 */
sleep(chan, pri) /* … */

/*
 * Wake up all processes sleeping on chan.
 */
wakeup(chan) /* … */
A process that calls sleep(), for a certain channel, can later be awakened by another process that will call wakeup(). for the same channel. . I reiterate, the code has become complex due to the peculiarities of the argument-passing convention, but some details can be omitted. and pipe.c They coordinate their actions through such paired calls. Note that reads data from the pipe. But it's better to trace the implementation starting from always prioritizes PPIPE, when calling sleep(),thus all sleep(), can be interrupted by a signal.
Now we have everything to understand the function pipe.c:
readp(fp)
int *fp;
{
    register *rp, *ip;

    rp = fp;
    ip = rp->f_inode;

loop:
    /* Very conservative locking. */

    plock(ip);

    /*
     * If the head (read) has caught up with
     * the tail (write), reset both to 0.
     */

    if(rp->f_offset[1] == ip->i_size1) {
        if(rp->f_offset[1] != 0) {
            rp->f_offset[1] = 0;
            ip->i_size1 = 0;
            if(ip->i_mode&IWRITE) {
                ip->i_mode &= ~IWRITE;
                wakeup(ip+1);
            }
        }

        /*
         * If there are not both reader and
         * writer active, return without
         * satisfying read.
         */

        prele(ip);
        if(ip->i_count i_mode |= IREAD;
        sleep(ip+2, PPIPE);
        goto loop;
    }

    /* Read and return */

    u.u_offset[0] = 0;
    u.u_offset[1] = rp->f_offset[1];
    readi(ip);
    rp->f_offset[1] = u.u_offset[1];
    prele(ip);
}
You might find it easier to read this function from bottom to top. The 'read and return' branch is typically used when there is data in the pipeline. In this case, we use to read as much data as is available starting from the current f_offset position, and then update the corresponding offset value.
Upon subsequent reading, the pipeline will be empty if the read offset has reached the value i_size1 of the inode. We reset the position to 0 and attempt to wake up any process that wants to write to the pipeline. We know that when the pipeline is full, . I reiterate, the code has become complex due to the peculiarities of the argument-passing convention, but some details can be omitted. it will sleep on ip+1. And now, when the pipeline is empty, we can wake it up to resume its write cycle.
If there is nothing to read, then pipe.c it can set a flag IREAD and sleep on ip+2. We know that it will be woken up when data is written to the pipeline. . I reiterate, the code has become complex due to the peculiarities of the argument-passing convention, but some details can be omitted.Comments for
readi() and writei() ', we can handle them like ordinary input-output functions that take a file, a position, a buffer in memory, and count the number of bytes to read or write.uRegarding the 'conservative' locking,
/*
 * Read the file corresponding to
 * the inode pointed at by the argument.
 * The actual read arguments are found
 * in the variables:
 *    u_base        core address for destination
 *    u_offset    byte offset in file
 *    u_count        number of bytes to read
 *    u_segflg    read to kernel/user
 */
readi(aip)
struct inode *aip;
/* … */

/*
 * Write the file corresponding to
 * the inode pointed at by the argument.
 * The actual write arguments are found
 * in the variables:
 *    u_base        core address for source
 *    u_offset    byte offset in file
 *    u_count        number of bytes to write
 *    u_segflg    write to kernel/user
 */
writei(aip)
struct inode *aip;
/* … */
the inode is locked until the work is completed or a result is obtained (i.e., a call to pipe.c and . I reiterate, the code has become complex due to the peculiarities of the argument-passing convention, but some details can be omitted. wakeup plock()). prele() and work simply: using another set of calls allow us to wake any process that needs the lock we just released: sleep and plock() At first, I couldn't understand why
/*
 * Lock a pipe.
 * If its already locked, set the WANT bit and sleep.
 */
plock(ip)
int *ip;
{
    register *rp;

    rp = ip;
    while(rp->i_flag&ILOCK) {
        rp->i_flag =| IWANT;
        sleep(rp, PPIPE);
    }
    rp->i_flag =| ILOCK;
}

/*
 * Unlock a pipe.
 * If WANT bit is on, wakeup.
 * This routine is also used to unlock inodes in general.
 */
prele(ip)
int *ip;
{
    register *rp;

    rp = ip;
    rp->i_flag =& ~ILOCK;
    if(rp->i_flag&IWANT) {
        rp->i_flag =& ~IWANT;
        wakeup(rp);
    }
}
doesn't call pipe.c prele(ip) before calling wakeup(ip+1). The first thing it calls in its loop isplock(ip), which leads to a deadlock if . I reiterate, the code has become complex due to the peculiarities of the argument-passing convention, but some details can be omitted. hasn't released its lock yet, so the code somehow has to work correctly. Looking at should clarify the flow.the context of how pipe.c it handles these situations. wakeup()., it becomes clear that it only marks the sleeping process as ready for execution, so in the future sched() actually launched it. So pipe.c calls wakeup()., removes the lock, sets IREAD and calls sleep(ip+2)— all of this before . I reiterate, the code has become complex due to the peculiarities of the argument-passing convention, but some details can be omitted. resuming the cycle.
This concludes the description of pipes in the sixth edition. Simple code, far-reaching consequences.
(January 1979) was a new major release (four years later), which introduced many new applications and kernel properties. There were also significant changes related to typecasting, unions, and typed pointers to structures. However, has hardly changed. We can skip this edition.
Xv6, a simple Unix-like kernel
The creation of the kernel was influenced by the sixth edition of Unix, but it is written in modern C to run on x86 processors. The code is easy to read and understand. Moreover, unlike the Unix sources from TUHS, you can compile it, modify it, and run it on something other than the PDP 11/70. Therefore, this kernel is widely used in universities as educational material for operating systems. The sources .
The code contains a clear and well-thought-out implementation , backed by a buffer in memory instead of an inode on disk. Here, I provide only the definition of 'structural pipe' and the functions pipealloc():
#define PIPESIZE 512

struct pipe {
  struct spinlock lock;
  char data[PIPESIZE];
  uint nread;     // number of bytes read
  uint nwrite;    // number of bytes written
  int readopen;   // read fd is still open
  int writeopen;  // write fd is still open
};

int
pipealloc(struct file **f0, struct file **f1)
{
  struct pipe *p;

  p = 0;
  *f0 = *f1 = 0;
  if((*f0 = filealloc()) == 0 || (*f1 = filealloc()) == 0)
    goto bad;
  if((p = (struct pipe*)kalloc()) == 0)
    goto bad;
  p->readopen = 1;
  p->writeopen = 1;
  p->nwrite = 0;
  p->nread = 0;
  initlock(&p->lock, "pipe");
  (*f0)->type = FD_PIPE;
  (*f0)->readable = 1;
  (*f0)->writable = 0;
  (*f0)->pipe = p;
  (*f1)->type = FD_PIPE;
  (*f1)->readable = 0;
  (*f1)->writable = 1;
  (*f1)->pipe = p;
  return 0;

 bad:
  if(p)
    kfree((char*)p);
  if(*f0)
    fileclose(*f0);
  if(*f1)
    fileclose(*f1);
  return -1;
}
pipealloc() sets the state of the remaining implementation, which includes the functions piperead(), pipewrite() and pipeclose(). The actual system call sys_pipe is a wrapper implemented in . I recommend reading all of its code. The complexity is at the level of the sixth edition source, but it is much easier and more pleasant to read.
Linux 0.01
The source code of Linux 0.01 can be found. It would be instructive to study the implementation of pipes in its fs/reads data from the pipe. But it's better to trace the implementation starting from. Here, an inode is used to represent the pipe, but the pipe itself is written in modern C. If you have navigated through the code of the sixth edition, you will not face difficulties here. This is how the function looks write_pipe():
int write_pipe(struct m_inode * inode, char * buf, int count)
{
    char * b=buf;

    wake_up(&inode->i_wait);
    if (inode->i_count != 2) { /* no readers */
        current->signal |= (1< 0) {
        while (PIPE_FULL(*inode)) {
            wake_up(&inode->i_wait);
            if (inode->i_count != 2) {
                current->signal |= (1<i_wait);
        }
        ((char *)inode->i_size)[PIPE_HEAD(*inode)] =
            get_fs_byte(b++);
        INC_PIPE(PIPE_HEAD(*inode));
        wake_up(&inode->i_wait);
    }
    wake_up(&inode->i_wait);
    return b-buf;
}
Even without looking at the structure definitions, one can understand how the inode reference counter is used to check whether the write operation leads to SIGPIPE. Aside from byte-wise operations, this function can easily be correlated with the ideas described above. Even the logic sleep_on/wake_up does not seem so alien.
Modern Linux kernels, FreeBSD, NetBSD, OpenBSD
I quickly scanned through some modern kernels. None of them still implement disk-based solutions (not surprisingly). Linux has its own implementation. Although the three modern BSD kernels contain implementations based on code written by John Dyson, they have diverged significantly over the years.
To read fs/reads data from the pipe. But it's better to trace the implementation starting from (on Linux) or sys/kern/sys_pipe.c (on *BSD), real dedication is required. Today, performance and support for features like vectorized and asynchronous I/O operations are crucial in the code. Moreover, the details of memory allocation, locks, and kernel configuration all vary significantly. This is not what universities need for an introductory course on operating systems.
In any case, I found it interesting to unearth some vintage patterns (for instance, generating SIGPIPE and returning EPIPE when writing to a closed pipe) in all these very different modern kernels. I might never see a PDP-11 computer in person, but there is still much to learn from the code that was written years before my birth.
The article ‘’ written by Divy Kapoor in 2011 provides an overview of how (still) pipelines work in Linux. A illustrates the pipeline interaction model, whose capabilities exceed those of temporary files; it also shows how far pipelines have come from the ‘very conservative locking’ in the sixth edition Unix kernel.
Source: habr.com
