

Hello everyone, we are sharing with you the second part of the publication "Virtual File Systems in Linux: Why They Are Needed and How They Work?" The first part can be read . Let us remind you that this series of publications is dedicated to the launch of a new stream for the course , which starts very soon.
How to Observe VFS Using eBPF and bcc Tools
The simplest way to understand how the kernel operates with files sysfs is to observe it in practice, and the easiest way to monitor ARM64 is to use eBPF. eBPF (short for Berkeley Packet Filter) consists of a virtual machine running in , which privileged users can request (query) from the command line. The kernel source informs the reader about what the kernel can do; running eBPF tools on a loaded system shows what the kernel actually does.
Fortunately, it is easy to start using eBPF with tools , which are available as packages from the general distribution and are well documented The tools bcc are Python scripts with small C code inserts, meaning anyone familiar with both languages can easily modify them. In bcc/tools there are 80 Python scripts, so it is likely that a developer or system administrator will find something suitable for solving their task.
To get at least a superficial understanding of what role VFS plays in a running system, try vfscount or vfsstat.This will show, for instance, that dozens of calls to vfs_open() and "its friends" occur literally every second.
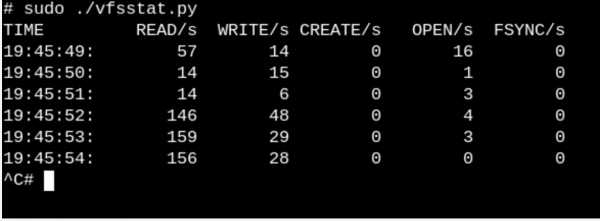
vfsstat.pyis a Python script with C code inserts that simply counts VFS function calls.
Let's provide a more trivial example and see what happens when we insert a USB flash drive into a computer and the system detects it.
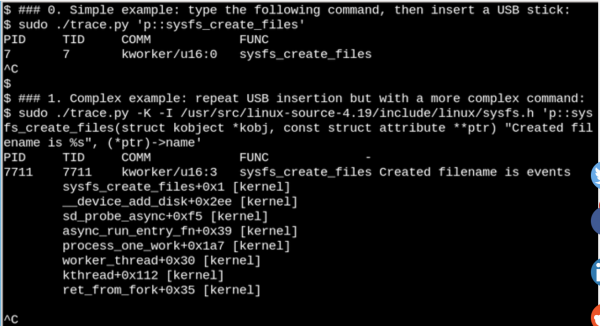
With eBPF you can see what happens in
/sys, when a USB flash drive is inserted. Here is a simple and a complex example.
In the example shown above, bcc tool outputs a message when the command sysfs_create_files()is executed. We can see that sysfs_create_files() it was triggered by kworker thread in response to the flash drive being inserted, but what file was created? The second example demonstrates the full power of eBPF. Here trace.py outputs a kernel backtrace (option -K) and the name of the created file sysfs_create_files(). The insertion in single quotes is C code that includes an easily recognizable format string, provided by a Python script that runs LLVM just-in-time compiler. This string is compiled and executed in a virtual machine within the kernel. The full signature of the function sysfs_create_files () must be replicated in the second command so that the format string can reference one of the parameters. Errors in this C code fragment lead to recognizable C compiler errors. For example, if the -l parameter is missing, you will see "Failed to compile BPF text." Developers who are well-acquainted with C and Python will find the tools bcc easy to extend and modify.
When a USB drive is inserted, the kernel backtrace will show that PID 7711 is the thread kworker, which created the file "events" downward API support (simultaneously with this in sysfs. Accordingly, the call to sysfs_remove_files() will show that removing the drive resulted in the deletion of the file events, which corresponds to the general concept of reference counting. In this process, viewing sysfs_create_link () with eBPF during USB drive insertion will indicate that at least 48 symbolic links were created.
So what is the purpose of the events file? Using to search for , shows that it calls disk_add_events (), and either "media_change", or "eject_request" may be written to the events file. Here, the kernel block layer informs userspace of the insertion and ejection of the 'disk'. Note how informative this method of investigation is when inserting a USB drive compared to trying to figure out how everything works solely from the sources.
Read-only root file systems enable embedded devices
Of course, no one turns off the server or their computer by pulling the plug out of the wall. But why? It's because mounted file systems on physical storage devices may have pending writes, and the data structures recording their state may not synchronize with the records in storage. When this happens, system owners must wait for the next boot to run the fsck filesystem-recovery utility and, in the worst case, lose data.
However, we all know that many IoT devices, as well as routers, thermostats, and cars, now operate under Linux. Many of these devices have virtually no user interface, and there is no way to turn them off 'cleanly'. Imagine starting a car with a dead battery when the power to the control unit is constantly fluctuating. How does it happen that the system boots up without a long delay, fsckwhen the engine finally starts running? The answer is simple. Embedded devices rely on a root file system, (shortened to ro-rootfs (read-only root filesystem).
ro-rootfs These offer numerous advantages that are less obvious than authenticity. One benefit is that malware cannot write to /usr or /lib, if no Linux process can write to it. Another is that a largely immutable file system is critical for field support of remote devices, as support staff use local systems that are nominally identical to the systems in the field. Perhaps the most important (but also the trickiest) advantage is that ro-rootfs forces developers to decide which system objects will be immutable early in the system design phase. Working with ro-rootfs can be inconvenient and painful, much like dealing with const variables in programming languages, but their benefits easily outweigh the additional overhead.
Creating rootfs Read-only file systems require some additional effort from embedded systems developers, and this is where VFS comes into play. Linux requires that files in /var be writable, and moreover, many popular applications that run embedded systems will try to create configuration dot-files. downward API support (simultaneously with this in $HOMEOne solution for configuration files in the home directory is usually their pre-generation and assembly into rootfs. For /var One possible approach is to mount it in a separate writable partition, while / itself is mounted read-only. Another popular alternative is to use bind or overlay mounts.
Bind and overlay mounts, using them with containers
Executing the command man mount – is the best way to learn about bind and overlay mounts that allow developers and system administrators to create a file system at one path and then provide it to applications at another. For embedded systems, this means the ability to store files on /var a read-only flash drive, but overlaying or binding a path from tmpfs downward API support (simultaneously with this in /var at boot will allow applications to write there (scrawl). The next time it is powered on, changes in /var will be lost. An overlay mount creates a union between tmpfs and the underlying file system and allows you to make apparent changes to existing files in ro-tootf whereas a bind mount can make new empty tmpfs directories visible as writable in ro-rootfs paths. While overlayfs is the correct (proper) type of file system, bind mounting is implemented in .
Based on the description of overlay and bind mounting, it's no surprise that actively use them. Let's observe what happens when we use to run a container, using the tool mountsnoop from bcc.
Call system-nspawn starts the container during the operation mountsnoop.py.
Let's see what we got:
Start mountsnoop during the container's 'boot' shows that the container runtime environment heavily relies on bind mounting (Only the start of a long output is displayed).
Here systemd-nspawn provides selected files from Functions and sysfs the host into the container as paths in its rootfs. In addition to the MS_BIND flag, which sets the bind mount, some other flags in the mounting system define the relationship between changes in the host's namespace and the container. For example, a bind mount can either pass changes into /proc and /sys the container, or hide them depending on the call.
Conclusion
Understanding the inner workings of Linux may seem like an impossible task, as the kernel itself contains a massive amount of code, not to mention the user space Linux applications and system call interfaces in C language libraries, such as glibc. One way to make progress is to read the source code of a kernel subsystem, focusing on understanding system calls and headers addressed to user space, as well as key internal kernel interfaces, for instance, the table file_operations. File operations adhere to the principle of "everything is a file," making their management particularly enjoyable. The core source files written in C are located in the top-level directory fs/ and represent the implementation of virtual file systems, which act as a shell layer providing broad and relatively straightforward compatibility for popular file systems and storage devices. Mounting through binding and overlaying via Linux namespaces is the magic of VFS, enabling the creation of containers and read-only root file systems. Combined with studying the source code, the eBPF core tool and its interface bcc
make exploring the kernel easier than ever.
Friends, did you find this article useful? Perhaps you have some comments or suggestions? For those interested in the "Linux Administrator" course, we invite you to , which will take place on April 18.
Source: habr.com
