

LINQ was introduced in .NET as a powerful new data manipulation language. LINQ to SQL, as part of it, allows for convenient interaction with the DBMS using, for example, Entity Framework. However, developers often overlook what SQL query will be generated by the queryable provider, in your case — Entity Framework.
Let's examine two main points through an example.
To do this, we will create a database called Test in SQL Server, and within it, we will create two tables using the following query:
Creating tables
USE [TEST]
GO

SET ANSI_NULLS ON
GO

SET QUOTED_IDENTIFIER ON
GO

CREATE TABLE [dbo].[Ref](
	[ID] [int] NOT NULL,
	[ID2] [int] NOT NULL,
	[Name] [nvarchar](255) NOT NULL,
	[InsertUTCDate] [datetime] NOT NULL,
 CONSTRAINT [PK_Ref] PRIMARY KEY CLUSTERED
(
	[ID] ASC
)WITH (PAD_INDEX = OFF, STATISTICS_NORECOMPUTE = OFF, IGNORE_DUP_KEY = OFF, ALLOW_ROW_LOCKS = ON, ALLOW_PAGE_LOCKS = ON) ON [PRIMARY]
) ON [PRIMARY]
GO

ALTER TABLE [dbo].[Ref] ADD  CONSTRAINT [DF_Ref_InsertUTCDate]  DEFAULT (getutcdate()) FOR [InsertUTCDate]
GO

USE [TEST]
GO

SET ANSI_NULLS ON
GO

SET QUOTED_IDENTIFIER ON
GO

CREATE TABLE [dbo].[Customer](
	[ID] [int] NOT NULL,
	[Name] [nvarchar](255) NOT NULL,
	[Ref_ID] [int] NOT NULL,
	[InsertUTCDate] [datetime] NOT NULL,
	[Ref_ID2] [int] NOT NULL,
 CONSTRAINT [PK_Customer] PRIMARY KEY CLUSTERED
(
	[ID] ASC
)WITH (PAD_INDEX = OFF, STATISTICS_NORECOMPUTE = OFF, IGNORE_DUP_KEY = OFF, ALLOW_ROW_LOCKS = ON, ALLOW_PAGE_LOCKS = ON) ON [PRIMARY]
) ON [PRIMARY]
GO

ALTER TABLE [dbo].[Customer] ADD  CONSTRAINT [DF_Customer_Ref_ID]  DEFAULT ((0)) FOR [Ref_ID]
GO

ALTER TABLE [dbo].[Customer] ADD  CONSTRAINT [DF_Customer_InsertUTCDate]  DEFAULT (getutcdate()) FOR [InsertUTCDate]
GO
Now, let's populate the Ref table by executing the following script:
Populating the Ref table
USE [TEST]
GO

DECLARE @ind INT=1;

WHILE(@ind<1200000)
BEGIN
	INSERT INTO [dbo].[Ref]
           ([ID]
           ,[ID2]
           ,[Name])
    SELECT
           @ind
           ,@ind
           ,CAST(@ind AS NVARCHAR(255));

	SET @ind=@ind+1;
END
GO
Similarly, we will populate the Customer table using the following script:
Populating the Customer table
USE [TEST]
GO

DECLARE @ind INT=1;
DECLARE @ind_ref INT=1;

WHILE(@ind<=12000000)
BEGIN
	IF(@ind%3=0) SET @ind_ref=1;
	ELSE IF (@ind%5=0) SET @ind_ref=2;
	ELSE IF (@ind%7=0) SET @ind_ref=3;
	ELSE IF (@ind=0) SET @ind_ref=4;
	ELSE IF (@ind=0) SET @ind_ref=5;
	ELSE IF (@ind=0) SET @ind_ref=6;
	ELSE IF (@ind=0) SET @ind_ref=7;
	ELSE IF (@ind=0) SET @ind_ref=8;
	ELSE IF (@ind=0) SET @ind_ref=9;
	ELSE IF (@ind=0) SET @ind_ref=10;
	ELSE IF (@ind=0) SET @ind_ref=11;
	ELSE SET @ind_ref=@ind90000;

	INSERT INTO [dbo].[Customer]
	 ([ID]
	 ,[Name]
	 ,[Ref_ID]
	 ,[Ref_ID2])
	 SELECT
	 @ind,
	 CAST(@ind AS NVARCHAR(255)),
	 @ind_ref,
	 @ind_ref;


	SET @ind=@ind+1;
END
GO
Thus, we have obtained two tables, with one containing over 1 million rows of data, and the other having more than 10 million rows of data.
Now in Visual Studio, you need to create a test project Visual C# Console App (.NET Framework):
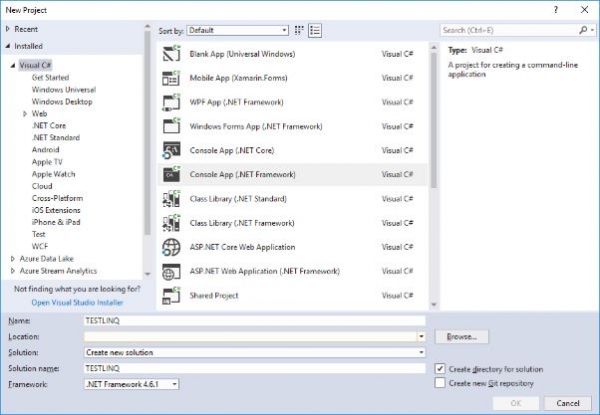
Next, you need to add a library for Entity Framework to interact with the database.
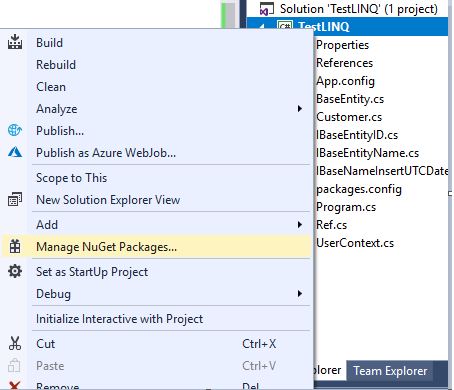
To add it, we will right-click on the project and select Manage NuGet Packages from the context menu:
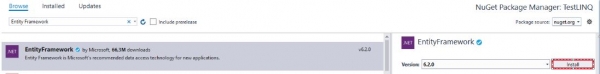
Then, in the NuGet Package Manager window that appears, we will enter the word 'Entity Framework' in the search box, select the Entity Framework package, and install it:
Next, in the App.config file, after closing the configSections element, we need to add the following block:
In the connectionString, you need to enter the connection string.
Now let's create 3 interfaces in separate files:
- Implementation of the IBaseEntityID interface
namespace TestLINQ { public interface IBaseEntityID { int ID { get; set; } } } - Implementation of the IBaseEntityName interface
namespace TestLINQ { public interface IBaseEntityName { string Name { get; set; } } } - Implementation of the IBaseNameInsertUTCDate interface
namespace TestLINQ
{
    public interface IBaseNameInsertUTCDate
    {
        DateTime InsertUTCDate { get; set; }
    }
}
And in a separate file, we will create a base class BaseEntity for our two entities, which will contain common fields:
Implementation of the BaseEntity base class
namespace TestLINQ
{
    public class BaseEntity : IBaseEntityID, IBaseEntityName, IBaseNameInsertUTCDate
    {
        public int ID { get; set; }
        public string Name { get; set; }
        public DateTime InsertUTCDate { get; set; }
    }
}
Next, we will create our two entities in separate files:
- Implementation of the Ref class
using System.ComponentModel.DataAnnotations.Schema; namespace TestLINQ { [Table("Ref")] public class Ref : BaseEntity { public int ID2 { get; set; } } } - Implementation of the Customer class
using System.ComponentModel.DataAnnotations.Schema;

namespace TestLINQ
{
    [Table("Customer")]
    public class Customer: BaseEntity
    {
        public int Ref_ID { get; set; }
        public int Ref_ID2 { get; set; }
    }
}
Now let's create the UserContext in a separate file:
Implementation of the UserContext class
using System.Data.Entity;

namespace TestLINQ
{
    public class UserContext : DbContext
    {
        public UserContext()
            : base("DbConnection")
        {
            Database.SetInitializer(null);
        }

        public DbSet Customer { get; set; }
        public DbSet Ref { get; set; }
    }
}
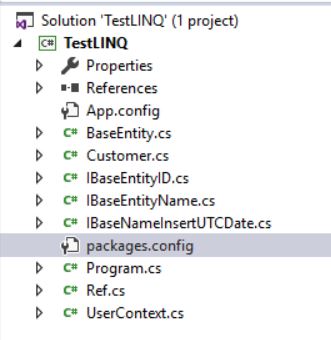
We have a ready solution for conducting optimization tests with LINQ to SQL via EF for MS SQL Server:
Now let's enter the following code in the Program.cs file:
Program.cs file
using System;
using System.Collections.Generic;
using System.Linq;

namespace TestLINQ
{
    class Program
    {
        static void Main(string[] args)
        {
            using (UserContext db = new UserContext())
            {
                var dblog = new List();
                db.Database.Log = dblog.Add;

                var query = from e1 in db.Customer
                            from e2 in db.Ref
                            where (e1.Ref_ID == e2.ID)
                                 && (e1.Ref_ID2 == e2.ID2)
                            select new { Data1 = e1.Name, Data2 = e2.Name };

                var result = query.Take(1000).ToList();

                Console.WriteLine(dblog[1]);

                Console.ReadKey();
            }
        }
    }
}
Next, we will run our project.
At the end of the execution, the console will display:
Generated SQL Query
SELECT TOP (1000)
    [Extent1].[Ref_ID] AS [Ref_ID],
    [Extent1].[Name] AS [Name],
    [Extent2].[Name] AS [Name1]
    FROM  [dbo].[Customer] AS [Extent1]
    INNER JOIN [dbo].[Ref] AS [Extent2] ON ([Extent1].[Ref_ID] = [Extent2].[ID]) AND ([Extent1].[Ref_ID2] = [Extent2].[ID2])
So, in general, the LINQ query generated a SQL query for the MS SQL Server quite well.
Now let's change the AND condition to OR in the LINQ query:
LINQ query
var query = from e1 in db.Customer
                            from e2 in db.Ref
                            where (e1.Ref_ID == e2.ID)
                                || (e1.Ref_ID2 == e2.ID2)
                            select new { Data1 = e1.Name, Data2 = e2.Name };
And again, we will run our application.
Execution will throw an error related to exceeding the command timeout of 30 seconds:
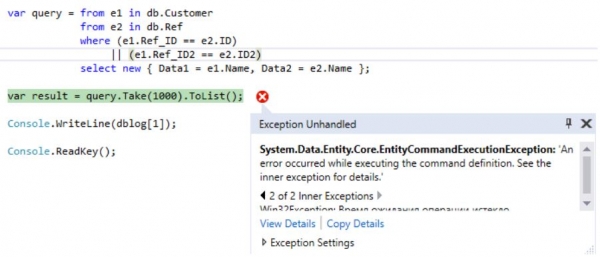
If we look at what query was generated by LINQ:
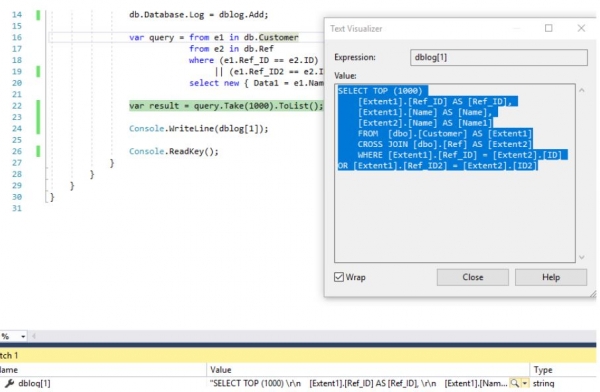
, we can see that the selection occurs through the Cartesian product of two sets (tables):
Generated SQL Query
SELECT TOP (1000)
    [Extent1].[Ref_ID] AS [Ref_ID],
    [Extent1].[Name] AS [Name],
    [Extent2].[Name] AS [Name1]
    FROM  [dbo].[Customer] AS [Extent1]
    CROSS JOIN [dbo].[Ref] AS [Extent2]
    WHERE [Extent1].[Ref_ID] = [Extent2].[ID] OR [Extent1].[Ref_ID2] = [Extent2].[ID2]
Let's rewrite the LINQ query as follows:
Optimized LINQ Query
var query = (from e1 in db.Customer
                   join e2 in db.Ref
                   on e1.Ref_ID equals e2.ID
                   select new { Data1 = e1.Name, Data2 = e2.Name }).Union(
                        from e1 in db.Customer
                        join e2 in db.Ref
                        on e1.Ref_ID2 equals e2.ID2
                        select new { Data1 = e1.Name, Data2 = e2.Name });
Then we will get the following SQL query:
SQL query
SELECT
    [Limit1].[C1] AS [C1],
    [Limit1].[C2] AS [C2],
    [Limit1].[C3] AS [C3]
    FROM ( SELECT DISTINCT TOP (1000)
        [UnionAll1].[C1] AS [C1],
        [UnionAll1].[Name] AS [C2],
        [UnionAll1].[Name1] AS [C3]
        FROM  (SELECT
            1 AS [C1],
            [Extent1].[Name] AS [Name],
            [Extent2].[Name] AS [Name1]
            FROM  [dbo].[Customer] AS [Extent1]
            INNER JOIN [dbo].[Ref] AS [Extent2] ON [Extent1].[Ref_ID] = [Extent2].[ID]
        UNION ALL
            SELECT
            1 AS [C1],
            [Extent3].[Name] AS [Name],
            [Extent4].[Name] AS [Name1]
            FROM  [dbo].[Customer] AS [Extent3]
            INNER JOIN [dbo].[Ref] AS [Extent4] ON [Extent3].[Ref_ID2] = [Extent4].[ID2]) AS [UnionAll1]
    )  AS [Limit1]
Unfortunately, in LINQ queries, there can only be one join condition. Therefore, an equivalent query can be made through two queries for each condition, subsequently merging them using Union to remove duplicate rows.
Yes, the queries will generally be non-equivalent considering that full duplicate rows might be returned. However, in real life, complete duplicate rows are not needed and are typically removed.
Now let's compare the execution plans of these two queries:
- for CROSS JOIN the average execution time is 195 seconds:

- for INNER JOIN-UNION the average execution time is less than 24 seconds:

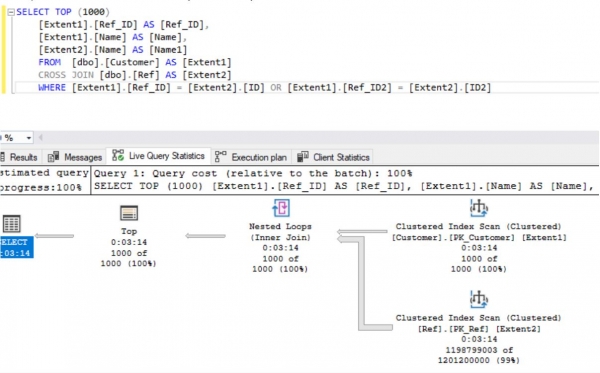
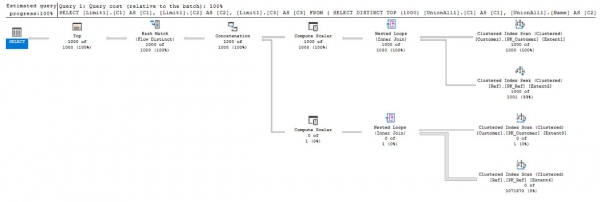
As seen from the results, for two tables with millions of records, the optimized LINQ query runs several times faster than the non-optimized one.
For the AND condition in LINQ queries of the following form:
LINQ query
var query = from e1 in db.Customer
                            from e2 in db.Ref
                            where (e1.Ref_ID == e2.ID)
                                 && (e1.Ref_ID2 == e2.ID2)
                            select new { Data1 = e1.Name, Data2 = e2.Name };
there will almost always be a correctly generated SQL query, which will run in an average of about 1 second:
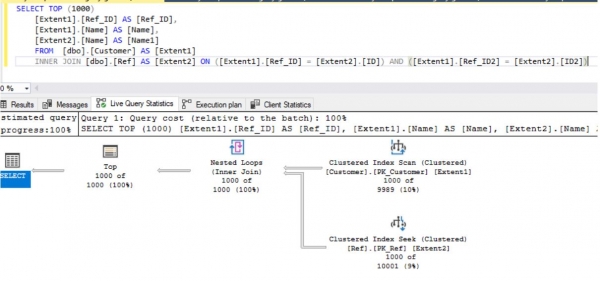
Also, for LINQ to Objects manipulations instead of a query of the form:
LINQ query (1st variant)
var query = from e1 in seq1
                            from e2 in seq2
                            where (e1.Key1 == e2.Key1)
                               && (e1.Key2 == e2.Key2)
                            select new { Data1 = e1.Data, Data2 = e2.Data };
you can use a query of the form:
LINQ query (2nd variant)
var query = from e1 in seq1
                            join e2 in seq2
                            on new { e1.Key1, e1.Key2 } equals new { e2.Key1, e2.Key2 }
                            select new { Data1 = e1.Data, Data2 = e2.Data };
where:
Definition of two arrays
Para[] seq1 = new[] { new Para { Key1 = 1, Key2 = 2, Data = "777" }, new Para { Key1 = 2, Key2 = 3, Data = "888" }, new Para { Key1 = 3, Key2 = 4, Data = "999" } };
Para[] seq2 = new[] { new Para { Key1 = 1, Key2 = 2, Data = "777" }, new Para { Key1 = 2, Key2 = 3, Data = "888" }, new Para { Key1 = 3, Key2 = 5, Data = "999" } };
, and the Para type is defined as follows:
Definition of the Para type
class Para
{
        public int Key1, Key2;
        public string Data;
}
Thus, we have covered some aspects of optimizing LINQ queries to MS SQL Server.
Unfortunately, even experienced and leading .NET developers forget that it is crucial to understand what happens behind the scenes with the instructions they use. Otherwise, they become mere configurators and may set a time bomb for the future, both in scaling the software solution and in minor changes to the external environment conditions.
A brief overview was also conducted and .
The source files for the test - the project itself, the creation of tables in the TEST database, as well as the filling of these tables with data are located .
Also, in this repository, the Plans folder contains the execution plans with OR conditions.
Source: habr.com
