

The first step when working with a new dataset is to understand it. To do this, for example, you need to determine the range of values for variables, their types, as well as find out about the number of missing values.
The pandas library provides us with many useful tools for performing Exploratory Data Analysis (EDA). However, before using them, it is usually necessary to start with more general functions, such as df.describe(). It is worth noting that the capabilities offered by such functions are limited, and the initial steps in working with any datasets during EDA often resemble each other.
The author of the material we are publishing today states that he is not a fan of performing repetitive tasks. As a result, in search of tools that can quickly and effectively perform exploratory data analysis, he found the library . Its output is not expressed in the form of isolated indicators, but as a fairly detailed HTML report containing much of the information about the analyzed data that may be needed before starting more in-depth work with it.
This section will discuss the features of using the pandas-profiling library using the Titanic dataset as an example.
Exploratory data analysis using pandas
I decided to experiment with pandas-profiling on the Titanic dataset because it contains data of different types and has missing values. I believe that the pandas-profiling library is particularly interesting in cases where the data has not yet been cleaned and requires further processing, depending on its characteristics. In order to successfully perform such processing, one must know where to start and what to pay attention to. This is where the capabilities of pandas-profiling come in handy.
First, let's import the data and use pandas to obtain descriptive statistics:
# импорт необходимых пакетов
import pandas as pd
import pandas_profiling
import numpy as np

# импорт данных
df = pd.read_csv('/Users/lukas/Downloads/titanic/train.csv')

# вычисление показателей описательной статистики
df.describe()
After executing this code fragment, the result will be as shown in the following figure.
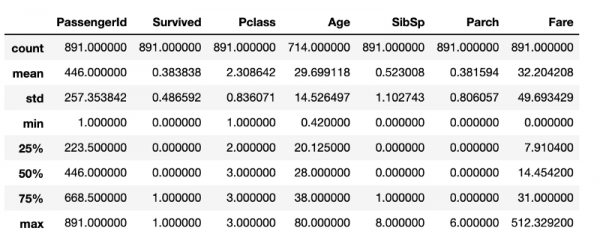
Descriptive statistics obtained using standard pandas tools
Although this contains a wealth of useful information, there is not everything one might want to know about the analyzed data. For example, it can be assumed that the data frame has 891 rows. If this needs to be verified, another line of code will be required to determine the size of the frame. Although these calculations are not particularly resource-intensive, repeating them frequently will surely lead to time loss, which is probably better spent on data cleaning. DataFrameExploratory data analysis using pandas-profiling
Now let's do the same using pandas-profiling:
pandas_profiling.ProfileReport(df)
Executing the above code line will generate a report with exploratory data analysis metrics. The code shown above will output the information found about the data, but it can be done in such a way that the result is an HTML file that can be shown to someone.The first part of the report will contain the Overview section, providing key information about the data (number of observations, number of variables, and so on). Additionally, it will include a list of warnings, notifying the analyst about what deserves special attention. These warnings can serve as hints on where to focus efforts during data cleaning.
Overview Section
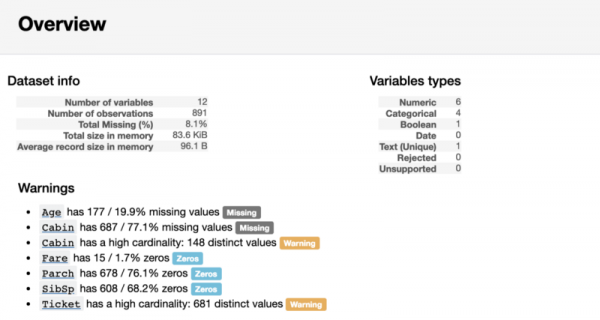
Exploratory analysis of variables
Following the Overview section in the report, useful information about each variable can be found. These include, among other things, small charts describing the distribution of each variable.
Information about the numerical variable Age
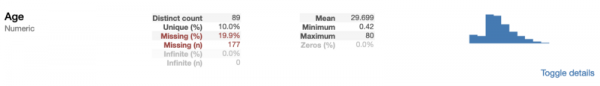
As can be seen from the previous example, pandas-profiling provides several useful indicators, such as the percentage and number of missing values, as well as descriptive statistics that we have already seen. Since
Age is a numerical variable, visualizing its distribution as a histogram allows us to conclude that it is a right-skewed distribution. When examining a categorical variable, the displayed metrics differ slightly from those found for the numerical variable.
Information about the categorical variable Sex
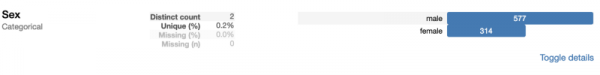
Information about the categorical variable Sex
Specifically, instead of searching for the mean, minimum, and maximum, the pandas-profiling library found the number of classes. Since Sex — is a binary variable, its values are represented by two classes.
If you, like me, enjoy exploring code, you may be interested in how exactly the pandas-profiling library calculates these metrics. It's not too difficult to find out, considering the library's code is open and available on GitHub. As I am not a big fan of using 'black boxes' in my projects, I took a look at the library's source code. For example, here's how the mechanism for processing numerical variables looks, represented by the function :
def describe_numeric_1d(series, **kwargs):
    """Compute summary statistics of a numerical (`TYPE_NUM`) variable (a Series).
    Also create histograms (mini and full) of its distribution.
    Parameters
    ----------
    series : Series
        The variable to describe.
    Returns
    -------
    Series
        The description of the variable as a Series with index being stats keys.
    """
    # Format a number as a percentage. For example 0.25 will be turned to 25%.
    _percentile_format = "{:.0%}"
    stats = dict()
    stats['type'] = base.TYPE_NUM
    stats['mean'] = series.mean()
    stats['std'] = series.std()
    stats['variance'] = series.var()
    stats['min'] = series.min()
    stats['max'] = series.max()
    stats['range'] = stats['max'] - stats['min']
    # To avoid to compute it several times
    _series_no_na = series.dropna()
    for percentile in np.array([0.05, 0.25, 0.5, 0.75, 0.95]):
        # The dropna() is a workaround for https://github.com/pydata/pandas/issues/13098
        stats[_percentile_format.format(percentile)] = _series_no_na.quantile(percentile)
    stats['iqr'] = stats['75%'] - stats['25%']
    stats['kurtosis'] = series.kurt()
    stats['skewness'] = series.skew()
    stats['sum'] = series.sum()
    stats['mad'] = series.mad()
    stats['cv'] = stats['std'] / stats['mean'] if stats['mean'] else np.NaN
    stats['n_zeros'] = (len(series) - np.count_nonzero(series))
    stats['p_zeros'] = stats['n_zeros'] * 1.0 / len(series)
    # Histograms
    stats['histogram'] = histogram(series, **kwargs)
    stats['mini_histogram'] = mini_histogram(series, **kwargs)
    return pd.Series(stats, name=series.name)
Although this code snippet may seem quite large and complex, in reality, it is very straightforward to understand. The point is that the library's source code contains a function that determines the types of variables. If it turns out that the library encounters a numerical variable, the aforementioned function will find the metrics we discussed. This function uses standard pandas operations to work with objects of the type Series, such as series.mean(). The computation results are stored in a dictionary stats. Histograms are generated using an adapted version of the function matplotlib.pyplot.histThe adaptation is aimed at enabling the function to work with various types of datasets.
Correlation metrics and sample data under investigation
After analyzing the variables using pandas-profiling, the Correlations section will display Pearson and Spearman correlation matrices.
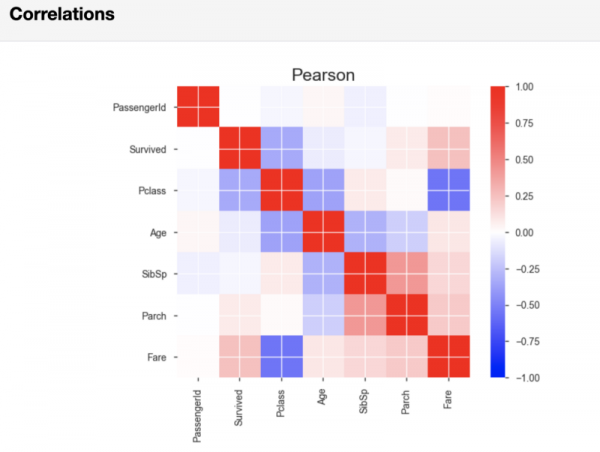
Pearson correlation matrix
If needed, you can specify threshold metrics used in the correlation calculation in the line of code that initiates report generation. By doing this, you can define what level of correlation is considered significant for your analysis.
Finally, in the pandas-profiling report, the Sample section displays a snippet of data taken from the beginning of the dataset. This approach can lead to unpleasant surprises, as the first few observations may represent a sample that does not reflect the characteristics of the entire dataset.
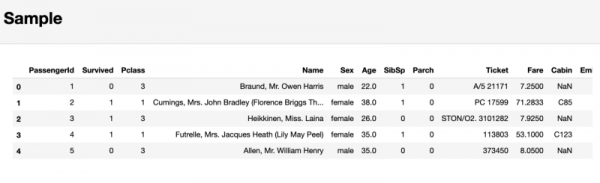
Section containing the sample data under investigation
As a result, I do not recommend focusing on this last section. Instead, it's better to use the command df.sample(5), which will randomly select 5 observations from the dataset.
Summary
In summary, the pandas-profiling library provides analysts with useful features that come in handy when a quick overview of the data is required, or when you need to provide someone with a report on exploratory data analysis. Actual data work, taking their characteristics into account, is still done manually, just as it would without using pandas-profiling.
If you want to see what an entire exploratory data analysis looks like in a single Jupyter notebook, check out my project created with nbviewer. And in the GitHub repository, you can find the corresponding code.
Dear readers! Where do you start your analysis of new datasets?
Source: habr.com
