

In today's world, it's impossible to imagine a project based on Kubernetes without the ELK stack, which saves the logs of both applications and the system components of the cluster. In our practice, we use the EFK stack with Fluentd instead of Logstash.
Fluentd is a modern universal log collector that is gaining popularity and has joined the Cloud Native Computing Foundation, which has directed its development towards use with Kubernetes.
The use of Fluentd instead of Logstash does not change the overall essence of the software suite; however, Fluentd has its own specific nuances due to its multifunctionality.
For example, when we started using EFK in a high-load project with a high log write intensity, we encountered an issue where some messages in Kibana were displayed multiple times. In this article, we will explain why this phenomenon occurs and how to solve the problem.
Document Duplication Issue
In our projects, Fluentd is deployed as a DaemonSet (automatically started as a single instance on each node of the Kubernetes cluster) and monitors stdout logs of containers in /var/log/containers. After collection and processing, logs in the form of JSON documents are sent to ElasticSearch, deployed in either a clustered or standalone mode, depending on the project's scale and performance and fault tolerance requirements. Kibana is used as the graphical interface.
When using Fluentd with a buffering plugin at the output, we encountered a situation where some documents in ElasticSearch have completely identical content, differing only by their identifier. You can verify that these are indeed duplicate messages by looking at an Nginx log. In the log file, this message exists in a single instance:
127.0.0.1 192.168.0.1 - [28/Feb/2013:12:00:00 +0900] "GET / HTTP/1.1" 200 777 "-" "Opera/12.0" -However, in ElasticSearch, there are several documents containing this message:
{
  "_index": "test-custom-prod-example-2020.01.02",
  "_type": "_doc",
  "_id": "HgGl_nIBR8C-2_33RlQV",
  "_version": 1,
  "_score": 0,
  "_source": {
    "service": "test-custom-prod-example",
    "container_name": "nginx",
    "namespace": "test-prod",
    "@timestamp": "2020-01-14T05:29:47.599052886 00:00",
    "log": "127.0.0.1 192.168.0.1 - [28/Feb/2013:12:00:00  0900] \"GET / HTTP/1.1\" 200 777 \"-\" \"Opera/12.0\" -",
    "tag": "custom-log"
  }
}

{
  "_index": "test-custom-prod-example-2020.01.02",
  "_type": "_doc",
  "_id": "IgGm_nIBR8C-2_33e2ST",
  "_version": 1,
  "_score": 0,
  "_source": {
    "service": "test-custom-prod-example",
    "container_name": "nginx",
    "namespace": "test-prod",
    "@timestamp": "2020-01-14T05:29:47.599052886 00:00",
    "log": "127.0.0.1 192.168.0.1 - [28/Feb/2013:12:00:00  0900] \"GET / HTTP/1.1\" 200 777 \"-\" \"Opera/12.0\" -",
    "tag": "custom-log"
  }
}
Moreover, there may be more than two repetitions.
During the observation of this issue in the Fluentd logs, a large number of warnings with the following content can be seen:
2020-01-16 01:46:46 +0000 [warn]: [test-prod] failed to flush the buffer. retry_time=4 next_retry_seconds=2020-01-16 01:46:53 +0000 chunk="59c37fc3fb320608692c352802b973ce" error_class=Fluent::Plugin::ElasticsearchOutput::RecoverableRequestFailure error="could not push logs to Elasticsearch cluster ({:host=>\"elasticsearch\", :port=>9200, :scheme=>\"http\", :user=>\"elastic\", :password=>\"obfuscated\"}): read timeout reached"These warnings occur when Elasticsearch cannot return a response to the request within the time set by the request_timeout parameter, preventing the sent buffer chunk from being cleared. After this, Fluentd attempts to resend the buffer chunk to Elasticsearch, and after an arbitrary number of attempts, the operation is successful.
2020-01-16 01:47:05 +0000 [warn]: [test-prod] retry succeeded. chunk_id="59c37fc3fb320608692c352802b973ce"
2020-01-16 01:47:05 +0000 [warn]: [test-prod] retry succeeded. chunk_id="59c37fad241ab300518b936e27200747"
2020-01-16 01:47:05 +0000 [warn]: [test-dev] retry succeeded. chunk_id="59c37fc11f7ab707ca5de72a88321cc2"
2020-01-16 01:47:05 +0000 [warn]: [test-dev] retry succeeded. chunk_id="59c37fb5adb70c06e649d8c108318c9b"
2020-01-16 01:47:15 +0000 [warn]: [kube-system] retry succeeded. chunk_id="59c37f63a9046e6dff7e9987729be66f"
However, Elasticsearch perceives each of the resent buffer chunks as unique and assigns them unique values for the _id fields during indexing. This is how message duplicates arise.
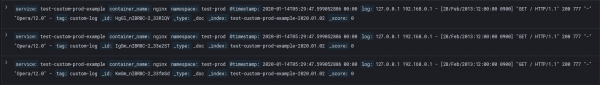
In Kibana, it looks like this:
Troubleshooting
There are several options for solving this problem. One of them is the mechanism for generating a unique hash for each document built into the fluent-plugin-elasticsearch plugin. By using this mechanism, ElasticSearch will recognize duplicates during the transmission stage and prevent document duplication. However, it is important to note that this solution addresses the symptom rather than the root cause of the timeout error, which is why we decided against its implementation.
We use a buffering plugin on the Fluentd output to prevent log loss in case of brief network issues or increased logging intensity. If ElasticSearch cannot instantly write a document to the index for any reason, the document is placed in a queue stored on the disk. Therefore, in our case, to eliminate the source of the problem that leads to the aforementioned error, it is necessary to set appropriate values for the buffering parameters, ensuring that the output buffer of Fluentd is sufficiently large and clears within the allotted time.
It's worth noting that the parameter values we will discuss below are specific to each particular case of using buffering in output plugins, as they depend on many factors: the intensity of log message recording by services, the performance of the disk system, the load on the network channel, and its bandwidth. Therefore, to obtain suitable but not excessive buffer settings for each individual case while avoiding prolonged blind trial and error, one can use the debug information that Fluentd writes to its log during operation to relatively quickly acquire correct values.
At the time the issue was recorded, the configuration appeared as follows:
 @type file
        path /var/log/fluentd-buffers/kubernetes.test.buffer
        flush_mode interval
        retry_type exponential_backoff
        flush_thread_count 2
        flush_interval 5s
        retry_forever
        retry_max_interval 30
        chunk_limit_size 8M
        queue_limit_length 8
        overflow_action block
In addressing the problem, the values of the following parameters were manually adjusted:
chunk_limit_size — the size of the chunks into which messages are divided in the buffer.
- flush_interval — the time interval after which the buffer is cleared.
- queue_limit_length — the maximum number of chunks allowed in the queue.
- request_timeout — the time allocated for the connection between Fluentd and ElasticSearch.
The total buffer size can be calculated by multiplying the queue_limit_length and chunk_limit_size parameters, which can be understood as "the maximum number of chunks in the queue, each of which has a defined size." If the buffer size is insufficient, the following warning will appear in the logs:
2020-01-21 10:22:57 +0000 [warn]: [test-prod] failed to write data into buffer by buffer overflow action=:blockThis means that the buffer is not being cleared in time, and data entering the filled buffer is blocked, which will lead to some log loss.
The buffer can be increased in two ways: by increasing either the size of each chunk in the queue or the number of chunks that can be in the queue.
If the chunk size chunk_limit_size is set to more than 32 megabytes, ElasticSearch will not accept it because the incoming packet will be too large. Therefore, if further buffer increase is necessary, it's better to increase the maximum queue length queue_limit_length.
When the buffer stops overflowing and only the timeout shortage message remains, you can start to increase the request_timeout parameter. However, setting the value above 20 seconds will cause the following warnings to appear in the Fluentd logs:
2020-01-21 09:55:33 +0000 [warn]: [test-dev] buffer flush took longer time than slow_flush_log_threshold: elapsed_time=20.85753920301795 slow_flush_log_threshold=20.0 plugin_id="postgresql-dev" This message does not affect system operation and indicates that the buffer clearing time took longer than the time set by the slow_flush_log_threshold parameter. This is debugging information, and we use it to fine-tune the request_timeout parameter.
The generalized tuning algorithm is as follows:
- Set the request_timeout value to be significantly larger than necessary (in the hundreds of seconds). During configuration, the main criterion for the correctness of this parameter's setting will be the disappearance of timeout shortage warnings.
- Wait for messages indicating that the slow_flush_log_threshold has been exceeded. In the warning text, the elapsed_time field will show the actual buffer clearing time.
- Set the request_timeout value higher than the maximum elapsed_time value obtained during the observation period. We calculate request_timeout as elapsed_time + 50%.
- To remove warnings about long buffer flushing from the log, you can increase the slow_flush_log_threshold value. We calculate this value as elapsed_time + 25%.
The final values of these parameters, as noted earlier, are obtained individually for each case. By following the algorithm outlined above, we can ensure the elimination of the error that leads to duplicate messages.
The table below shows how the number of errors per day leading to duplicate messages changes as we fine-tune the values of the parameters described above:
node-1
node-2
node-3
node-4
Before/After
Before/After
Before/After
Before/After
failed to flush the buffer
1749/2
694/2
47/0
1121/2
retry succeeded
410/2
205/1
24/0
241/2
It is also worth noting that the obtained settings may become outdated as the project grows and the number of logs increases. The primary sign of insufficient timeout is the return of messages about long buffer flushing in the Fluentd log, indicating the slow_flush_log_threshold has been exceeded. From this point, there is still a small buffer before exceeding the request_timeout parameter, so it is necessary to promptly respond to these messages and re-execute the process of fine-tuning the optimal settings described above.
Conclusion
Fine-tuning the Fluentd output buffer is one of the key stages in configuring the EFK stack, determining its stability and the correct placement of documents in indices. By following the described tuning algorithm, one can be sure that all logs will be written to the ElasticSearch index in the correct order, without duplicates or losses.
Also, read other articles in our blog:
Source: habr.com
